Patrick Ferris [index]
I'm a PhD student in the Energy and Environment Group at the Department of Computer Science, University of Cambridge.
I'm particularly interested in:
How technology can help tackle climate change (e.g. geocaml) and potential issues it creates.
The changing landscape of human rights as a consequence of technology and climate change.
Communicating science effectively to a wide audience (e.g. NI Forests) and improving diversity and inclusion in tech (see Outreachy).
Patrick Ferris' Weeklies [weeklies]
A collection of personal weekly(ish) updates about my work. If you want a more specific feed of OCaml-related work, please see OCaml weeklies. My personal weeklies will include the OCaml specific ones too.
Below are weeklies from 2026.
Weekly 2026 W43 [weekly-2026-w43]
- October 26, 2026
- Patrick Ferris
This week was a bit of a flop as I ended up coming down with something and was unable to work for about half of it. A shorter note this week due to this.
Paper Writing
- October 26, 2026
- Patrick Ferris
I had a productive conversation with Anil about the direction of the paper I am currently writing. Plenty of work to do with the deadline looming, but I am starting to think the framework we're building could have wider use than the applications I first thought of and that is somewhat exciting.
More on this during the week as I'm back to operational strength!
Forester 6.0
- October 26, 2026
- Patrick Ferris
A new release of Forester is imminent and with that comes upgrades and fixes to Graft. If you are reading this post then you are enjoying the delights of Forester 6.0 compiling artefacts from an in-the-works version of Graft.
The upgrade was mostly smooth, though some of my CSS was a bit broken, and it was easier to do a merge of the most important bits with the new Forester stylesheets.
Depending on the internals of Forester is a little tricky as it is first and foremost a CLI tool. The library APIs are likely to be less stable and are a bit of a moving target. The changes, however, were pleasantly small as far as I can tell, limited mostly to some changes in the reporting infrastructure and the strictness of all Forester codes needing a location (somewhat tricky as there is no one-to-one mapping from markdown/yaml/bibtex to these codes). For the latter case, we do our best and where possible try to map the generated codes back to the fragment of the source language Graft has transpiled.
Now that I am dog-fooding Graft and Forester, it will be easier to keep things working ahead of the next release.
Thanks to Kento and Jon for their work on improving Forester.
Outreachy
- October 26, 2026
- Patrick Ferris
I have lots of thoughts about Outreachy this year. The volume and quality of contributions is quite unlike anything I have seen before, in large part due to the current ease of accessibility and quality of LLMs. This does fly in the face of somewhat strong policies set out by Outreachy to help maintainers handle AI contributions.
Going forward, I imagine it will be difficult to balance pedagogical values with financial rewards given wide-spread AI usage (regardless of project-specific or organisational AI policies). Not something that quite exists, in the same way, say, for university undergraduate students.
I am still trying to find my feet in the middle of this. I have never felt quite this alone in the open-source software world.
Misc.
- October 26, 2026
- Patrick Ferris
Claudius Playground
- October 26, 2026
- Patrick Ferris
Michael spoke to me about some accessible ways to play around with his fantasy console library Claudius. At this point, I fancy myself a bit of an expert at shoving OCaml code into browsers, so I pulled together a rough and ready Claudius Playground (code is freely available on tangled). Happy coding!
Music
- October 26, 2026
- Patrick Ferris
I was able to go see the Mountain Goats before the start of last week, with Craig Finn supporting. I enjoyed Isaiah 45:23.
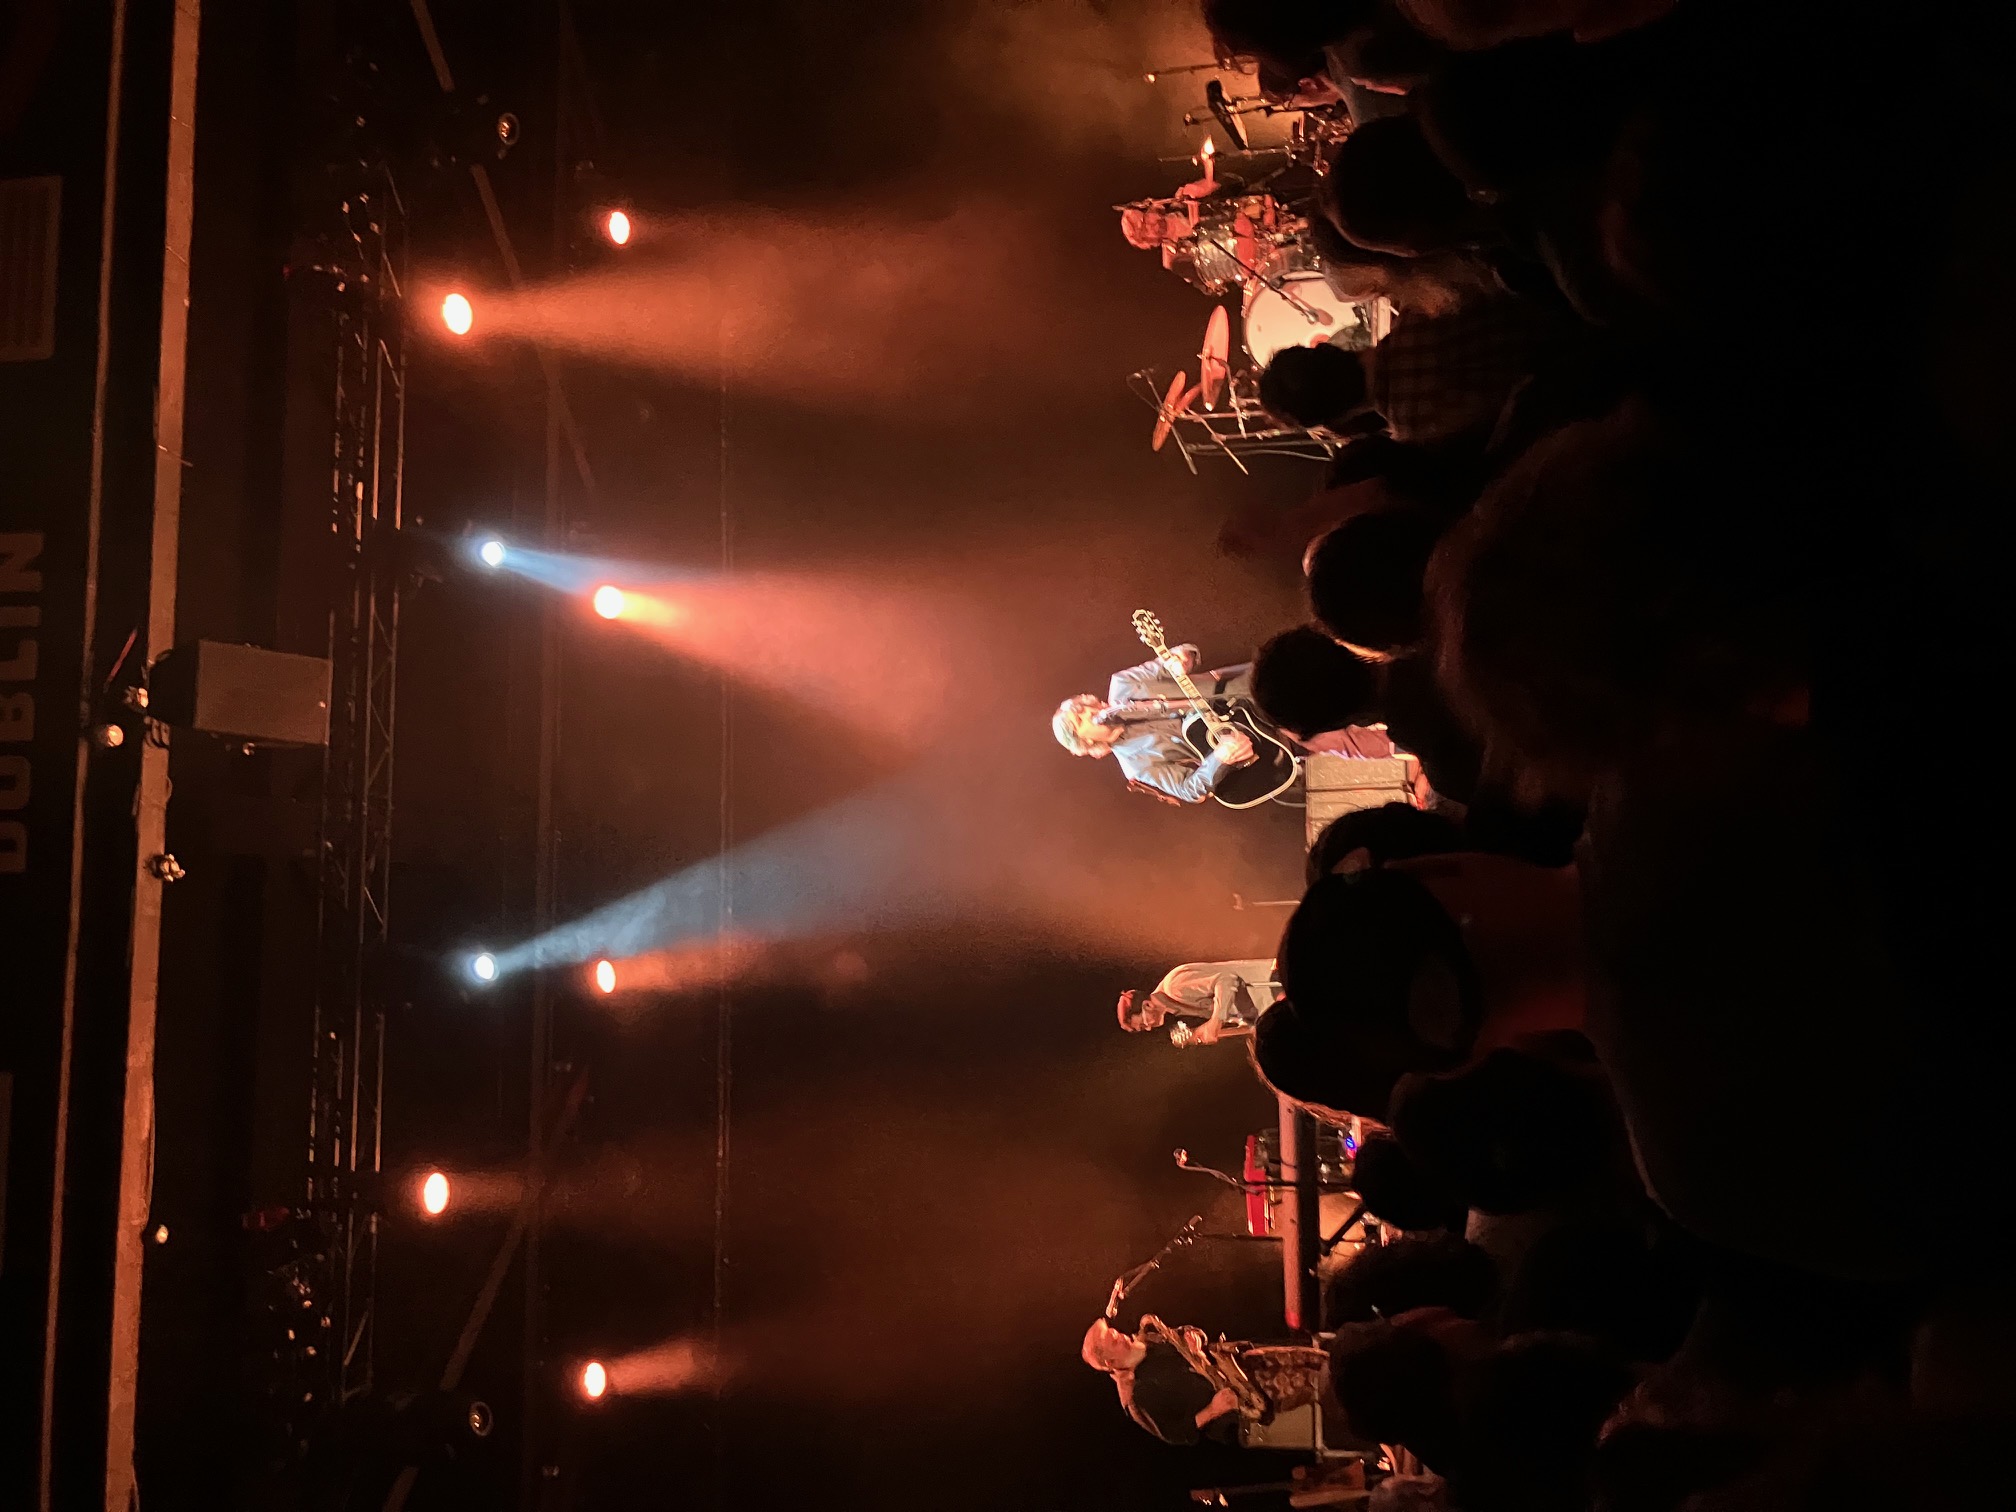
The Mountain Goats at Vicar St. Dublin, 2026-10-18.
Shells, SOOCon26 and Part IIs [weekly-2026-w41]
- October 9, 2026
- Patrick Ferris
Last week I gave a precise meaning to the "mergeability" of container images. The further I go down this rabbit hole, the less convinced I am of the exact benefits of such an approach. However, there are lots of off-shoots to explore as well, which all seem very worthwhile and might have better semantics than merging (e.g. incremental computation and provenance-tracking).
Uniform Representations [uniform-repr]
- October 12, 2026
- Patrick Ferris
Whilst working on things related to Merry and Shelter, I couldn't help but think how much easier parts of this problem would be if we were using Plan9 for one simple reason: the uniform access to OS resources. Half the battle on Linux is trying to trace or sandbox a process with respect to some set of OS resources (in an ideal world, all of them). Syscalls are perhaps the closest thing we have, but there isn't a one-to-one mapping between user actions and syscalls (e.g. opening a file using io_uring does not call open(2) or openat(2)).
I think there is often a trade-off here in terms of performance and simplicity. Plan9's 9P protocol was not exactly known for its performance. But, I still find myself, to use a phrase my colleague Ryan once used when explaining his use of emacs, comfy with uniform representations. Another example, a tree in Forester.
It is pleasant when these representations have a defined structure, even if the contents are more malleable. For instance, I don't want everything to be schema-less JSON. Forester trees have tags and that allows me to impose a schema in a structured way that doesn't lead to parsing errors. Similarly, 9P offers a simple protocol on which all things are built. As I understand it, the semantics are given by the interpretation of the file server that is resolved, but the protocol is uniform. Anyway, just some thoughts.
State of Open Conference 2026 -- Belfast [soocon2026-belfast]
- October 9, 2026
- Patrick Ferris
- https://stateofopencon.com/belfast-soocon26/
This week I was fortunate enough to attend (as a volunteer) SOOCon26 in Belfast in the Ulster Bank building, just opposite the City Hall. Thanks to Anil Madhavapeddy for linking me up with Amanda Brock to make it happen at the last hour.
If I can boil down the conference into a general topic it would be: how are large language models and coding agents impacting commercial, business-oriented open-source software. I found the conference's near-total focus on AI a little surprising and a little disappointing, but I suppose it reflects the current state of open source. For example, most, if not all, the working developers and business owners at this conference, for one reason or another, felt the need to relate their work to AI, both in their talks and in hallway conversations. Something I continue to struggle with, though, is that almost all references to "AI" pointed to large, expensive, closed frontier models (such as Claude, ChatGPT, Copilot and Gemini). That being said, there were talks on data (and AI) sovereignty as well as mentions of the increasingly capabale open models (e.g. Qwen).
I would like to add that the conference was essentially offline: no recordings or streaming. With that in mind, I want to respect the fact that most attendees and presenters could speak freely and candidly, so I will only focus on some of the higher level threads of discussion without attributing too much to any individual.
AI: Productivity
- October 9, 2026
- Patrick Ferris
The morning focused mainly on the question: what is a software developer's job in 2026? This culminated in a panel discussion on "building trust in AI". Already, I would say the conference's mind was made up, AI is here to stay; it is just a tool; we should learn how to hold it properly. I think, in part, this was mainly due to the group of speakers who were all, more or less, executives within for-profit businesses that incorporate open source in some way: Github, BIMP.ai and Budibase. The only exception was a speaker from the Institute of Directors. I think this gave the morning session a commercial flavour which suggested the tech industry's large-scale adoption of AI tooling, a position I'm not sure is as common among, or available to, smaller open-source maintainers.
One stream of thought that was popular was arguing that languages like C, where it is easy to introduce memory bugs and vulnerabilities, are on the way out. Copilot's runtime rewrite in Rust was championed as a success story for the kinds of productivity that can be unlocked for highly-skilled developers. A pinch of salt is needed though, as Microsoft did sponsor the event. My own thoughts, however, are that there are quite a few success stories we can learn from where software was translated from one programming language to another using an LLM. Migration seems well-defined and well-scoped, often with large, pre-existing test suites that can easily guide a tool towards some form of correctness. In the same breath, it is not necessarily that straightforward, for example, see some lobste.rs commentary on the Bun rewrite in Rust.
Another undercurrent throughout the morning talks was how LLMs could free up developers to actively engage with users. Some quotes from the talks included "experiment with empathy" and "AI doesn't write the story". On the surface, this seems like a reasonable argument. But, shouldn't these large teams of people have already been thinking about their users, with or without AI? I'm also not convinced this free time will appear. When the metric of success is at least proportional to the rate of new features, it would seem that a tool, like an LLM, would only crank out more widgets rather than better widgets.
A final worrying conversation from the panel, discussed the fact that companies are not hiring graduates. This was self-evident from a few other people I met in and around the conference: computer science graduates still looking for jobs.
AI: Community, Data Centres and Vulnerabilities
- October 9, 2026
- Patrick Ferris
The post-lunch session included a talk about the future of community open source, a talk about AI data centres and finally a panel about the "vulnpocalypse".
The first talk focused on the realities of doing community open source and how, in effect, AI and LLMs are not (yet) a part of our shared open culture, citing large, anti-AI open-source projects, some which have banned AI contributions (e.g. NLNet Labs, Codemirror) and pro-AI projects which have closed contributions (e.g. Ladybird). Of course, open source never meant the right to contribute, but it still signals a, perhaps, worrying shift in open-source, cultural norms. An arXiv paper collected some AI policies on popular repositories which is worth a skim.
Another topic in the talk was the "time to open". The speaker argued that it was now possible to completely reverse engineer closed-source products and tools in as little as 48 hours. This could lead to more open source business models, as closed models are no longer viable. The speaker suggested that the open-source community around a project is now more important than the code itself. I think I fall somewhere closer to believing that they are both important. I worry about the proliferation of agentically-managed software stacks which companies and individuals use with little incentive to upstream patches back to the community (or release their new code for the community). This kind of isolationism seems more likely given the ability to create your own implementation of any piece of software.
Data Centres
- October 9, 2026
- Patrick Ferris
The talk on hyperscalar data centres presented some great work from the folks at Action to Protect Rural Scotland (APRS). With some serious energy projections:
This gives an estimated around 7,306 MW currently in the planning system or in pre-application consultation. Peak winter electricity demand in Scotland is just over 4,000 MW.
It seemed like the feeling in the room was that these data centres are inevitable, in spite of these jarring numbers; and that somewhere down the line, the ends will be just so good, that the means will be justified.
It seems, once again, I must reach for Pete Seeger.
Perhaps the biggest change will come when we don't have to change much at all When maniacs holler "grow, grow, grow, grow!"; we can choose to be small.
Vulnerabilities
- October 9, 2026
- Patrick Ferris
I don't think this needs too much explaining, but visit Daniel Stenberg's mastodon feed and that will catch you up. Edit: I wanted to also add a more recent post from Daniel highlighting the other work of the core curl team.
Conclusion of sorts
- October 9, 2026
- Patrick Ferris
Unfortunately, I missed a good portion of the final session as I was helping clear up. The talks were: "The cost of Sovereignty", "Knowledge Graphs for Digital Transformation" and "You can't download trust".
I managed to have a good chat with Phil Weir, director of Flax and Teal, about some of their work including Alizarin, a tool for working with knowledge graphs and Arches data. It was refreshing to hear about the details of an actual project someone was building.
Ultimately, I would say the day left me disheartened for the immediate future of (open-source) software. What I found most unsettling about SOOCon is what I find unsettling about the tech industry at large. It would seem that the industry is leaving new graduates in the lurch. Additionally, environmental concerns are falling somewhere (far?) below commerical concerns.
I'm also anxious that open source's ethos is being eclipsed by the need for companies (and individual employees) to demonstrate their relevance in an AI-focused economy, and that that performance of relevance is really about integrating, into whatever you're doing, the products coming out of a few powerful companies, which are not invested in the values which make open source make sense.
I think conferences like State of Open are important, and we need more conversations from all kinds of open-source community members. I'd like to see more talks from students, sole maintainers of highly depended-on software, folks from other non-profit-driven open-source initiatives like Outreachy or the Processing Foundation (these are just examples I know). I recognise that, perhaps, SOOCon26 Belfast was suffering from being in Belfast, hardly the most connected metropolis in the world... but it is the home of The Big Fish. I'm excited to hopefully see it return in the years to come.
My friends, Maddie and Emma, enjoying the splendour of Belfast!
Thanks to Meredith, my partner, for helping me edit this and form some much more coherent ideas.
Part II Projects
- October 9, 2026
- Patrick Ferris
After some super-human administration by Anil Madhavapeddy, I have closed this week with three part II projects to supervise.
An Embedded DSL for Querying OpenStreetMap [part-ii-edsl-osm]
- Matthew Occleshaw
This project, originally conceived by Anil Madhavapeddy, hopes to make it easier to answer questions like "What is the safest route to Pembroke College from Cambridge train station?". Here, "safest", can have lots of meanings: the best lit road, a route with tactile paving or accessible pedestrian signals etc.
In addition to this, we may wish to provide suggestions for how to improve the current folksonomy of information OSM stores.
From OCaml to Graphics Shader Languages [part-ii-shaders]
- Rohan Wadhawan
This project wants to reuse OCaml's typechecker to provide a safe way to create graphics shaders. As an extension, a ppx rewriter will provide a translation layer from OCaml to the embedded DSL making it possible to write shaders in a subset of the OCaml language.
When interacting with the GPU for graphics programming, parts of the rendering pipeline are written as standalone shader programs. The standard method of using these is to store the shader source code as a string, which is then compiled at runtime by the GPU driver. This is not a performance issue, as shader programs are usually small enough that compilation time is negligible. However, it does mean simple syntax errors or incorrect types, which would normally be caught at compilation, won’t manifest until the entire program is run.
I propose a new library, Shaders_of_ocaml, allowing for shader programs to be written inline as native OCaml, which is then compiled to shader code strings to be passed to the existing graphics libraries. This would allow the OCaml compiler to provide type checking for every shader written.
-- From Rohan's Proposal
Ripple: An OCaml Library for Incremental Computation [part-ii-incr]
- Boris Hall
Following the work of Adaptive Functional Programming and Implicit self-adjusting computation, this project will build an incremental computation engine in OCaml alongside an expressive combinator library for build such computations. As an extension, a small DSL will be built that makes use of the engine to build an implicitly incremental programming language.
The core of this project is to implement an eDSL and a runtime in OCaml for self-adjusting computation. I also propose a new TDT which allows for generic monoidal folds over modifiable sequences: the library will include a native foldMap primitive that allows performant reduction over a modifiable sequence of modifiable values for any general monoid, giving logarithmic updates with a small trace. I will then compare foldMap to the generic fold implemented in plain SAC.
-- From Boris' Proposal
Ppxlib
- October 9, 2026
- Patrick Ferris
Just a quick footnote about [Ppxlib]: I opened a PR tomerge multiple instances of a deriver. I threw together this OCaml script for checking implementation and interface files. Running it on Forester, it picked up two instances which can be avoided.
open Ppxlib

let attr_compare (a1 : attribute) (a2 : attribute) =
  String.compare a1.attr_name.txt a2.attr_name.txt

let has_derivings_recursively =
  object
    inherit [bool] Ast_traverse.fold as super

    method! structure_item s acc =
      match s.pstr_desc with
      | Pstr_type (Recursive, (_ :: _ as tds)) ->
        let attributes =
          List.fold_left (fun acc td -> td.ptype_attributes @ acc) [] tds
        in
        let uniq = List.sort_uniq attr_compare attributes in
        List.length attributes <> List.length uniq || super#structure_item s acc
      | _ -> acc

    method! signature_item s acc =
      match s.psig_desc with
      | Psig_type (Recursive, (_ :: _ as tds)) ->
        let attributes =
          List.fold_left (fun acc td -> td.ptype_attributes @ acc) [] tds
        in
        let uniq = List.sort_uniq attr_compare attributes in
        List.length attributes <> List.length uniq || super#signature_item s acc
      | _ -> acc
  end

let main f =
  let is_ml = Filename.extension f = ".ml" in
  let is_mli = Filename.extension f = ".mli" in
  let kind =
    if is_ml then Some Ppxlib_private.Utils.Kind.Impl
    else if is_mli then Some Intf
    else None
  in
  match kind with
  | None -> Format.eprintf "Skipping %s@,%!" f
  | Some kind -> (
    match Driver.load_input ~kind ~relocate:false ~input_name:f f with
    | Error (e, _) ->
      Format.eprintf "Input err %a: %s" Location.print (Location.Error.get_location e) (Location.Error.message e);
      exit 127
    | Ok (_, _, Impl s) ->
      if has_derivings_recursively#structure s false then
        Format.printf ">>> Maybe fix: %s@,%!" f
      else ()
    | Ok (_, _, Intf s) ->
      if has_derivings_recursively#signature s false then
        Format.printf ">>> Maybe fix: %s@,%!" f
      else ())
Note, that given the implementation of attr_compare, this will be an overapproximation.
Weekly 2026 w39 [weekly-2026-w39]
- September 30, 2026
- Patrick Ferris
Shells
- September 30, 2026
- Patrick Ferris
Work on the msh paper continued this week. One interesting result (for an appendix) was seeing what were the most commonly used commands in the Dockerfile dataset:
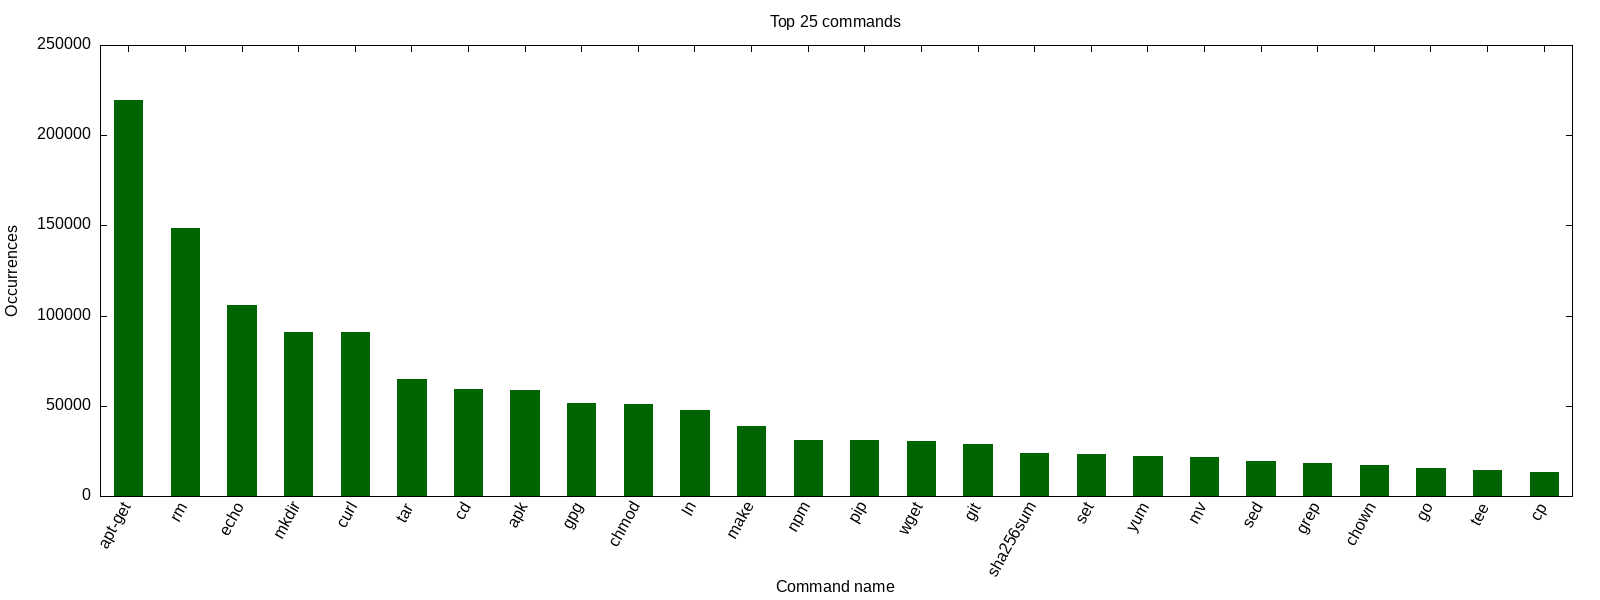
Which again, leads to some notion of overkill in terms of using a shell as the means to create container images when all we do is move some files around and install packages! I'm wondering if we're missing a real opportunity to streamline this process via something like the package calculus -- a package manager-agnostic means for declaring your dependencies.
Embed that as a programmable notion in your container image language alongside a container image-aware HTTP GET tool (to replace a vast majority of curl calls) and a handful of busybox commands, and you are left with (nearly) the raw shell only being used for the long tail of domain-specific things (e.g. invoking a build system).
Joy in old documents
- September 30, 2026
- Patrick Ferris
I'll talk about the joy I found in reading some historical bits and bobs tracking down information about shells, containers and operating systems more generally.
Part of this archaeological effort was trying to find when CHROOT was introduced into UNIX. Various online tools, including AI summaries, point to UNIX v7 but the system call is not obviously defined there. A bit more digging reveals it is listed under CHDIR(2) and not on its own.
Anyway, flicking through the manual was somewhat of a joy. The preface reads:
This new form of the Seventh Edition manual attests to the gratifying popularity of the UNIX Operating System. Delivered with no support and with an amateurishly published manual, this elegant and productive system has nevertheless earned worldwide respect, sometimes bordering on adulation...
Thousands of users today work from faint reproductions of reproductions of the original manual, whose ragged pages dangle and slide out of beat-up ring binders...
This bordering-on-poetic prose reminds me of some passages written for the MULTICS manual too (which I have talked about before).
All to say, I'm often thinking about the importance of writing these days and injecting some personality into it.
Part II Discussions
- September 30, 2026
- Patrick Ferris
I am hopefully going to supervise a part II project this year either on a fun ergonomic frontend to eBPF programs or a new spin on the geospatial DSL. More to follow once things are finalised.
Upstreaming Forester Pretty-printer
- September 30, 2026
- Patrick Ferris
I finally got around to upstreaming the Forester pretty-printing API I have been using in Graft. This allows you to print, hopefully, syntactically correct Forester code directly from the AST (a Code.t in forester parlance).
Happily, this all took place on tangled. It will be nice to keep this updated alongside Forester and point Graft to it. It feels like many people are moving away from a community-oriented model of software development, instead building a hybrid bazaarian cathedral monorepo powered by AI. I'm not here to really say what is right and what is wrong, but it seems to me that the sense of community is fragmenting and undue stress is being placed on many maintainers who no longer enjoy their job.
New release of ppx_deriving_ [ppx_deriving_yamlx-release]
- September 30, 2026
- Patrick Ferris
Raphael has proposed a new yamlx backend for ppx_deriving_yaml. It seems Ahrefs have been using his patch. I rejigged that PR to parameterise ppx_deriving_yaml over a small set of constructors and patterns so that the core codec logic could be reused.
I am fairly pleased with this abstraction. It allows any data format that supports objects and list to reuse the codec. For example, it would be trivial now to add a ppx_deriving_cbor.
Weeknotes 2026-w38 [weekly-2026-w38]
- September 18, 2026
- Patrick Ferris
Msh log 2026-38 [msh-log-2026-w38]
- September 18, 2026
- Patrick Ferris
After running some Dockerfile analysis last week, I have focused on formalising some operational semantics for the core POSIX-shell inspired language for a "mergeable shell".
This work borrows from Smoosh, but extends the semantics to include reasoning about namespaces, filesystems and effects.
For instance, here are two inference rules for field splitting and parameter substitution. Here, \sigma tracks the shell state, \phi is the filesystem and \tau tracks the side effects.
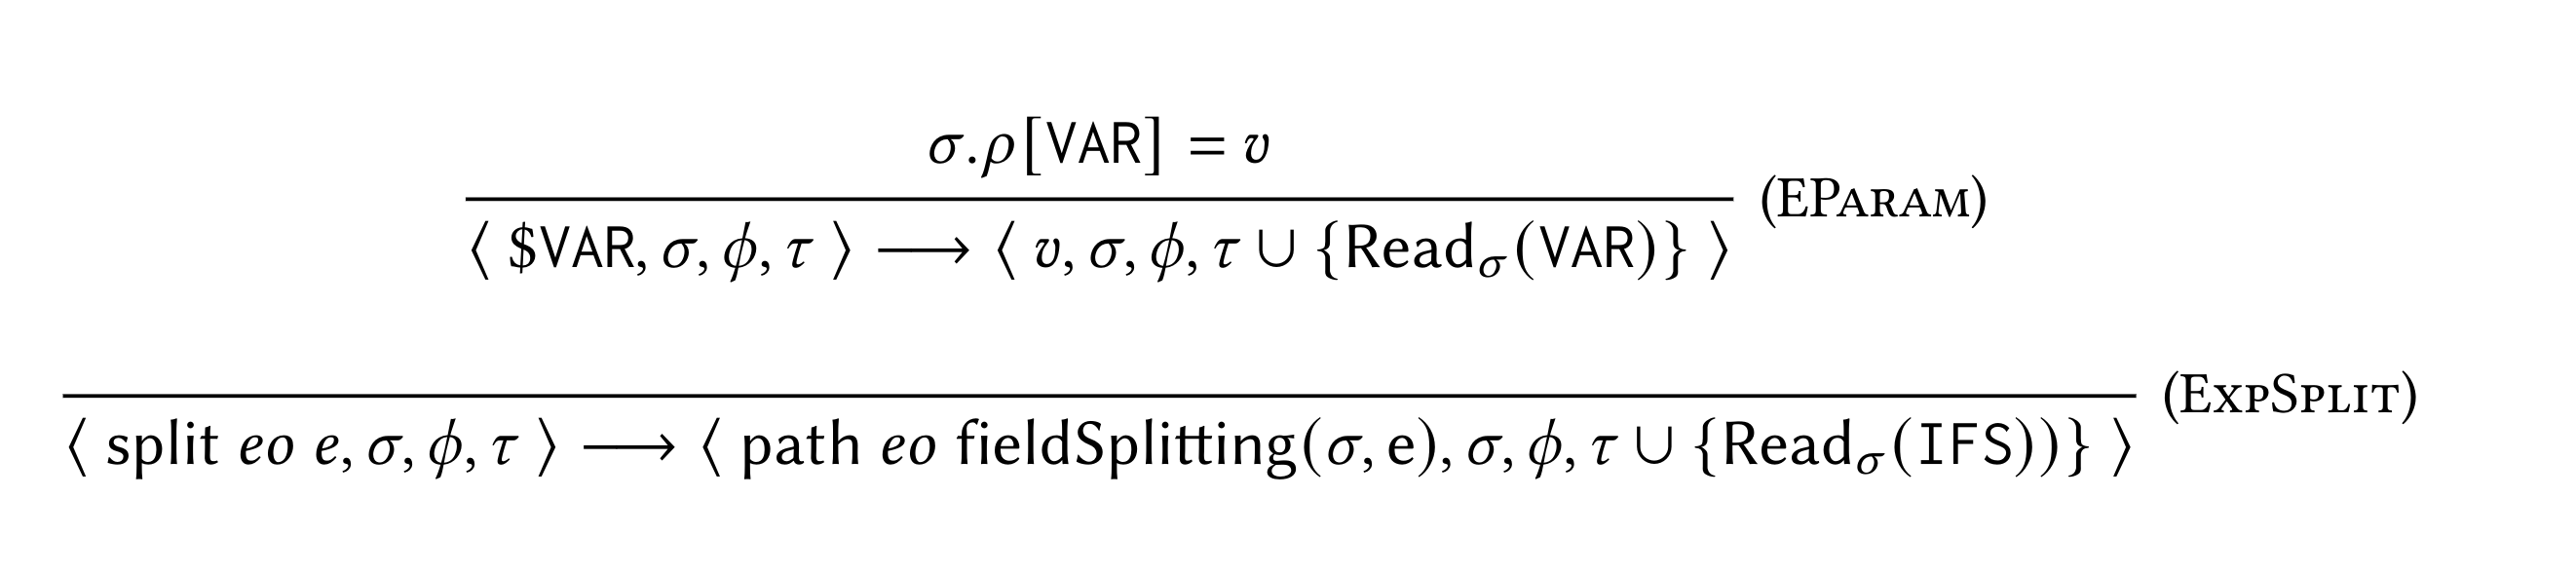
There are lots of interesting examples of this, like assignment during parameter substitution (e.g. ${FOO:=BAR}) or the side effects that take place during program name resolution.
OCaml Maintenance [ocaml-maintenance-2026-w38]
- September 18, 2026
- Patrick Ferris
A mixture of work in ppxlib and geocaml.
Ppxlib migration woes
- September 18, 2026
- Patrick Ferris
Ppxlib continues to prove itself as a tricky library to maintain. This week, a report came in from David about package_type attributes being dropped. These are new attributes that are attached to package expressions which simply did not have them before.
The solution here was to store these attributes on parent nodes (e.g. the core_type a Ptyp_pack might be a part of) when migrating from 5.4 to 5.3 alongside a ppxlib.migration attribute to distinguish them from the core_type's attributes. When migrating back up we then re-split the attributes.
David also landed a new syntax feature arriving in OCaml 5.6 that adds upstream support for expression "holes", something Merlin supports. It is now possible to replace any OCaml expression with _, for example, let x = 1 + _.
This needed explicit ppxlib support which, thankfully, was relatively straightforward as hole expressions do not have a lot of associated metadata or arguments.
Our benchmarking infrastructure is also back on its feet.
Thanks to Nathan for all the reviewing.
rtree.0.3.0 release [rtree-0-3-0]
- September 18, 2026
- Patrick Ferris
I cut a release of ocaml-rtree that removes the repr dependency. See the relevant discuss post.
This was a feature that Michael had asked for when building laserver. I took the time to open a PR to laserver to use rtree.0.3.0 which does simplify the code.
I wanted to ensure the library was still working, so I grabbed some of the LAS data for Lough Neagh, provided by OpenDataNI for 2017. After converting it to cloud-optimised point cloud (COPC) data via pdal (yes, two different "cloud" meanings) I managed to view the south-east portion of Lough Neagh.
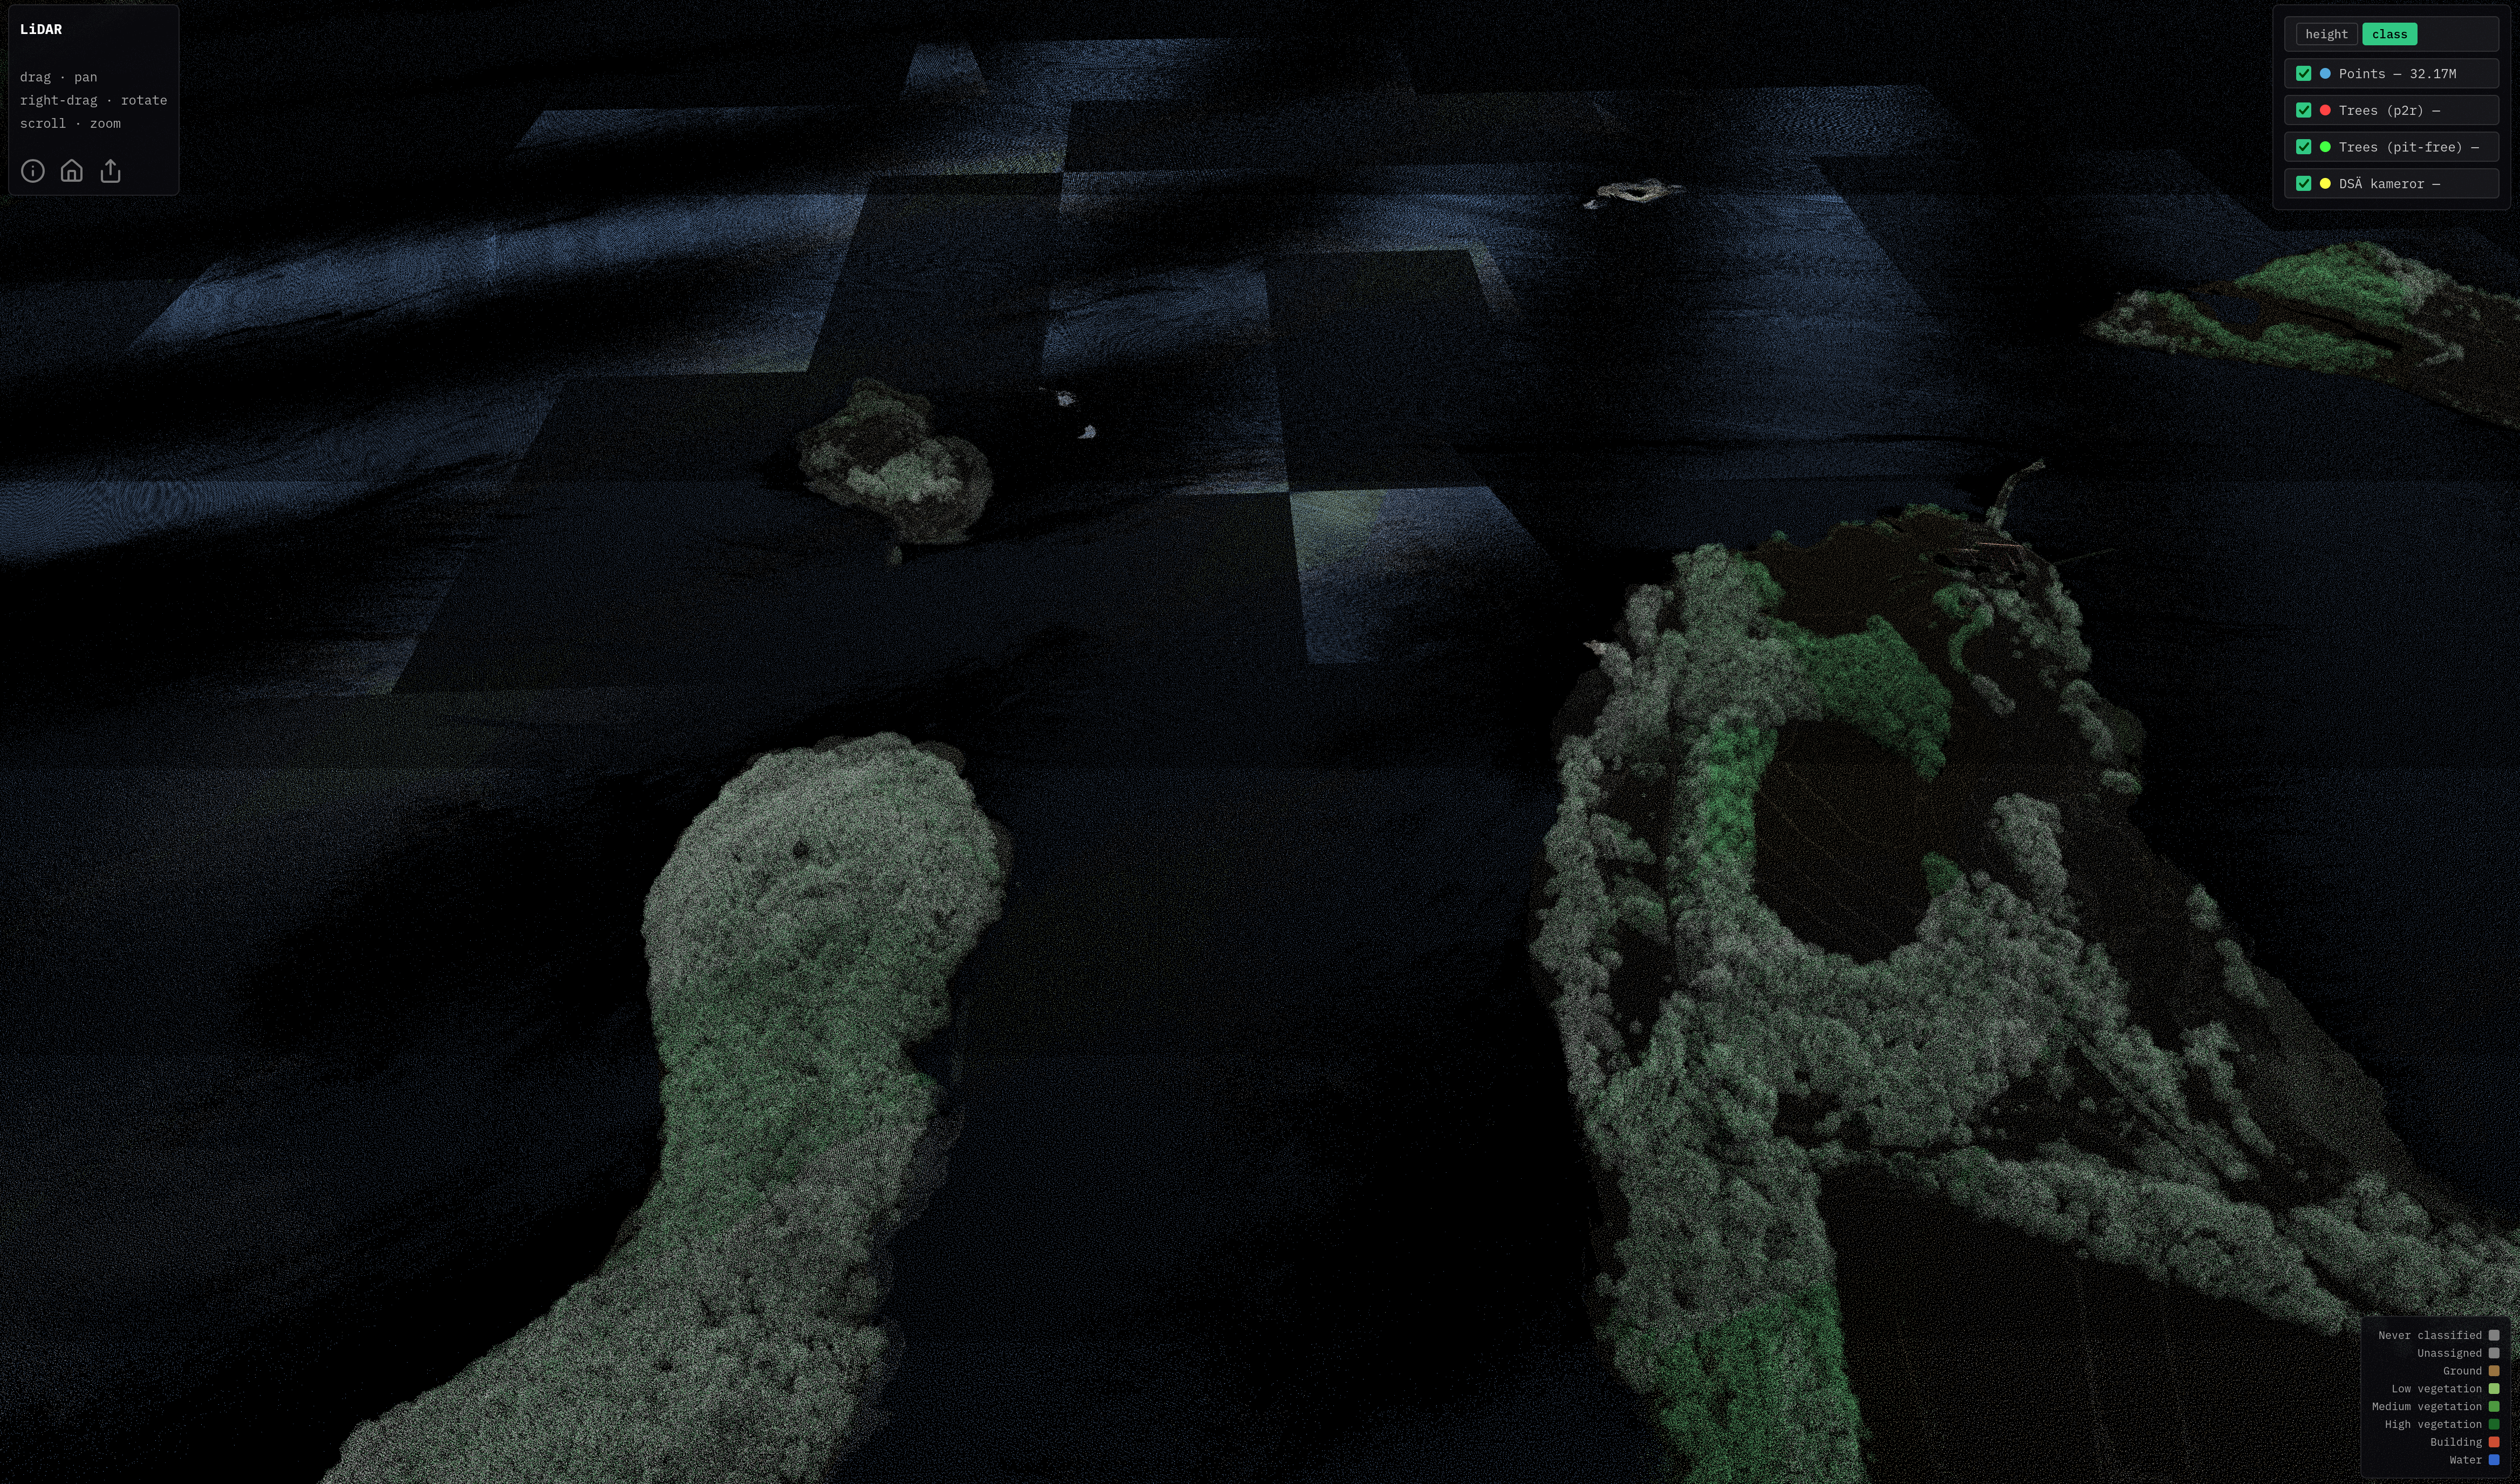
This is overlooking the Lough Neagh Discovery Centre and Croaghan Island.
Outreachy
- September 18, 2026
- Patrick Ferris
After securing funding for this Outreachy round, I submitted an ocaml-tiff project. A year ago, we had an intern successfully add write support to the library.
This time, I hope to continue building out the library with an intern who is interested in learning OCaml, functional programming and geospatial data formats! One subgoal of the internship will be to create a tiffinfo-like command line tool that is distributed as part of the library. I also hope to add more compression algorithm support and iron out some API kinks.
Analysing some Dockerfiles [weekly-2026-w37]
- September 12, 2026
- Patrick Ferris
After spending a few weeks thinking about the semantics of POSIX shells, this week saw me analysing lots of Dockerfiles looking for some evidence for how they are being used. It also saw environment variables landing in Eio thanks to Thomas and Anil. We also had some issues in ppxlib migrations.
Dockerfile Analysis [msh-dockerfile-analysis]
- September 12, 2026
- Patrick Ferris
Part of my research at the moment is thinking about how shells are used. What commands are run? What constructs are used (e.g. redirections, compound commands...)? Dockerfiles are a defacto standard means for building container images and for the most part they are a shell with weird semantics and some meta-commands (sounds familiar!).
I had some assumptions about the kinds of shell commands people use (myself included) when writing Dockerfiles. For example, making use of AND-lists for grouping commands in RUN instructions. But I had no evidence to back this up. So I ran some analysis over the dataset from this paper from Henkel et al..
Total Dockerfiles: 218_253 (errors: 808)
Total Docker Instructions: 2_729_118
Total RUN instructions: 657_909 (errors: 4_847)
========

Count (Windows Dockerfiles): 841 / 218_253
Count (ENV commands): 268_898 / 2_729_118
Count (COPY commands): 165_968 / 2_729_118
Count (ADD commands): 86_552 / 2_729_118
Count (WORKDIR commands): 104_112 / 2_729_118
Count (using at least one &&): 267_113 / 657_909
Count (uses of exec): 25 / 657_909
Count (system pkg manager: [apt, apt-get, dnf, apk, pacman, nix, brew, yum]): 192_092 / 657_909
Count (internet retrievers: [curl, wget]): 95_433 / 657_909
Count (might use python): 9_082 / 657_909
Counts:
[(rm, 169_386), (echo, 113_768), (mkdir, 100_924), (cd, 74_904),
 (chmod, 55_998), (set, 25_738), (mv, 24_034), (sed, 21_232),
 (chown, 18_610), (grep, 16_604), (cp, 15_637), (export, 13_154),
 ([, 10_411), (touch, 3_152), (exit, 2_288), (printf, 2_275), (awk, 2_010),
 (., 1_077), (test, 1_004), (source, 904), (pwd, 199), (unset, 105),
 (diff, 40), (trap, 2)]
I think there's some evidence here to support some assumptions I already had:
A significant proportion of
RUNinstructions in Dockerfiles invoke package managers.A significant proportion of
RUNinstructions invokecurlorwget.There is something rather Zipfian about how shell built-in utilities are used.
There is limited used of
exec(and therefore limited use of opening file descriptors directly via the shell, as opposed to a command running in a subprocess).A lot of time is spent changing directories, either temporally (via
cdin aRUNinstruction, or by usingWORKDIR).Lots of
ENVsetting.
Parsing Dockerfiles
- September 12, 2026
- Patrick Ferris
For reasons that are probably quite clear, whenever I end up doing a small task like this, I always reach for OCaml to do it. The idea is that I'm invested in that community and hope to see it thrive. And if that means contributing some fixes, libraries or advice along the way, it seems to me that that is time well spent.
When I started, I assumed ocaml-dockerfile had support for parsing files; it turns out it doesn't, but I found Thomas G.'s port that does. So I took it for a spin and the results were less than I had hoped for. Of the 219,061 Dockerfiles, 97,123 were not parseable! After a series of commits I managed to get that number down to 808.
Eio process environment
- September 12, 2026
- Patrick Ferris
What started out seemingly straightforward (add a capability-based API to Eio for accessing environment variables) ended up being a more nuanced discussion about what the best API would be. In the end, Thomas added an Eio.Process.Env API to manipulate soon-to-be opaque environments. This paved the way for the portable environment support.
The API Eio exposes is readonly so we do not have to worry too much about race conditions (even though users are free to Unix.putenv).
One quirk of this work was reaffirming something I had already stumbled across in Merry. Accessing and searching large environments has a cost! For my rather large Nix environment, we can see the slowdown pretty clearly.
                  name,   major-allocated,   minor-allocated,   monotonic-clock
        get_env/all 10,        346.619865,      38577.227215,      29248.828738
        get_env/all 50,       1677.003302,     181788.755923,     138307.102538
       get_env/all 100,       3323.770915,     361218.802888,     274768.577259
   get_env/all_once 10,        121.955078,      14694.900546,      11652.096583
   get_env/all_once 50,        563.133065,      61951.683658,      48161.605588
  get_env/all_once 100,       1113.238600,     121431.915770,      93960.646400
     get_env/direct 10,          0.000000,          0.000000,        974.649587
     get_env/direct 50,          0.000000,          0.000000,       4369.486360
    get_env/direct 100,          0.000000,          0.000000,       8753.393503
The all benchmark calls environment every time and then finds a variable using Eio.Process.Env.get_opt, all_once calls environment once and then Eio.Process.Env.get_opt every time and direct uses the Eio.Process.get_opt directly every time. The differences are a lot less stark when the environment is pretty small.
Ppxlib Migrations
- September 12, 2026
- Patrick Ferris
Thankfully, ppxlib has been mostly stable for a number of months. In part, thanks to the diligent efforts of Nathan. However, David uncovered some unpleasant bugs in the migration code for some new 5.4 AST features. Unfortunately, it is only for attributes which are a source of pain for ppxlib. I spent some time reviewing the fixes, and it looks like we still need some more work to ensure the attributes attached to package types roundtrip cleanly.
Misc.
- September 12, 2026
- Patrick Ferris
Some other work I recorded separately and include here for the eager reader.
OCaml Roundup: August 2026 [ocaml-roundup-august-2026]
- July 12, 2026
- Patrick Ferris
Much of August was spent thinking about POSIX shell semantics, and in particular extending notions from smoosh to include side effects (and maybe concurrency). This is still nascent work, but some ideas and flavours are described below.
Merging Shells
- July 12, 2026
- Patrick Ferris
The work came from wanting to merge two shell sessions into one. Setting aside the practicalities of an implementation, it makes sense to start first theoretically. When can I merge two shell executions, and when can I not?
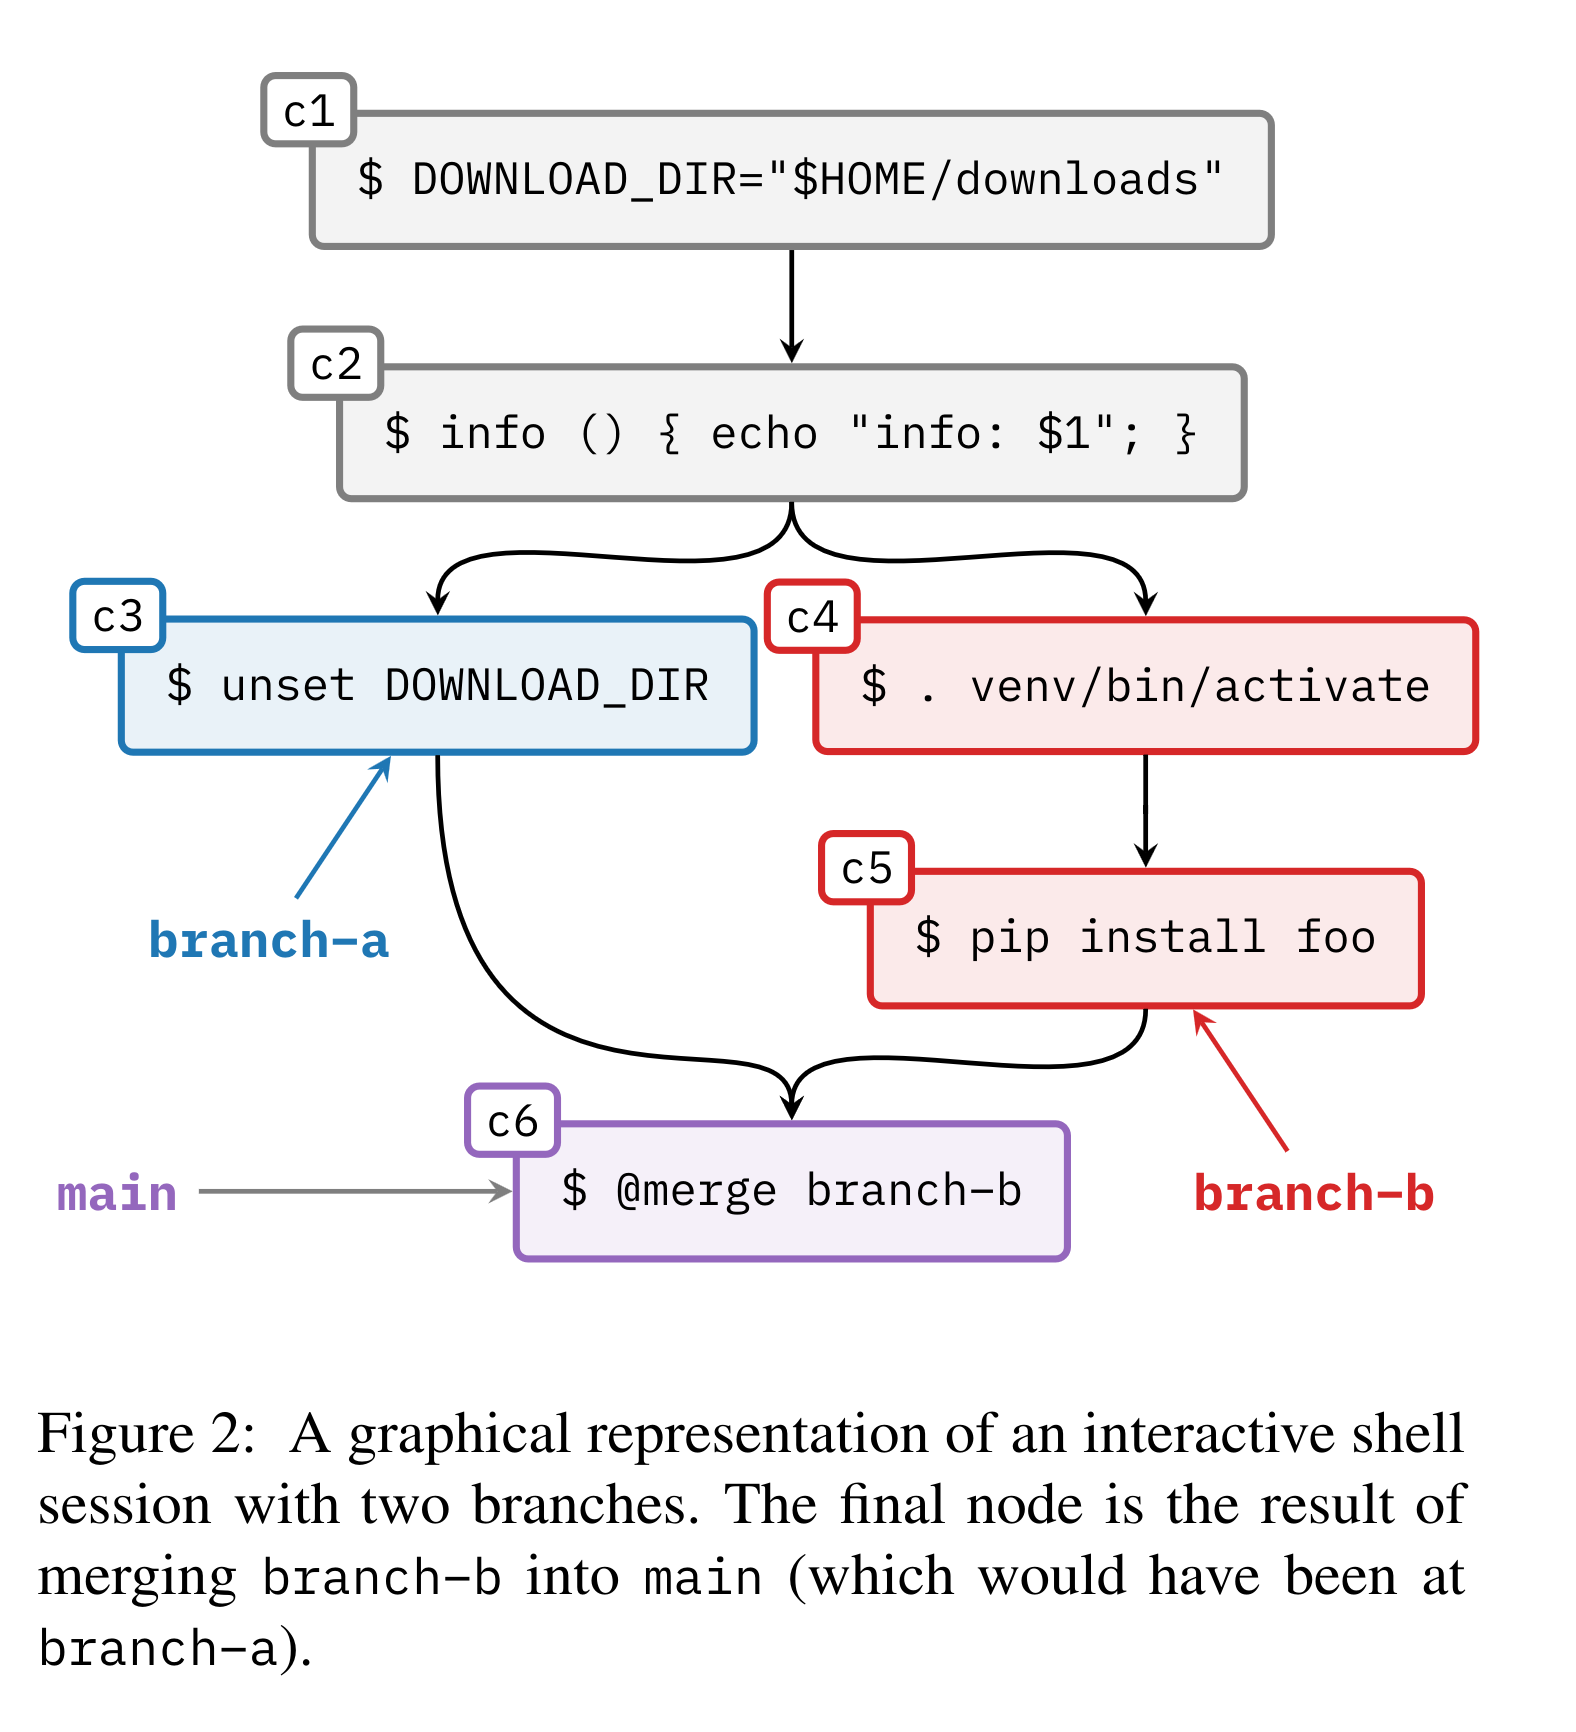
It would be nice to think of unset DOWNLOAD_DIR as a function. This function takes the shell state and the operating state as arguments and returns a modified shell state and an "unmodified" operating system state (at least for our purposes). Meanwhile, branch-b may have a lot more side effects, but when focusing on the environment only we can see in a sense the two branches are conflict free. Well, sorta. We also need to ensure we do not also read DOWNLOAD_DIR in branch-b if we intend to remove it in their merge.
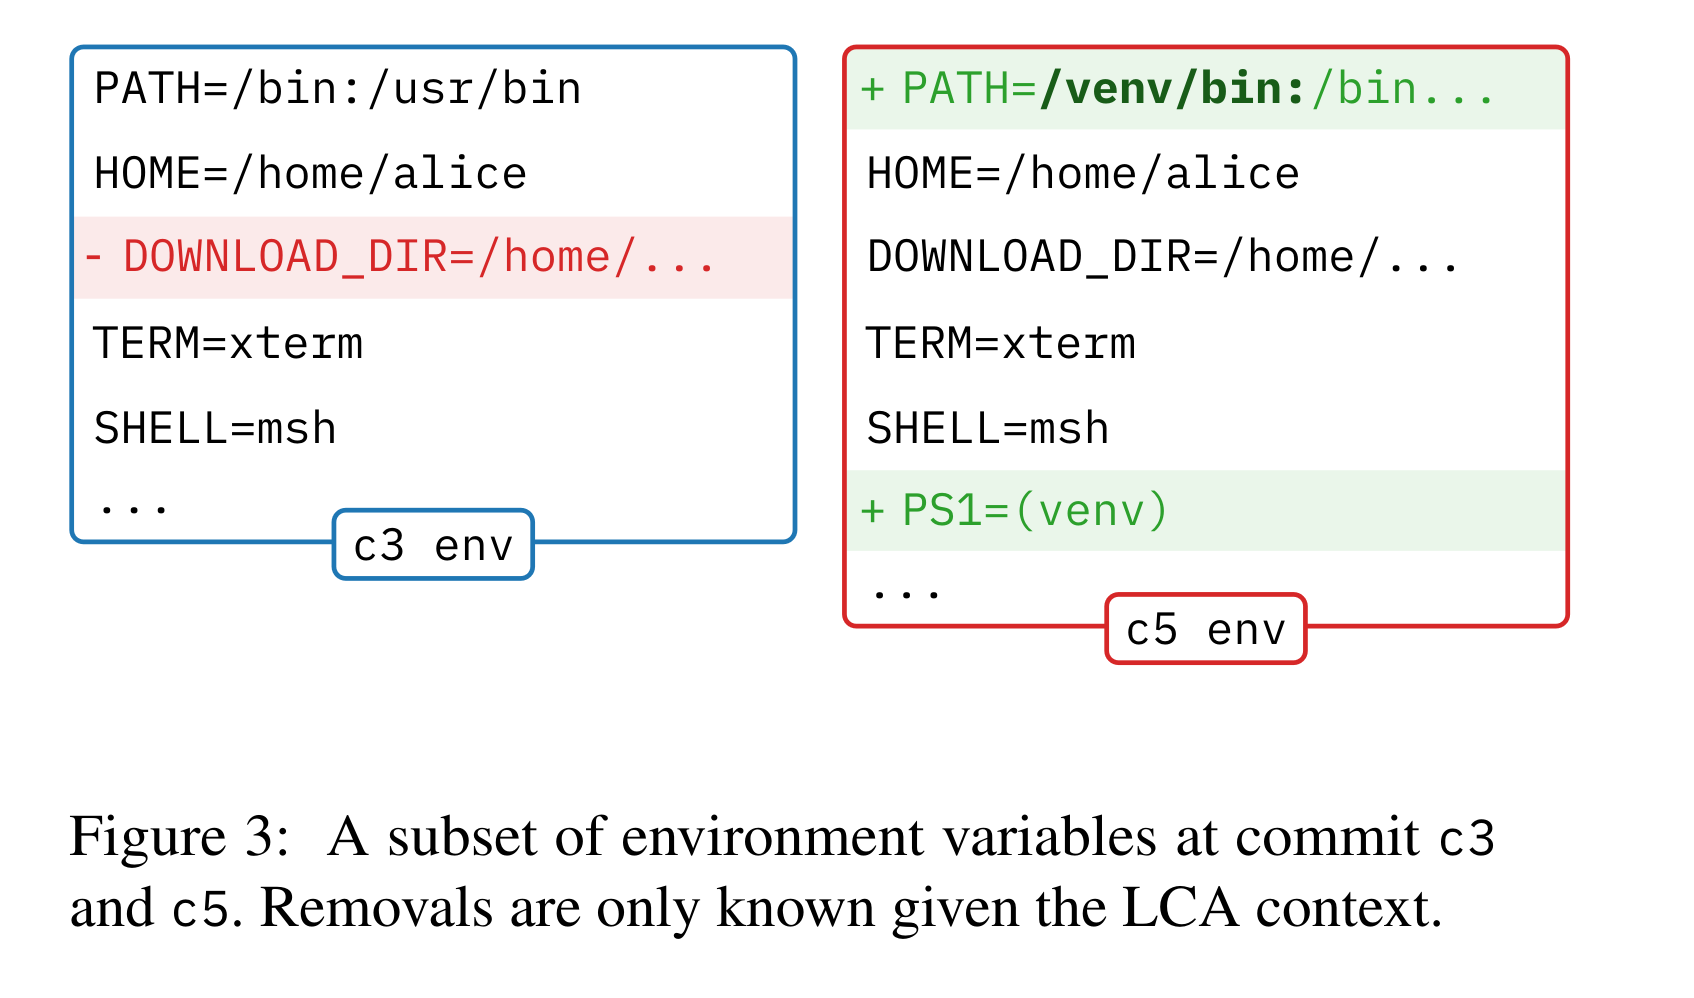
This work, in part, is borrowing ideas from MRDTs and can reuse void processes to help reason about when side effects can occur, as well as open-trace (which is now becoming os-trace).
I hope to continue this work, see my latest weekly for more on this.
Eio in the browser
- July 12, 2026
- Patrick Ferris
I spent some time carving out Eio_browser into a standalone library, something I depend on for Merry to work in the browser.
Eio_browser [eio_browser]
- September 12, 2026
- Patrick Ferris
- https://git.sirref.org/eio_browser
Eio_browser is a backend for Eio that works in the browser. It reuses work I started at Tarides that picked up some momentum but has since been a little dormant.
Crucially, it provides a functional standard environment like Eio_main or any of the OS-specific backends.
module Stdenv : sig
  type base =
    < stdout : Eio_unix.sink_ty r
    ; stderr : Eio_unix.sink_ty r
    ; clock : float Eio.Time.clock_ty r
    ; mono_clock : Eio.Time.Mono.ty r
    ; secure_random : Eio.Flow.source_ty r
    ; debug : Eio.Debug.t
    ; backend_id : string >
end

val run : (Stdenv.base -> unit) -> unit
(** [run fn] runs [fn] passing it the {! Stdenv.base} environment.
    See {! Backend.run} for more information about how effects are handled.*)
Browsher and Namespaces [weekly-2026-w33]
- August 17, 2026
- Patrick Ferris
The work presented constitutes a good bit more than a weeks worth of work. That being said, let's dive in.
Browsher [browsher]
- August 17, 2026
- Patrick Ferris
After a week or two of abstracting the internals of Merry, I finally got a shell running in the browser. You can have a play with it here:
https://patrick.sirref.org/msh
The final hurdle was providing an abstract interface to file handles. Eio, the library that so far has enabled much of the OS abstraction, doesn't have a particularly good cross-platform file descriptor API. Eio_unix does extend sources and sinks with the Unix_fd tag, but there is no Eio.Fd.dup2 that provides a platform-agnostic API for file handle manipulation. Even if it did, a POSIX shell does a fair amount of assuming that your file handles are integers which might prove tricky on Windows.
The shell in the browser completely reuses the logic of Merry. It also links in a browser-aware subpackage of bruit (the OCaml port of linenoise I wrote) and a few, half-baked POSIX utilities I wrote (like ls and cat). But you can at least run something like:
$ echo "hello" > hello.txt
$ ls -la .
$ cat < hello.txt
Being able to, in some sense, run a shell anywhere is actually quite an attractive proposition. Shells, with all of their wonderful footguns, are still a reliable and familiar tool for interacting with a running system. I'm interested in the idea of running shells in more exotic deployments (e.g., unikernels) where it becomes an interface for dynamical reconfiguration or a tool for debugging.
Updates on Eio_mem
- August 17, 2026
- Patrick Ferris
At the heart of browsher is Eio_mem (an in-memory filesystem for Eio). The Eio_mem API now comes with (and exposes) a number of file descriptor operations:
val pipe : Eio.Switch.t -> Fd.t * Fd.t
val dup : sw:Eio.Switch.t -> Fd.t -> Fd.t
val dup2 : sw:Eio.Switch.t -> src:Fd.t -> tgt:Fd.t -> unit
I was happy to see Eio_mem getting some use in Thomas G.'s fork eio-fs where he was able to use it for chaos engineering.
Namespaces [namespace-musings]
- August 17, 2026
- Patrick Ferris
I spent a few days recently trying to come up with some formalism for the notion of names, namespaces and name resolution.
On the surface, it seems bigraphs might be a fruitful approach. The orthogonal treatment of locality and connectivity maps fairly well onto name structure (e.g, Module.X.foo, /foo/bar/hello.txt or foo.example.org) and redirection (e.g., symlinks or CNAMEs). Bigraph reaction rules could then model name resolution. A resolution process can move through the hierarchical name structure and across links at which point you might have some interesting properties to prove or check about a particular namespace system. Additionally, namespaces and resolution mechanism might compose in different ways and this might be worth formalising and comparing.
I didn't get much further than modelling some bits of a filesystem in BigraphER.
# filesystem
ctrl Dir = 0;
atomic ctrl File = 1;
atomic ctrl SymLink = 2;

# Query -- the thing that gets resolved.
atomic ctrl Q = 1;

# Reaction Rules
react resolve_symlink =
  Q{x} | SymLink{x, y} --> Q{y} | SymLink{x, y};

# Initial State
big s0 =
  Dir.
    (SymLink{sym_a, file_a}
     |
     Q{sym_a}
     |
     File{file_a}
    );

# Bigraphical Reactive System
begin brs
  init s0;
  rules = [ {resolve_symlink} ];
end
Resulting in these two transition states.
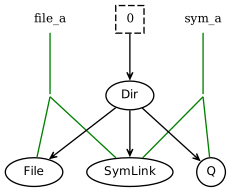
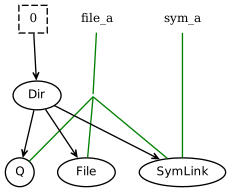
Bear in mind this was just a quick experiment. The first bigraph shows our query at sym_a and the second bigraph (using the resolve_symlink reduction rule) shows the query at file_a. All of this takes places within Dir. It seems that BigraphER represents the tree structure graphically with black arrows (rather than spatial containment).
Papers
- August 17, 2026
- Patrick Ferris
TODOs
- August 17, 2026
- Patrick Ferris
Over the next week, I hope to finish up a first draft of the aforementioned paper. I also want to publish a backlog of packages I have for OCaml: bruit, ocaml-bibtex, a fresh cut of Graft etc.
Ramblings
- August 17, 2026
- Patrick Ferris
I had some half-formed thoughts lying around in my forest, so I thought I might include those here:
Boilerplate [on-boilerplate]
- August 11, 2026
- Patrick Ferris
The word boilerplate gained popularity as a colloquialism used by newspaper and magazine editors for pre-prepared editorials and stories that were syndicated across the US. In effect, boilerplates were news stamps that could produce identical content.
I have been thinking about the nature of boilerplate code. How is it similar or different to boilerplate in its original meaning.
Distinguishing true boilerplate code from code that feels repetitive or boring to write is, I think, important. Argument parsing falls into this category quite well. Consider the following flag I added to Merry's set built-in.
let all_export =
  let doc = "Export all variables, like -o allexport." in
  Arg.(value & flag & info [ "a" ] ~docv:"ALLEXPORT" ~doc)
It uses cmdliner to define a new -a flag that will, in effect, make all variable definitions act like the export built-in. LLMs have been praised for their ability to do this specific task in OCaml.
What exactly is boilerplate about this code snippet? It seems to me that there is some sort of ceremony to defining a flag. There is boilerplate in the structure with more meaningful content threaded through. Below, is the example reduced to just the boilerplate replacing the for more meaningful parts with Merlin's typed holes: _.
let all_export =
  let doc = _ in
  Arg.(value & flag & info [ _ ] ~docv:_ ~doc)
Arguably the use of flag is quite important too as that is where the magic happens if you want an optional argument, or a positional one etc. As a thought experiment, having agents deliver fill-in-the-blanks style code might be quite useful. In a type system that can support holes (e.g. like in OCaml or Hazel) it becomes a more pleasant exercise, but helps keep you in the loop. I, myself, do not use any AI in the code I write; so I admit that I am pretty far from the problem.
The problem I have with this approach is that it is fairly easy to automate in a predictable and easy way! I just added a snippet subcommand to octx, but you could easily wrap this up in whatever your editor of choice is.
$ octx snippet cmdliner-flag
let cmdliner_flag =
  let doc = _ in
  Arg.(value & flag & info [ _ ] ~docv:_ ~doc)
The more I think on this problem the harder I find good uses for LLMs besides churning out vasts amount of end-to-end code; something I am personally not that interested in doing. It seems to me, to reap the benefits of LLMs, one must relinquish a certain amount of agency; anything less, and you could easily replace its usage with a cheaper, more predictable tool.
Shell Benchmarks, Back to Writing [weekly-2026-w26]
- July 4, 2026
- Patrick Ferris
A little late due to travel, but I did a little benchmarking of Merry.
Signal Handling in Merry
- July 4, 2026
- Patrick Ferris
In order to even run shellbench, I first had to fix some bugs in the shell implementation. Shellbench aims to warm up the shell before starting any benchmarks; it includes this prelude before getting started:
__ready=
trap __ready=1 HUP
kill -HUP "$MAIN_PID"
until ["$__ready" ]; do __dummy=; done
Whilst writing Merry, I hadn't really considered that the return context from a trap needed to be taken into consideration! I had assumed they would be silently ignored, how else would we know where to thread that context back into the shell's execution.
Even after reading through the specification for trap I am still none the wiser. I've opted to place some sensible signal polling points during the execution of the commands to run any signals that have come in. The single handlers in Merry simply push thunks onto a run queue. Looking at the Dash source code, it seems to be something that happens just before evaluation.
Benchmarking Merry [merry-benchmarks]
- July 4, 2026
- Patrick Ferris
Medium-to-small potatoes
- July 4, 2026
- Patrick Ferris
I used shellbench to understand where some of the performance pitfalls were coming from.
$ ./shellbench -s bash,zsh,msh sample/func.sh
-----------------------------------------------------------------------------------
name                                                     bash        zsh        msh
-----------------------------------------------------------------------------------
func.sh: no func                                      775,539  1,124,485      5,229
func.sh: func                                         398,861    197,169     93,424
-----------------------------------------------------------------------------------
* count: number of executions per second
This particular benchmark first runs nothing (i.e. :) and then a function lookup and execution. Surprisingly msh is slower at doing nothing! I perf-ed a run of msh test.sh with just a single : in the file:
Test built-in
- July 4, 2026
- Patrick Ferris
After making various improvements to Merry that almost halved the memory usage (e.g., removing extraneous string manipulations, adding a fast-path to the PATH variable for resolving programs). I was still pretty far off the performance of these other shells. I decided to have a look at dash which has a simple implementation.
This flame graph is for the following shell script:
f () { :; }
while __count=$(($__count+1)) && ["$__count" -le 10000 ]; do
	f
done
echo "count is $__count"
And here are some rudimentary benchmarks:
$ time -p dash test.sh
count is 10001
real 0.01
user 0.01
sys 0.00
$ time -p msh test.sh
count is 10001
real 15.53
user 4.28
sys 12.28
It turns out the massive slowdown is very simple to explain. In the dash flamegraph there is a oexpr stack; which comes from the bltin/test.c file. dash, along with the other shells, does not spawn a process for the [-test command! Forcing dash to do use the binary [ gives:
$ time -p dash test.sh
count is 10001
real 7.55
user 3.95
sys 3.44
Which is much more respectable in terms of performance compared to msh. Plenty of work to do though!
Parsing arithmetic expressions
- July 4, 2026
- Patrick Ferris
There was some obvious low-hanging fruit to help improve some of the performance differences. The first was pre-parsing arithmetic expressions. Morbig, the static parser, does not implement arithmetic expression parsing; so Merry does it for us. Before, it was on-demand, as we encountered an expression of the form $((<e>)). Now, it happens up front. This should improve tight-loops.
Writing
- July 4, 2026
- Patrick Ferris
More on this soon, but I have started writing two separate papers bringing all of this work together.
Three weeks in the Shell [weekly-2026-w25]
- June 16, 2026
- Patrick Ferris
The last three weeks have been focused work on building Merry. In practice, I wanted to run the following two commands through Merry's shell: msh:
apt-get install debootstrap -y
debootstrap stable /stable-chroot http://deb.debian.org/debian/
Seemingly innocuous. But both commands run thousands of lines of shell script. Whether that's Debian package maintainer scripts or state-machines for processing package release files.
What follows is a handful of the bugs and the shell scripts that caused them.
Field Splitting
- June 16, 2026
- Patrick Ferris
Edge-cases abound in the POSIX shell specification; and field splitting is one of the most serious perpetrators. Field splitting happens after word expansion. It is a known footgun amongst shell script authors.
$ count () { echo "Count: $#"; }; FOO="hello world"; count $FOO
Count: 2
Quoting variables that need expanding will prevent field splitting from taking place, but it is an easy thing to forget.
Field splitting uses the IFS (internal field separator) environment variable to determine how to do the splitting, and it comes with some extra rules beyond "split on these characters".
$ IFS=" "; FOO=" hello    world"; echo $FOO
hello world
$ IFS=" "; FOO=" hello    world"; echo "$FOO"
 hello    world
$ IFS=":"; FOO="a:b:c:"; echo $FOO
a b c
$ IFS=":"; FOO="a:b::c:d"; echo $FOO
a b  c d
$ IFS=":"; FOO=":a:b:c"; echo $FOO
 a b c
$ IFS=; FOO="unset   IFS"; echo $FOO
unset   IFS
Variable assignment
- June 16, 2026
- Patrick Ferris
How a shell stores variables also impacts field splitting. Naively, Merry stored variables as strings, but really they should be stored as their expanded form.
Consider this example of saving a function output in a variable called base.
iter () {
 echo "a"
 echo "b"
 echo "c"
}

base=$(iter)

for n in $base; do
  echo "Got $n"
done

for n in "$base"; do
  echo "Got $n"
done
Later, when we come to iterate across the fields of $base we wouldn't be able to reconstruct the intial fields that $(iter) produced if we simply saved the result as a string. Too much information would have been lost.
Redirections
- June 16, 2026
- Patrick Ferris
Redirections control what file descriptors point to. Each redirection has a lifetime associated with it. For example: cat < README.md really says "open README.md and execute the cat program mapping the process's FD 0 to the FD of README.md". When cat returns that redirection is no longer valid.
Other redirections are not so simple. Consider:
$ echo "!dlrow olleh" > input.txt
$ (read line; echo $line) < input.txt | rev
hello world!
There are lots of redirections here too. Firstly the standard input for everything inside the braced command (read line2; echo $line) should be the open file descriptor for input.txt. The standard output of the braced command should be the writing end of a pipe whose reading end is passed to rev as that process's standard input. The final standard output for rev should be unchanged from what it was originally (the shell's standard output).
Getting redirections right is hard, consider this snippet from the debootstrap scripts (all in the context of stdout and stderr pointing to a debootstrap.log file and file descriptor 4 pointing at the true stdout).
for m in $MIRRORS; do
    pkgdest="$TARGET/$($DLDEST pkg "$s" "$c" "$a" "$m" "$path")"
    if [! -e "$pkgdest" ]; then continue; fi
    pkgs_to_get="$(download_debs "$m" "$pkgdest" $pkgs_to_get 5>&1 1>&6)"
    if [ -z"$pkgs_to_get" ]; then break; fi
done 6>&1
More niche built-ins
- June 16, 2026
- Patrick Ferris
As the dust begins to settle on the nuts and bolts of implementing a POSIX-ish shell, new challenges are allowed to emerge from deep within scripts.
One such challenge is the seemingly endless (I know, they're finite) shell built-ins! Whilst trying to run debootstrap using its fakechroot variant, I bumped into getopts... a whole command-line parsing shell built-in.
An In-memory Filesystem for Eio [eio_mem]
- June 16, 2026
- Patrick Ferris
Towards the end of last week and the beginning of this week, I threw together a prototype for an in-memory filesystem for Eio: Eio_mem. Concretely, this provides a means for constructing an Eio.Fs.dir_ty Eio.Path.t value that is completely in-memory.
Thanks to Eio's capability-first approach, any existing code implemented against the _ Eio.Path.t API should just work with the in-memory filesystem.
There's a convenient Eio_mem.Fs.load function that can take a path from one filesystem (most likely a normal one from Eio_linux or Eio_posix) and replicate it into the in-memory filesystem. For example, you might have a static web-server pointing to a directory like "/var/www". The following might be the only change you need to make it completely in-memory (example from ocaml-cohttp):
 let () =   let port = ref 8080 in
   Arg.parse
     [ ("-p", Arg.Set_int port, " Listening port number(8080 by default)") ]     ignore "An HTTP/1.1 server";
   Eio_main.run @@ fun env ->
+  Eio_mem.run @@ fun menv ->
   Eio.Switch.run @@ fun sw ->
-  (* Restrict to current directory: *)
-  let htdocs = Eio.Stdenv.cwd env in
+  (* Restrict to in-memory current directory: *)
+  Eio_mem.Fs.load ~filter (Eio.Stdenv.cwd env);
+  let htdocs = Eio.Stdenv.cwd menv in
   let socket =
     Eio.Net.listen env#net ~sw ~backlog:128 ~reuse_addr:true
       (`Tcp (Eio.Net.Ipaddr.V4.loopback, !port))
The keen-eyed reader might have noticed the filter parameter. This can be used to ignore certain paths (here I ignored .git and _build which were adding substantial time to loading the filesystem).
Using meio to debug Merry [weekly-2026-w23]
- June 4, 2026
- Patrick Ferris
During a large rewrite of Merry, I introduced a regression causing certain shell programs to hang indefinitely. I thought it might be a good opportunity to try out Meio.
First, let's look at a trace of Meio from some real-world programs. For example: meio -- msh -c "sleep 100".
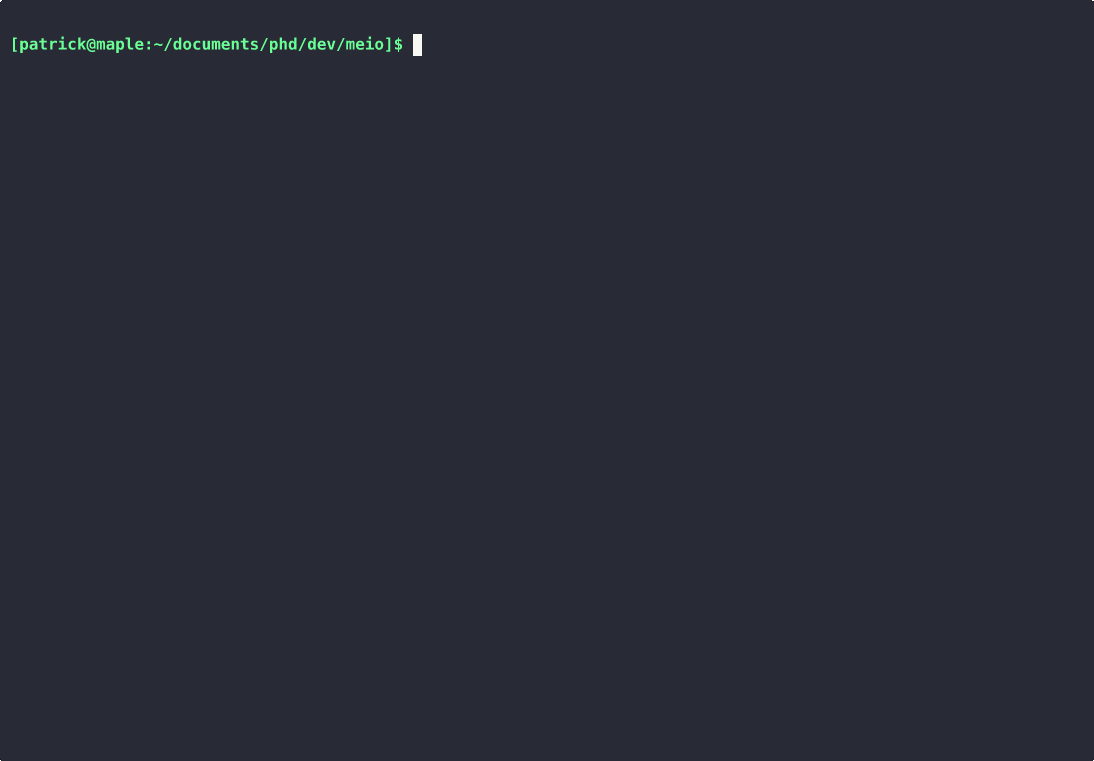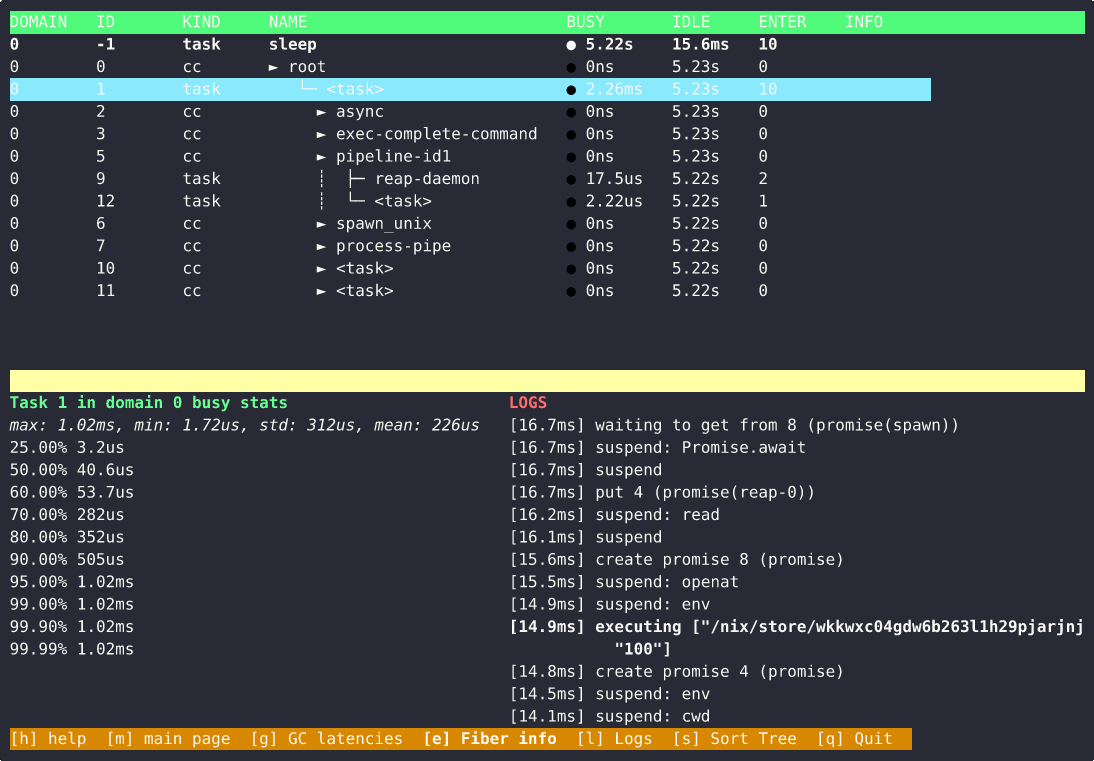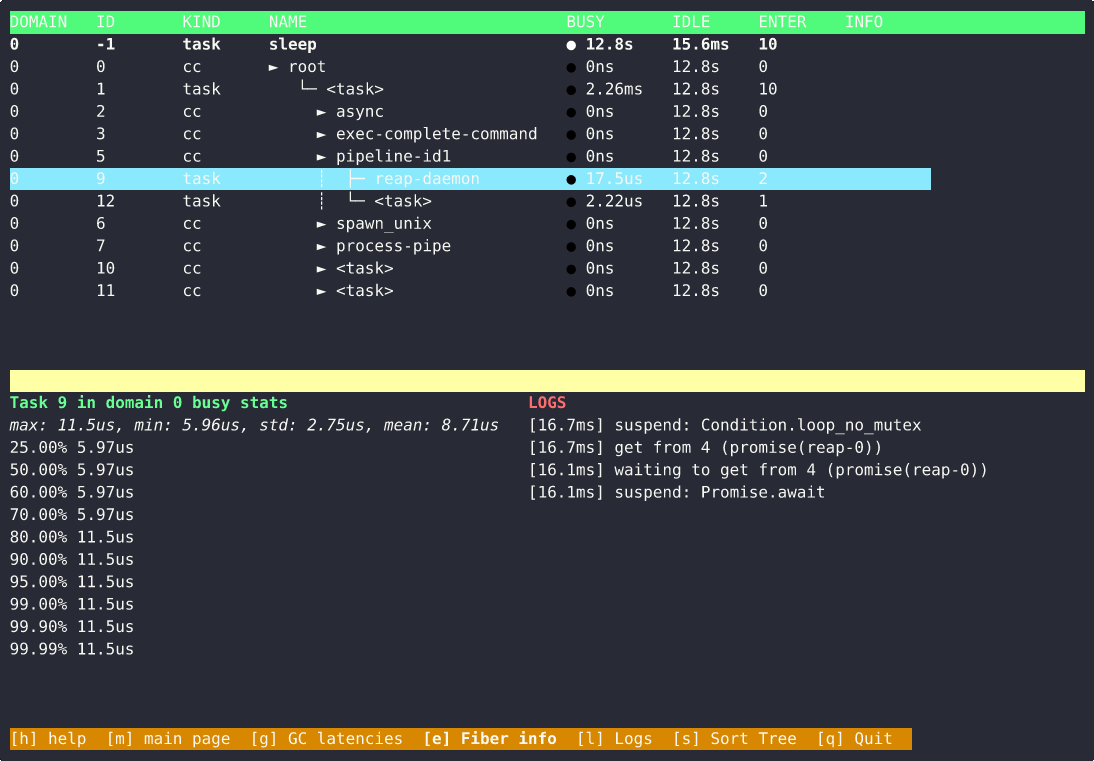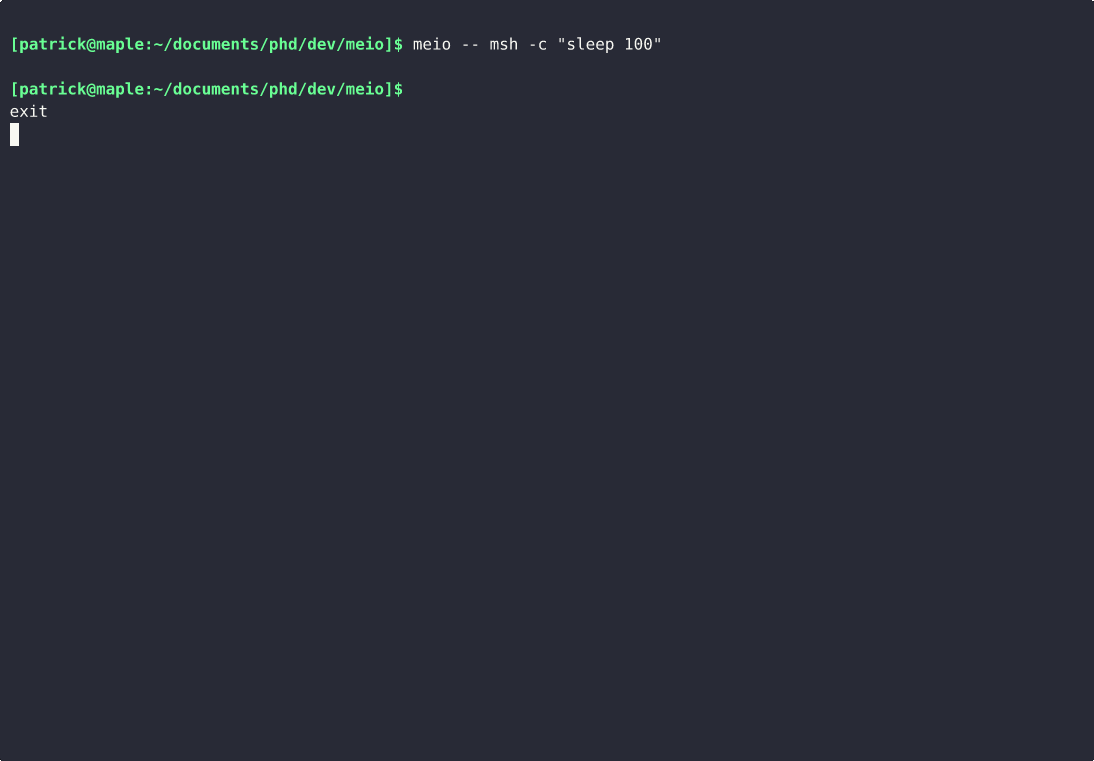
One problem that comes up immediately from this example is that the tree hierarchy of tasks and cancellation contexts makes it tricky to reason about the logging. Here, we can see the pipeline's cancellation context clearly labelled pipeline-id1. This is an Eio.Switch.t for the pipeline sleep 100. The actual execution log for sleep 100 bubbles back up to the main fiber (that has no name, so it is called <task>). The daemon fiber, for ensuring the spawned process is reaped, is attached to the switch and is displayed below it.
Meio has a long way to go. Most programs are too fast to be monitored in this way. Using something like tokio-console's model might be a better idea here focusing less on the tree strucuture of the program, and more on the performance and monitoring of individual tasks. Without this, it turns out Meio was not all that useful for debugging this specific issue (which ended up being some bad pipe management on my part).
Catching up in May [weekly-2026-w22]
- June 1, 2026
- Patrick Ferris
I never quite found the time in May to write weeknotes. I think that's, in some ways, quite a good thing. My philosophy on weeknotes is not that they are a public punchcard of my progress. They are a tool for organising thoughts and keeping my colleagues abreast of what I am up to. Only the latter suggests any necessity for timeliness and given I frequently message, call and zulip them, if a few weeks fall between the cracks then that's okay!
All that being said, I have tried to provide some thoughts and things I have been up to over the course of May and not just week 22 of the year.
Tools for Shells
- June 1, 2026
- Patrick Ferris
Some tools and libraries related to Merry.
Meio
- June 1, 2026
- Patrick Ferris
The shell work continues, and as the complexity internally increases I have found myself wishing for some more tools for debugging concurrent Eio programs. Given enough pipes and compound commands, it is fairly easy to introduce a fair deal of concurrency to your shell programs. To this end I hope I have improved meio somewhat in this fork.
In particular, there were several things I wanted to improve.
Simple UI improvements -- the set of tools for building TUI UIs from nottui are, on closer inspection, rather good and simple. For example, turning a particular UI component into a scrollable pane is as simple as wrapping it in a call to this function.
Logging more runtime events -- Eio programs emit information via OCaml's runtime events. This is how meio knows which fiber is currently active for example. It also emits information like "the current fiber created a new promise" and "this fiber is blocked waiting for a promise". I have not figured out an intuitive way for representing this in meio's tree-view, but I did turn these into "system logs" that appear in the per-fiber logs which is already an improvement. Thanks to Thomas for helping understand the runtime event sequence for logging this information.
Timestamping where possible -- all runtime events come with a timestamp, these were mostly discarded by meio.
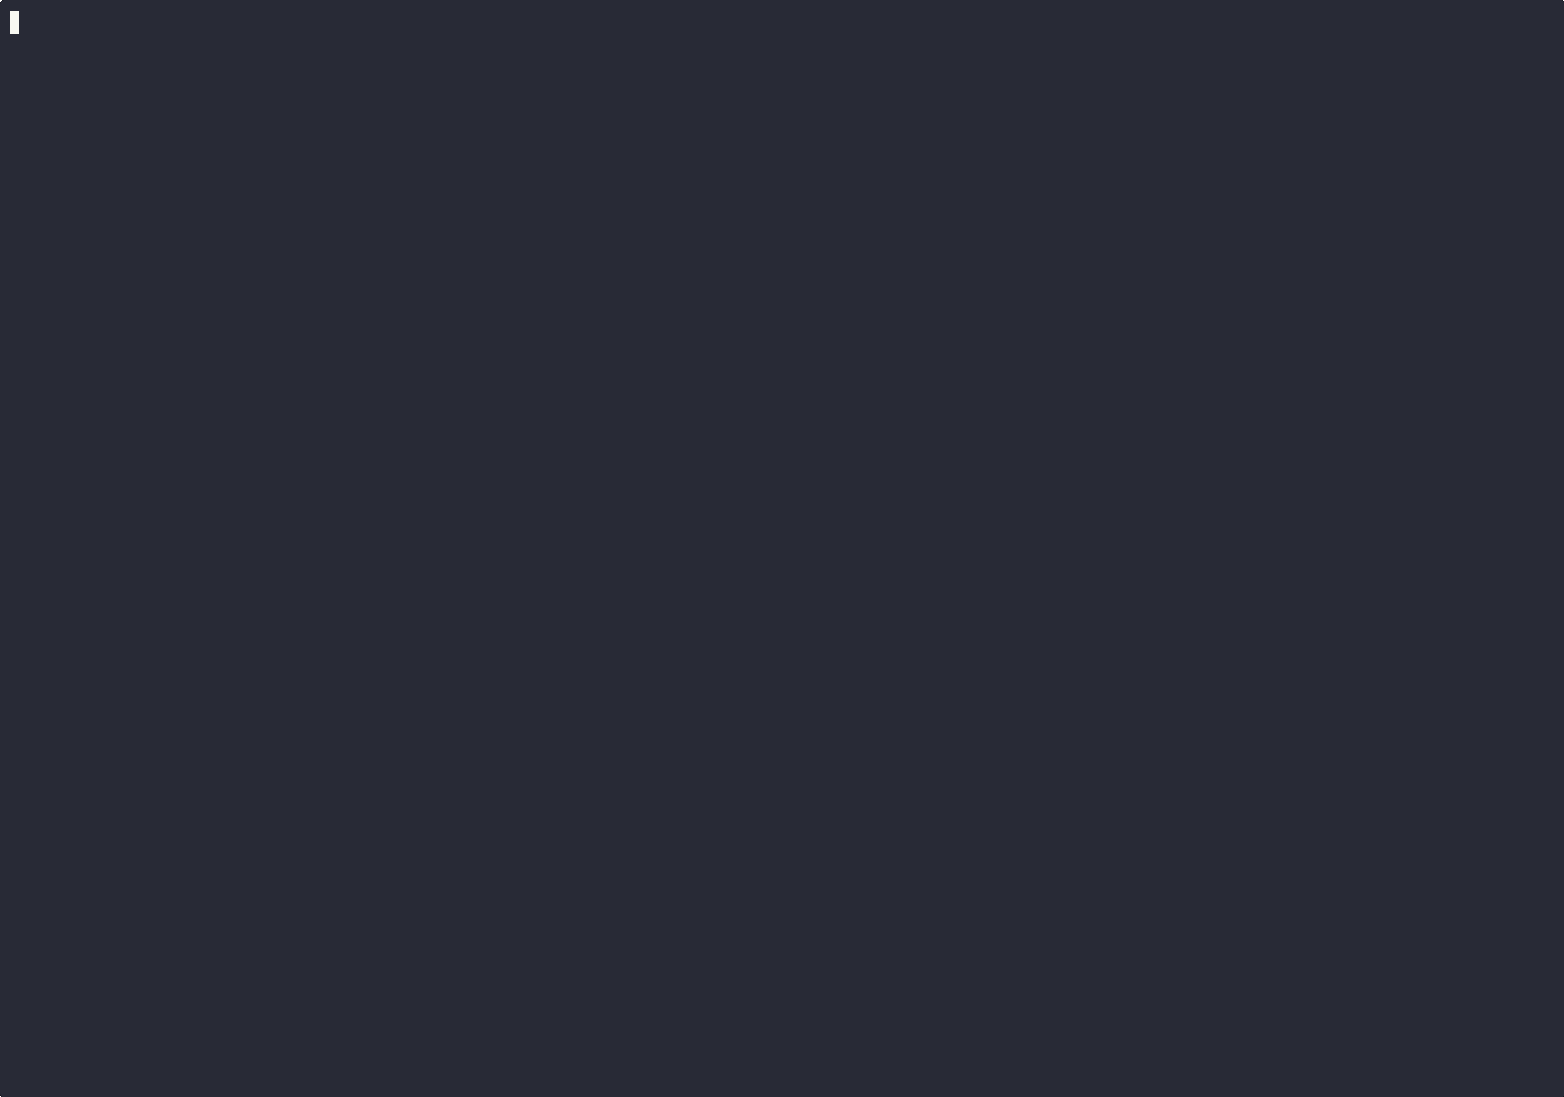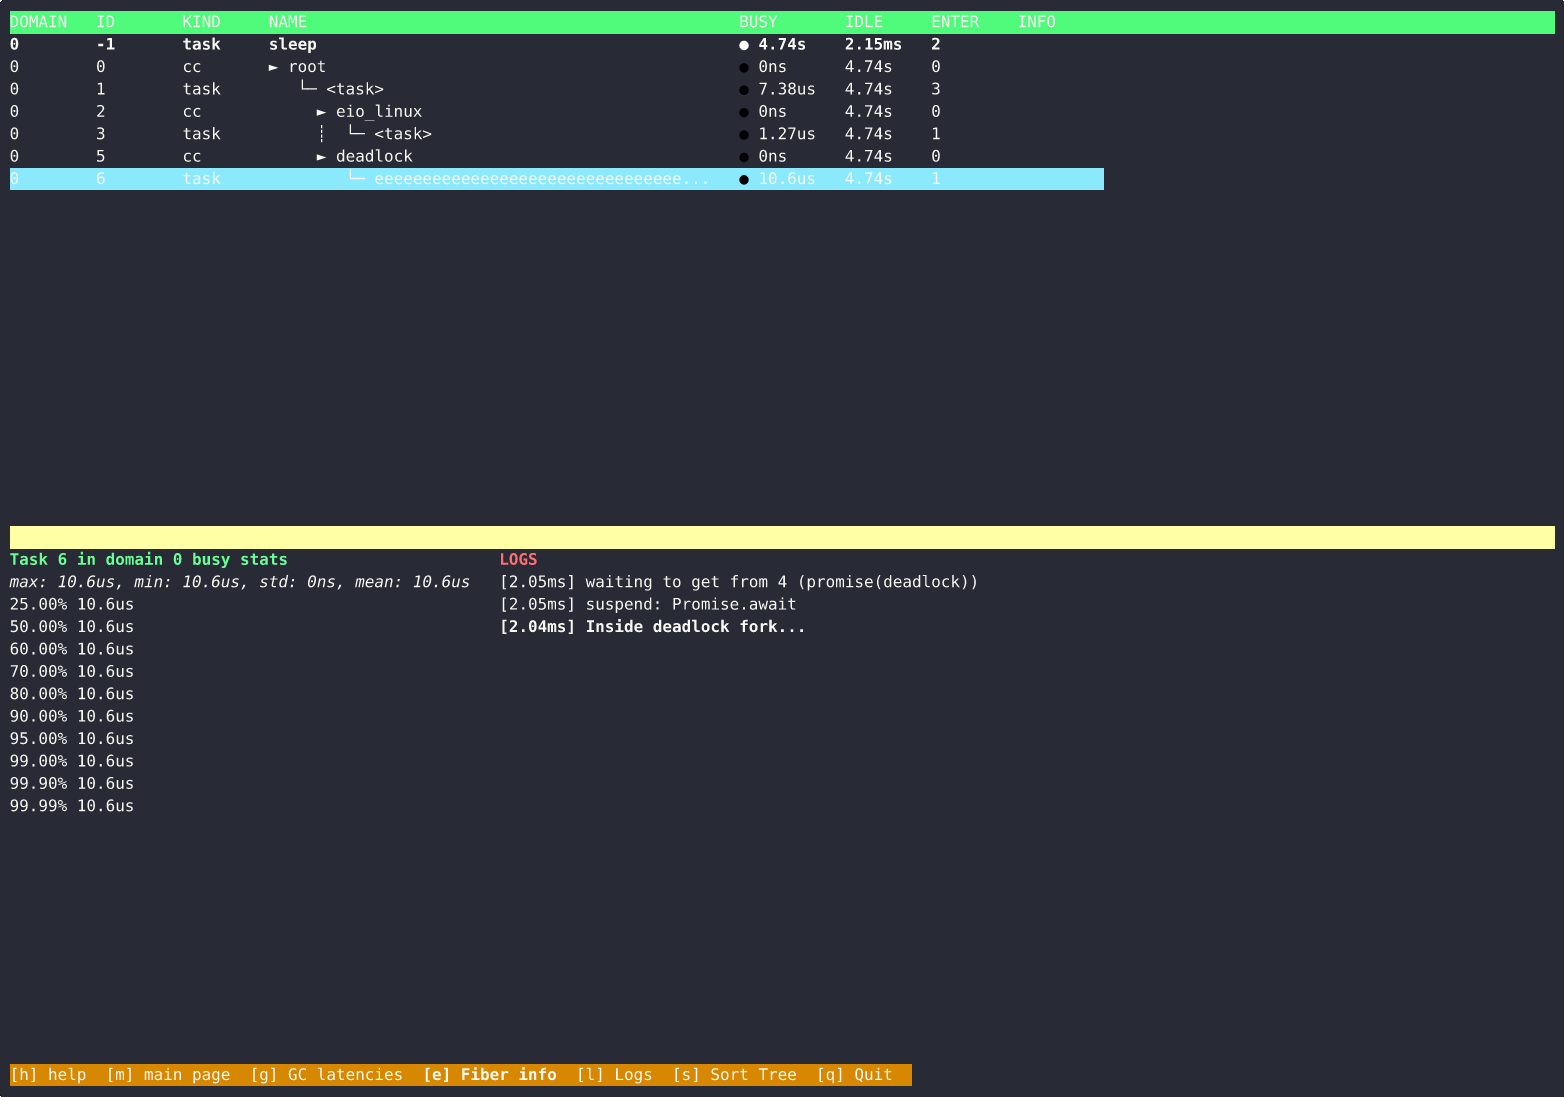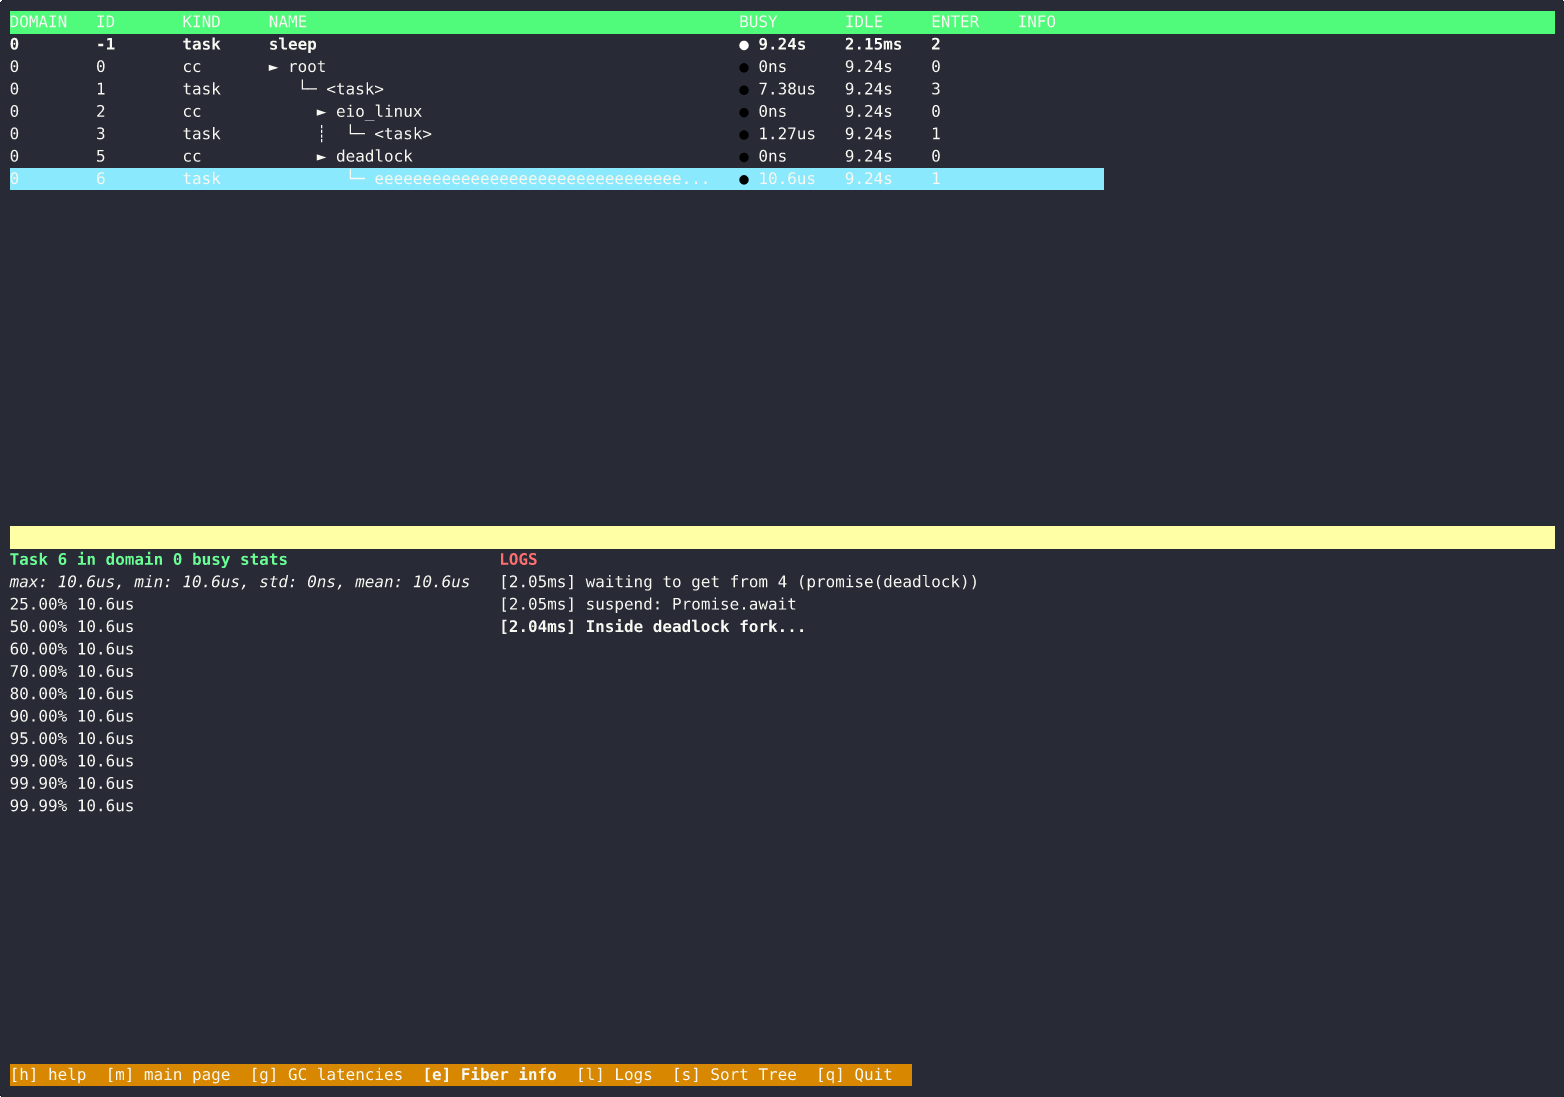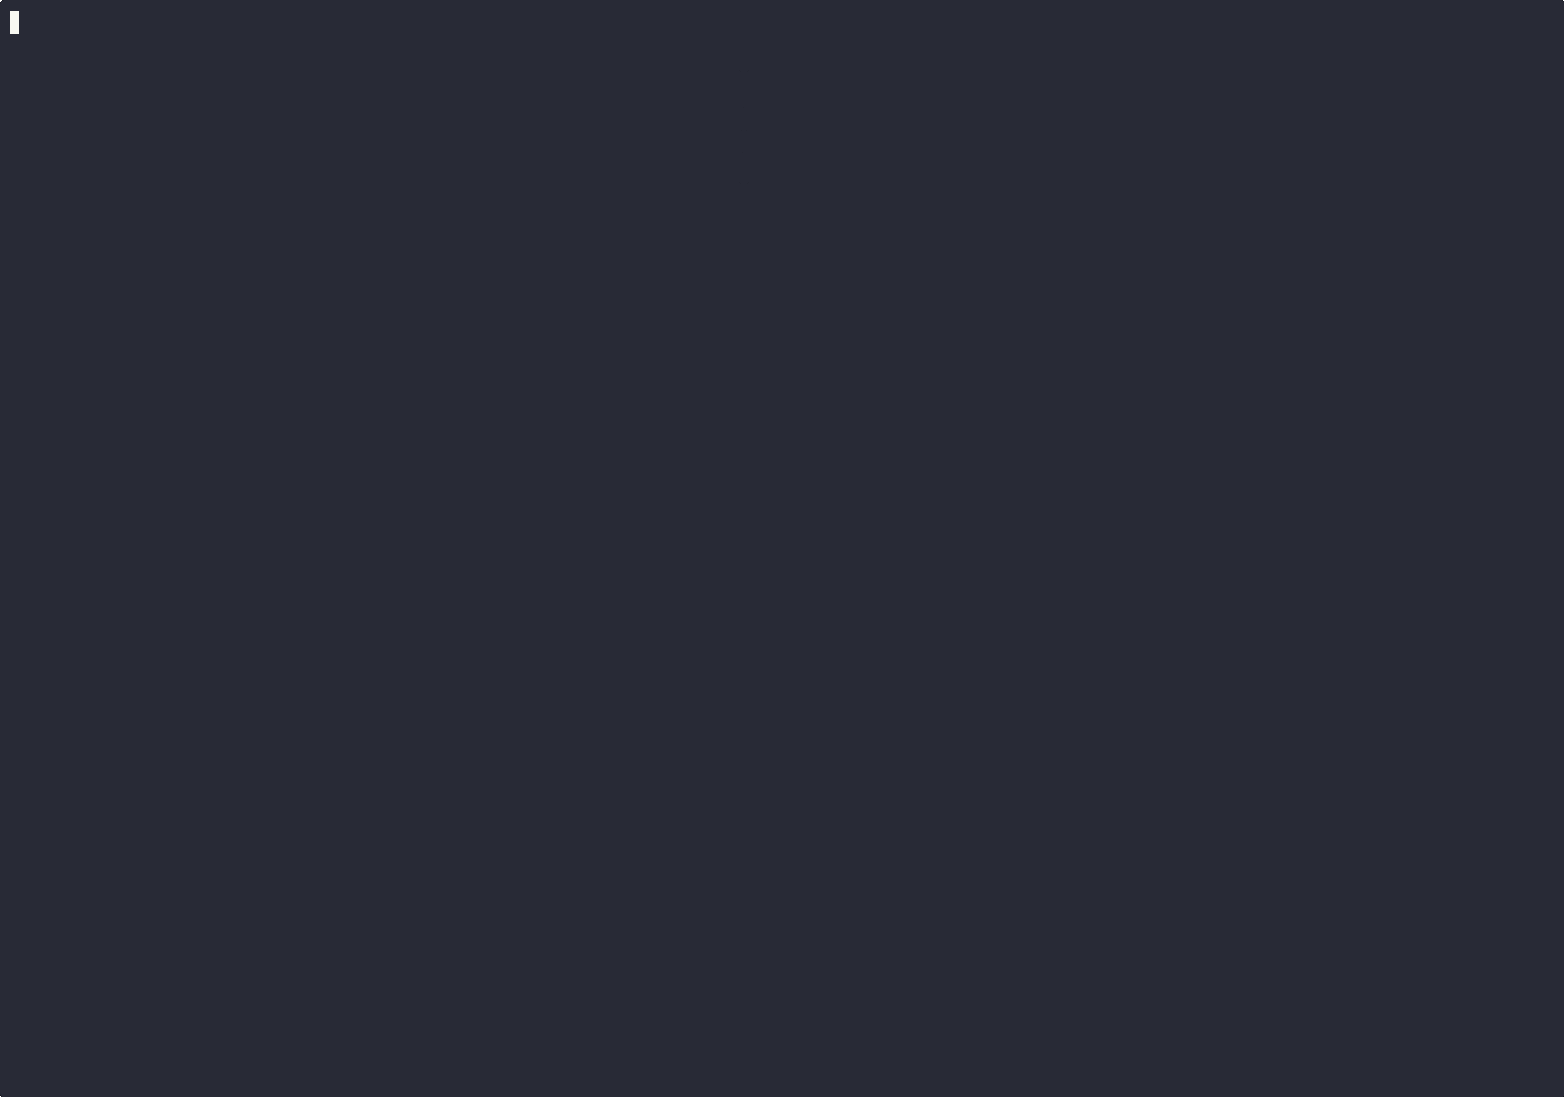
Some aspects of meio made it clear that labelling Eio.Switches and Eio.Promises might be a good practice. After reading Michael's Eio forays, I can't help but wonder if a more opinionated Eio for Systems Programmers guide might be useful. I think the Eio README does a wonderful job of introducing most of the low-level concepts, but not quite how they are used by the working systems programmer.
Glob
- June 1, 2026
- Patrick Ferris
A little dismayed at the lack of progress I was making with Merry, I switched to a specific problem I knew I wanted to fix -- removing the dependency on glob(3), replacing it with a pure OCaml implementation.
let get_txts fs =
  Glob_eio.glob fs Glob.(of_component [ dir_sep; string "home"; dir_sep; star; string ".txt" ])
Anil provided some issues with fixes too which was very appreciated.
Beyond factoring out fork+exec, Merry should now be portable to the browser. Of course there are lots of other refactorings needed to (e.g. a fake-filesystem) -- but I'm interested in how I can use Eio's filesystem capabilities to do this pretty seemlessly. Having an emeddable, pure OCaml shell may also unlock some cool debugging capabilities for unikernels too!
Geocaml
- June 1, 2026
- Patrick Ferris
Michael has been valiantly trying some of the Geocaml libraries in his work on rendering LiDAR point clouds. Where possible, I have been reviewing Michael's PRs and helping implement features he might find useful. I also took his Laserver for a spin, and suggested a few changes.
Rtree
- June 1, 2026
- Patrick Ferris
After a comical series of attempts, I (or rather Anil) released rtree.0.2.0 which contained:
A bug fix where not all the tree values were being returned.
A new bounds function for getting an Rtree's maximum bound.
A set of simple removal functions.
PROJ
- June 1, 2026
- Patrick Ferris
Michael added some new functions to ocaml-proj. Previously, I had worked on making PROJ more portable by using virtual libraries. This was a little restrictive, as it forced users to always implement a JS version of any functionality that exists in the native version of PROJ.
To make it easier to contribute (and allow the C bindings to contain more specific bindings) I carved out the two virtual library implementations into standalone libraries, and reimplemented the virtual library support using these libraries. Now projects can depend directly on proj_c if they wish to have more features in exchange for being less portable.
Ppxlib
- June 1, 2026
- Patrick Ferris
Thankfully, work on ppxlib has been relatively quiet. Nathan also opened a PR for initial OCaml 5.6 support. Keeping on top of 5.6 features is probably the right way to go about this (rather than one giant PR during the 5.6 release cycle).
I'm particularly happy to have some better migration error handling. The previous errors, though uncommon, were confusing ppx users and hopefully this will help ppx authors and ppxlib maintainers triaging important encoding bugs or feature wishes.
Self-hosting
- June 1, 2026
- Patrick Ferris
I now have a fairly workable setup for self-hosting source code with git.sirref.org and tests.sirref.org. One piece that is missing, is a publishing workflow. I spent a little time building a YOCaml static-site generator for packaging OCaml libraries. Unfortunately, this was full of rabbit holes and busy work which was frustrating.
Tar-eio
- June 1, 2026
- Patrick Ferris
One such rabbit hole was tar-eio. It was in a bit of a sorry state, so I took the opportunity to improve the API for new users. Tarring a directory is now as simple as:
let foo = Eio.Path.(cwd / "foo") in
let foo_tar = Eio.Path.(cwd / "foo.tar") in
Eio.Path.with_open_out ~create:(`Or_truncate 0o755) foo_tar @@ fun foo_tar ->
Eio.Switch.run @@ fun sw ->
let t = Tar_eio.create ~sw foo in
Tar_eio.run t (Tar_eio.flow_of_file tar)
There was also a series of security issues that the tar library had that were fixed too, you can read about those in Thomas's weeknotes.
Shell forks revisited [weekly-2026-w17]
- April 28, 2026
- Patrick Ferris
Whilst I did get up to some other work last week, I decided to dedicate this weekly to fork-ing in the shell.
Must we fork?
- April 28, 2026
- Patrick Ferris
I have spent some time trying to figure out: can you implement a shell that never has to fork and run its own code (as opposed to fork+exec-ing, which is necessary)? There are, at least, two bits of POSIX shell semantics that make this hard: concurrency and redirects, particularly in the presence of shell built-ins.
Individual commands in a pipeline, according to the POSIX specification, will have their standard input and output connected up before other redirections.
The standard input, standard output, or both of a command shall be considered to be assigned by the pipeline before any redirection specified by redirection operators that are part of the command.
Additionally:
...each command of a multi-command pipeline is in a subshell environment; as an extension, however, any or all commands in a pipeline may be executed in the current environment.
Where a subshell is defined as:
Subshell: A shell execution environment, distinguished from the main or current shell execution environment.
We will note that subshell \neq child process. In practice, however, the two are used fairly interchangeably given the semantics of spawning a child process. Perhaps the two most crucial aspects of a given command in a subshell are that:
It is run in parallel with the other commands.
It should be reentrant.
In what follows we will assume that we are discussing a multi-command pipeline p.
\texttt {p} = \texttt {cmd}_1 | ... | \texttt {cmd}_n \text { where } n \geq 2
Pipeline parallelism
- April 28, 2026
- Patrick Ferris
The POSIX specification does not mandate parallelism explicitly for commands in a pipeline. However, in practice the semantics of a pipeline necessitate concurrency at the very least.
Suppose we have \texttt {cmd}_1 | \texttt {cmd}_2 where \texttt {cmd}_1 produces an infinite amount of output (e.g., cat /dev/urandom) and \texttt {cmd}_2 consumes a finite amount of input (e.g., hxd-xxd -l100). What is the result of running this pipeline with the default POSIX shell options?
$ dash -c "cat /dev/urandom | hxd.xxd -l100"
00000000: 5033 7981 ae44 d475 074c 5361 0a9e 3828  P3y..D.u.LSa..8(
00000010: f88c 1f9e 3b0e bcde 528a f78c b1e4 7195  ....;...R.....q.
00000020: 16f2 8325 c90b 9310 539c af04 8289 c3a0  ...%....S.......
00000030: 57c5 680a 2c81 a999 71b6 708e 95df e720  W.h.,...q.p....
00000040: 004c 407a 8365 9448 65c6 b435 bed2 4084  .L@z.e.He..5..@.
00000050: 62ea 96ab 2b23 0385 f9d2 fc30 d090 1719  b...+#.....0....
00000060: 68d1 c514                                h...
cat: write error: Broken pipe
There are three factors that influence the pipeline's execution behaviour (i.e. what is done about the commands that are run and the exit status we return).
pipefail: Withpipefailset tofalse(the default), the exit status of the pipeline is entirely decided upon by the exit status of the rightmost command (above \texttt {cmd}_2). Withpipefail, the pipe will exit with 0 if all commands exit with 0; otherwise the non-zero exit status of the rightmost command is taken.!: If the pipeline begins with!then this inverts the exit code in the way you might expect.All commands must terminate.
Whilst in theory \texttt {cmd}_1 does not terminate, the termination of \texttt {cmd}_2 closes the reading end of the pipe resulting in the Broken pipe system error.
Let's replace \texttt {cmd}_1 with the following compound command that also produces, left to its own devices, infinite output on stdout.
while echo "some bytes"; do
  :
done | hxd.xxd -l100
In this example, we no longer have the luxury of being able to fork and exec. The compound command (the while loop) forces our hand -- we must rely on the internal execution logic of the shell to keep it going. How then do we prevent \texttt {cmd}_1 from blocking our shell from spawning \texttt {cmd}_2?
For most shells, this is where they might fork themselves and allow the while loop to execute in the child. The parent continuing on. Alternatively, the work could continue on in a separate thread (in OCaml parlance, domain). Fibers (green threads, coroutines etc.) are only possible if there are a sufficient number of co-operative yields (which can be hard to track: any control flow or shell built-in would need to ensure they periodically yield to the other commands in the pipeline).
With that being said, it would seem we have workarounds to ensure the parallel aspects of pipelines are possible to build without forking the shell state itself.
Command Reentrancy
- April 28, 2026
- Patrick Ferris
Command reentrancy deals with the fact that commands in a pipeline run in subshells. In practice, this means any \texttt {cmd}_i should not impact the execution environment of any other \texttt {cmd}_j. Commands may certainly interfere with one another: a rogue rm might remove a file that some other command was about to read or was in the middle of reading!
\S 2.13 of the POSIX shell specification describes the execution environment. In Merry we lift this into the ctx type making it completely immutable; the only way to update the context is to destructively declare new fields, e.g., { ctx with cwd = "/home/bactrian" }. All shell built-ins work directly from the context as opposed to any state that might also be kept by the process itself (e.g., we do not call getcwd(3) to expand PWD, but instead read it from the context).
Most state is handled nicely by this functional implementation of the shell; except open (or not) file descriptors. The exec built-in is particularly thorny in this regard:
If exec is specified with no operands, any redirections associated with the exec command shall be made in the current shell execution environment.
So, exec 3>&1 says "in the current execution environment map file descriptor 3 to stdout" and exec > /dev/null says "in the current execution environment map stdout to /dev/null. This is often used to silence anything writing to stdout.
info () {
  echo "INFO: $1" >&3
}

exec 3>&1 > /dev/null
info "Starting up server..."
echo "Some noisy program spamming STDOUT"
info "All is quiet..."
If we are not running shell built-ins inside new child processes, then we must lift the file descriptor table into the context as well and disallow any two built-ins to run in parallel. Consider this example:
exec < ./hello.txt

while read line; do
  echo "Got $line" >&2
done | (exec < ./world.txt; cat)
If we allow exec to change the set of open file descriptors of the shell process directly, then individual commands in the pipeline are no longer re-entrant. The pipeline here is not being used to pipe bytes from one command to another, but instead to expose concurrency and the subshell behaviour.
The second exec < ./world.txt has no impact on the currently opened file on stdin, the while loop continues to read ./hello.txt. This is straightforward to implement with fork as you can dup2 any files you need. The bookkeeping and isolation is all provided by the POSIX process semantics. Without fork, the file descriptors would have to be saved and restored on every suspension and resumption to provide an illusion of isolation.
We could relax our rule to "disallow any two built-ins to run in parallel" by taking a lock on the file descriptor table, but considering the lock is held from the point of resumption until the next suspension it might not achieve very much in practice.
Some of the intricacies of scheduling are also covered in Michael Greenberg's An executable and formal semantics of the POSIX shell.
To motivate the question, consider the following two pipelines:
(1)
while true; do echo 5; done | true(2)
while true; do echo 5; done | { read x; echo $((x+42)); }Both pipelines spawn two processes, both of which use shell builtins exclusively: neither of these pipelines needs to make an
execvesystem call (though some systems may implement true or echo as executables, Smoosh and most shells build them in).
Scheduling is an opaque part of the POSIX specification. Indeed, as we have argued here, there is no semantics for scheduling. Here is a similar pipeline run through a script that straces for clone and fork calls on various shells:
% ./test/check_fork.sh "while echo 5; do : ; done | true"
bash  3
dash  3
yash  1
zsh   1
ksh   1
ash   3
It might make an interesting use case for effects in OCaml -- whilst we can certainly piggyback on Eio's existing suspension mechanisms, this is slightly different in that we need to ensure some preconditions are true before resuming certain computations. Fiber-local state is insufficient as programs implicitly depend on global state of the process (in particular the FD table). In this sense, we need some form of suspension-resumption hooks.
Landlocked Eio [weekly-2026-w16]
- April 18, 2026
- Patrick Ferris
I spent the start of last week wrapping up the "local" CI I mentioned the previous week. Unfortunately it was mostly a packaging nightmare, followed by missing features in ocaml-ci-local. It would be great to have a richer CLI tool for running tests on a directory of git repositories, but unfortunately most of the existing tooling has prioritised the Github/Gitlab etc. APIs.
After coming across minimal during the week, I took it as an opportunity to learn a little more about Linux's Landlock mechanism.
Landlocked Eio [landlocked-eio]
- April 18, 2026
- Patrick Ferris
Landlock is a sandboxing mechanism that has existed in the Linux kernel since 5.13. It allows unprivileged processes a means to restrict their ambient rights (e.g. creating a file or opening a network connection). These rights are ambient in the ambient authority sense, i.e., any process can attempt to perform an action without needing access to any particular capability to do so.
Ambient systems are often contrasted with capability-based ones. In terms of operating systems, this is most commonly illustrated with access-control-lists-as-columns and capabilities-as-rows in an access matrix.
Eio is a capability-based library in OCaml -- resources are provided at the start of the application and can be passed around wherever they are needed. The design is covered in Thomas Leonard's lambda capabilities blog post. Unfortunately, any application (willingly or via a third-party library) may ambiently access OS resources. In OCaml, this may be by using the standard library functions (e.g. Sys.readdir), things from the Unix module, a C FFI function or by spawning a subprocess.
I had a go at "landlocking" Eio applications last week after stumbling across minimal's hakoniwa library for process isolation (which is very reminiscent of void processes).
module Landlock = Eio_linux.Landlock
let ( / ) = Eio.Path.( / )

let run_eio file =
  Eio.traceln "Writing to file";
  Eio.Path.save ~create:(`Exclusive 0o644) file "hello, world!";
  Eio.traceln "Reading file: %s" (Eio.Path.load file);
  Eio.Path.unlink file

let bad_program () =
  In_channel.with_open_bin "/etc/passwd" In_channel.input_all
  |> Eio.traceln "/etc/passwd: %s"

let () =
  Eio_linux.run @@ fun env ->
  Eio.Path.with_open_dir (Eio.Stdenv.cwd env / ".") @@ fun dir ->
  let parent_fd =
    Eio_unix.Resource.fd_opt (fst dir) |> Option.get
  in
  let file = dir / "hello.txt" in
  let rules =
    Landlock.Rule.
      [
        path_beneath ~parent_fd
          ~flags:Flags.Fs.(
            write_file + read_file + make_reg + remove_file
           );
      ]
  in
  match Landlock.enter rules with
  | Ok () ->
      run_eio file;
      bad_program ()
  | Error `Not_supported -> Eio.traceln "Landlock not supported!"
Running this program (with the necessary privileges) prints the following.
+Writing to file
+Reading file: hello, world!
Fatal error: exception Sys_error("/etc/passwd: Permission denied")
Eio already has a similar function for the BSDs using capsicum. In capsicum, processes enter a capability mode:
cap_enter()places the current process into capability mode, a mode of execution in which processes may only issue system calls operating on file descriptors or reading limited global system state.
This plays nicely with Eio's capabilities. Within the scope of Eio.Path.with_open_dir, the directory will remain usable after entering "cap" mode. This is not the case with landlock unless you add a specific path_beneath rule to the ruleset (like in the example above). However, you could imagine plumbing the necessary information throughout the Eio_linux backend for it to build a set of rules that can be applied at any given moment in order to mimic the capsicum semantics.
Self-hosting Music [self-host-music]
- April 18, 2026
- Patrick Ferris
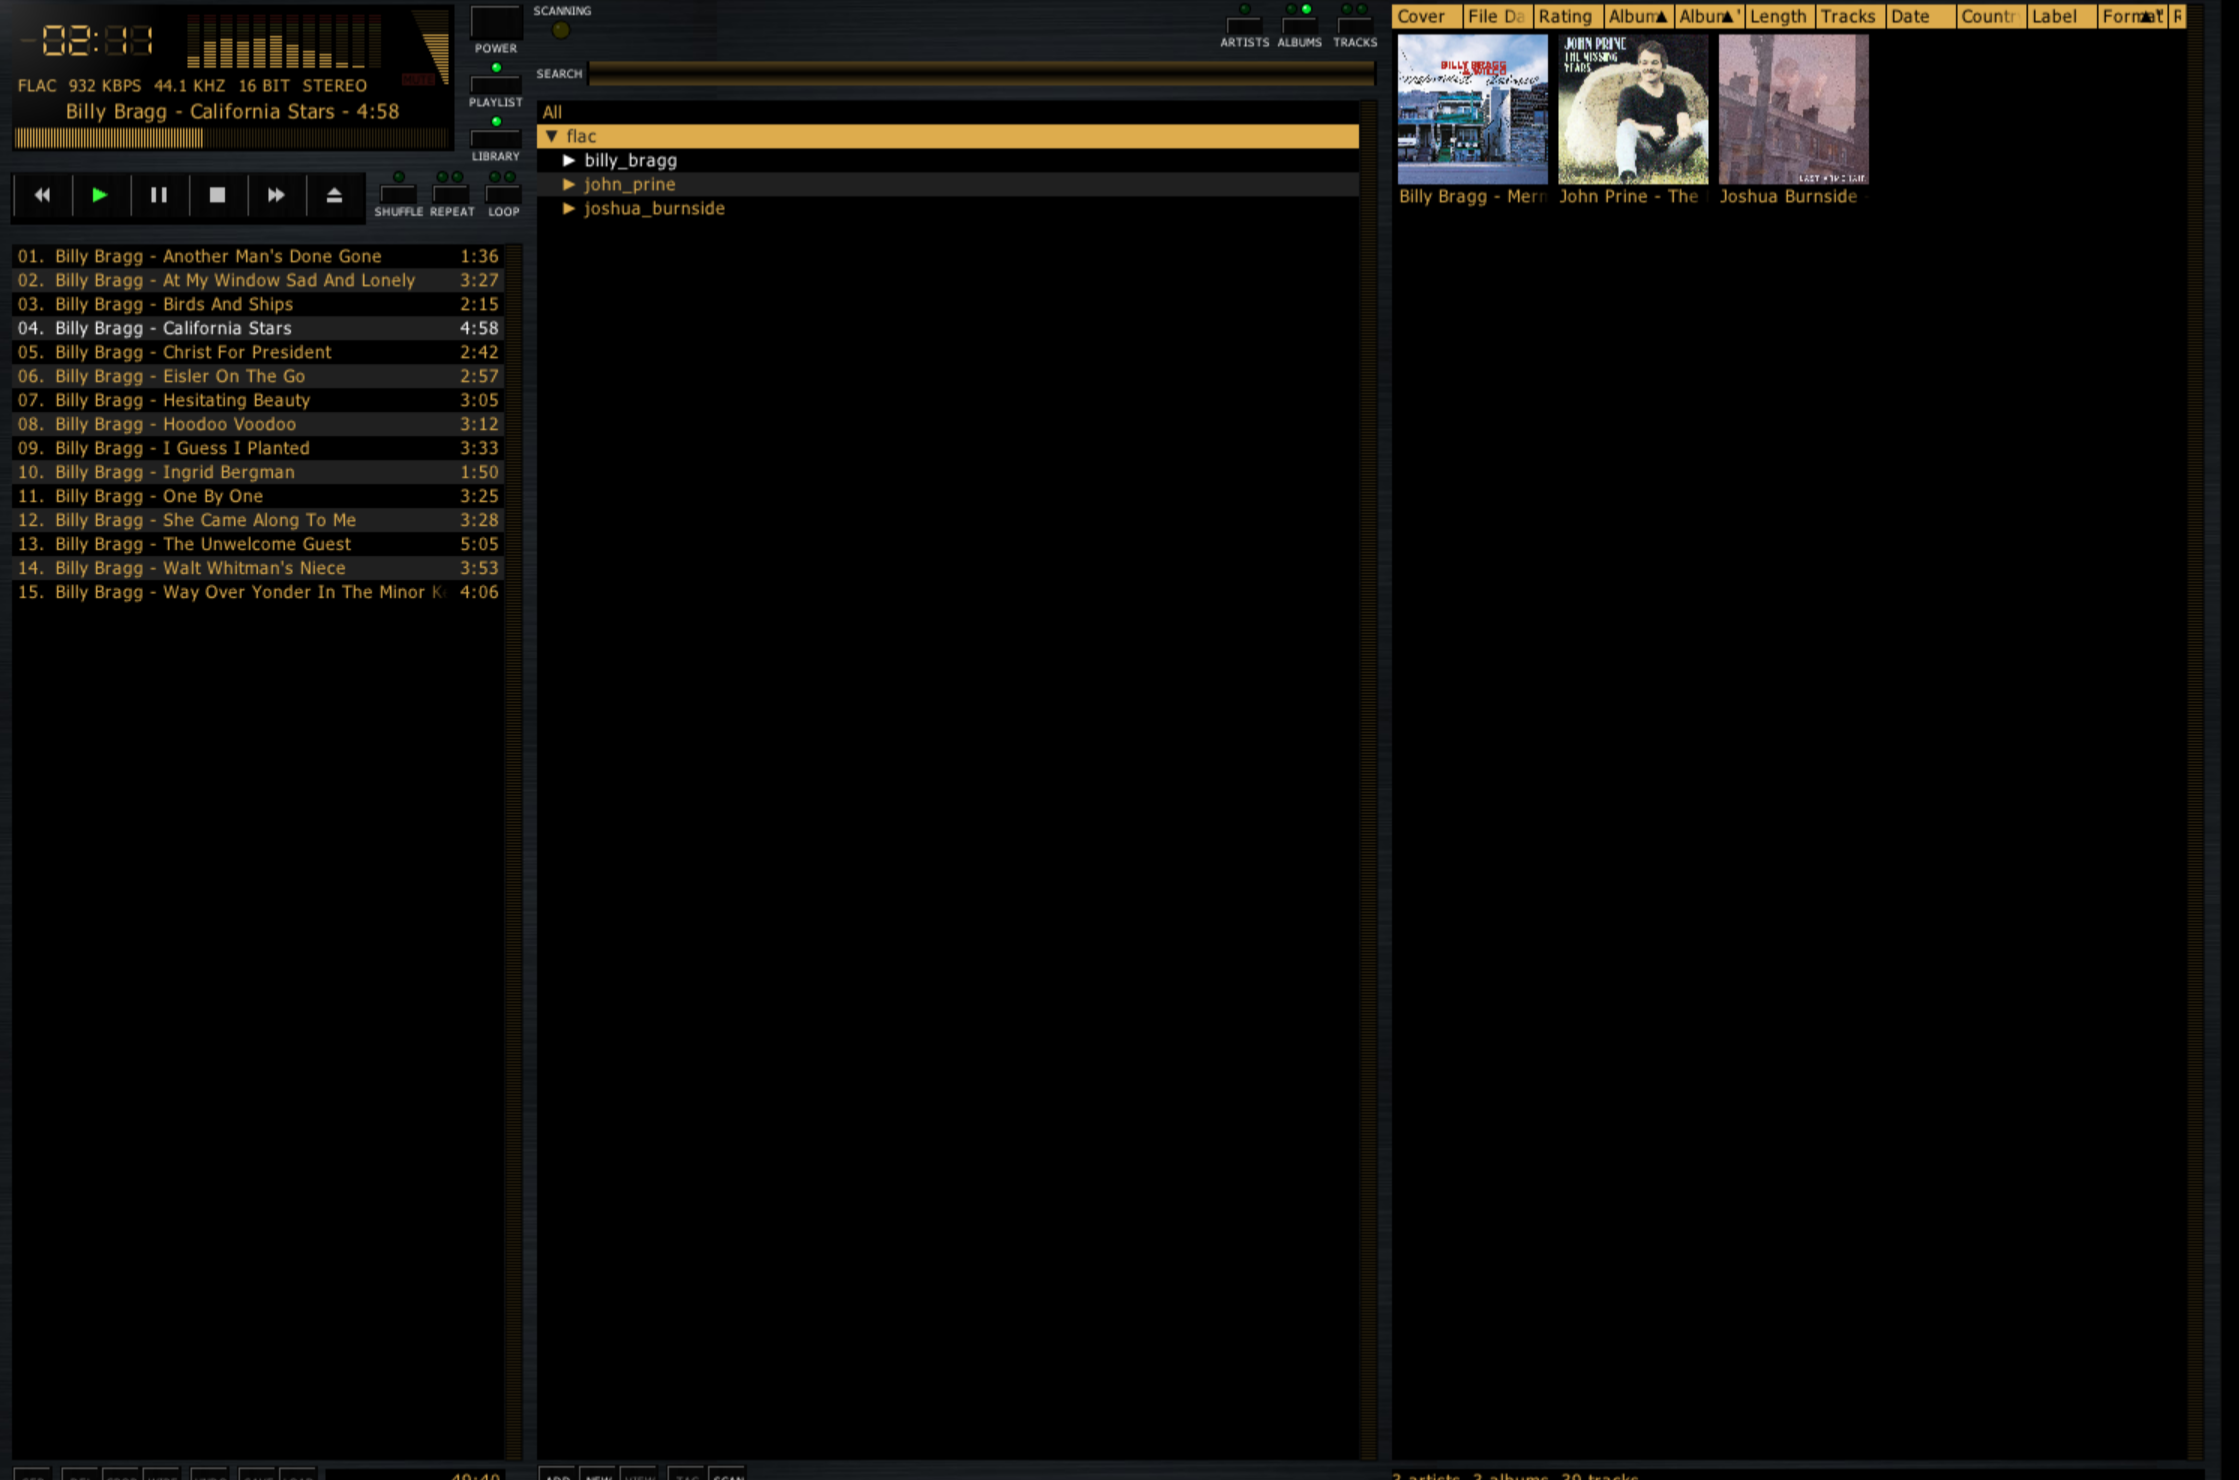
After my friend, Greta, sent me some articles about music streaming services and their exploitation of artists, I decided enough was enough and setup navidrome. It is compatible with Subsonic and so far I'm very pleased to be streaming my own music to my devices. I am using substreamer on iOS. On my laptop, I tried out Andreas Rossberg's Camp
What you got here is an old-school music player heavily inspired by good old Winamp [1], with a focus on decent music library and playlist handling.
I took Anil's OCaml Installer tool for a spin with great success... after a few mishaps mostly related to system dependencies.
$ nix-shell -p pkg-config gcc pulseaudio miniaudio libxi libxrandr libxinerama libffi mesa libxcursor libGL
$ oi-linux-x86_64 run --with=https://github.com/patricoferris/camp#nix -- camp
The fixes in my fork of Camp are just to install the assets using dune and also statically provide the -lpulse flag (which should probably be dynamically picked up). Otherwise, raylib or miniaudio selects the Null playback device. Roll-on cross-ecosystem package management.
Moving away from Github [weekly-2026-w15]
- April 13, 2026
- Patrick Ferris
A short week for me as I was hiking with family in and around Porthmadog, Wales.
Reliance on Github
- April 13, 2026
- Patrick Ferris
I joined Github in 2016, but only began using it in earnest (according to my Github activity) in July 2018: right after Microsoft announced its intent to acquire Github; and just before they closed the $7.5bn deal. I originally joined to boost my résumé and I hoped to receive the odd open-source contribution to projects I was working on (like ppx_deriving_yaml). Since then, I have used Github extensively both at work (Tarides) and for more personal projects.
There have been many reasons to jump ship from Github ever since the Microsoft acquisition (e.g. their planned (and quickly unplanned) announcement to charge self-hosted Github runners). Ultimately, I was convinced when I noticed the new AI tool on the homepage with options to select your "versatile and highly intelligent" model. There is no need for me to stay on the platform for my personal projects. AI integration into Github has nullified those earlier motivations for hosting my projects on the site. The number of contributions has increased, but many of them fix superficial elements of an underlying bug. In my (maybe too uncharitable) imagination, it is all too easy for contributors to prompt their built-in LLM to "fix this broken unit test" and for the fix to layer a single-use workaround on top, instead of identifying and correcting the relevant code. This is, at least, what it looks like to me when I receive a new review request on my open-source projects.
At the end of last week I set up my own Git infrastructure following Ryan's nixos setup. In the future, the source of truth for my projects will be git.sirref.org (I will likely continue to mirror to tangled.org or Github).
Reduce, Reuse, Recycle
- April 13, 2026
- Patrick Ferris
Part of self-hosting your own source code is managing some form of automatic testing. I hesitate to describe it as "continuous integration" as the term is confusing and overloaded. Luckily, parts of the OCaml community have been building test infrastructure for a while.
I have a proclivity for rebuilding things from scratch be it to learn or to build something the way I want. It is a proclivity I am trying to reign in as I find less and less time to hack on projects. I think this is a good thing. Reusing and recycling existing technologies, in earnest, feels like a pushback on the not-invented-here syndrome that seems to be snowballing thanks to LLMs and code generation tools.
To that end, I dusted off my OCurrent knowledge, and repurposed the "local" mode of OCaml-CI to work with my git repositories. After battling through nested layers of git submodules, I managed to Nix-ify this and get it running at tests.sirref.org. I needed to add multi-repository support as well as Current.Monitors for the local git refs. By no means perfect, but it is nice to own the testing infrastructure (and the cost of downloading OCaml images and the compute to run the tests).
Forking in Shells & Library Maintenance [weekly-2026-w14]
- April 3, 2026
- Patrick Ferris
This week, Merry got close to executing apt-get install ca-certificates and running Debian's debootstrap scripts correctly. Nathan and I released Ppxlib 0.38.0, I added support to ocaml-proj for compiling to the browser and I fixed a long-standing bug in hilite.
Forking in Merry
- April 3, 2026
- Patrick Ferris
So far, Merry has managed to support many features of the POSIX shell specification without needing to do a fork(2) without an exec. Or, to put it another way, all the forking that Merry does, will only be followed by running C code. This is actually a feature of Eio's Process API. It is required to make process execution safe in the context of multiple domains in OCaml (mostly due to ensuring consistency within the garbage collector). However, it is perfectly okay to fork and run OCaml code provided there is only a single domain.
In a shell, many features of the shell language require that commands (or built-ins, function applications etc.) execute within a subshell. The specification does not go into detail about how shells should implement this, but many choose to fork in order to preserve some state in the parent (for example, the file descriptor table). Some shells try to minimise the number of forks as an optimisation. The korn shell (ksh) is one such shell.
Using the notation
$(command)will causecommandto execute in a subshell of the current ksh. In many instances, ksh will not actually fork/exec a subshell when command is a built-in or a shell function.
By trying to adhere to Multicore OCaml's "thou shalt not fork" commandment, Merry is much more similar to ksh in this regard. However, whenever there is an interaction with a shell built-in and semantics that need a child process, things get tricky very quickly. Consider the following:
while echo "hello"; do
  :
done | head -n 3
We have a mix of shell built-ins, normal commands, a compound command (the while loop) and a pipeline. Each individual command in the pipeline requires you to run them in a subshell and set them up before executing them. Without a fork for that first command, you may end up looping forever which is not the intended behaviour here. I had a good conversation with Michael about the implications of this for reproducibility.
For now, I have started implementing a fork for some of the shell features whilst still trying to maintain the functional core of the implementation.
An OCaml 5.5 compatible Ppxlib
- April 3, 2026
- Patrick Ferris
Nathan and I released an OCaml 5.5 compatible version of ppxlib.
Ppxlib Releases › 0.38.0 [ppxlib-release-0-38-0]
- March 30, 2026
- Patrick Ferris
Nathan and I released ppxlib.0.38.0 last week. Its main feature is full migration support for the upcoming OCaml 5.5 compiler (currently in its alpha3 release). This means supporting the handful of new features landing in OCaml 5.5: modular explicits, external type declarations and arbitrary "local" structure items.
As Nathan and I continue to find a plausible maintenance story for ppxlib, Nathan has opened an issue on the OCaml compiler to discuss the idea of adding additional extension points to the language.
This comes from the desire to be able to store encoded versions of new OCaml features inside older abstract syntax trees.
There are also some nice bug fixes in there too:
A potential OOM loop has now been removed.
Browser support for ocaml-proj [ocaml-proj-virt]
- April 3, 2026
- Patrick Ferris
A while ago I built some "modern" bindings to PROJ4 in OCaml. After reading Jon Ludlam's weeknotes (and speaking with him and Anil, I thought it might be nice to add a Javascript backend to those bindings). This was relatively straight-forward using Dune's virtual libraries and is available on Github.
With virtual libraries, your own data analysis could (if you wished) depend solely on the proj library and later choose to either link it with proj.c or proj.js depending on where the analysis is being deployed.
I briefly looked at WASM support, but quickly realised there was not much appetite for it and trying to compile around the C FFI was going to be hard.
Hilite updates
- April 3, 2026
- Patrick Ferris
Since I helped relaunch the ocaml.org website a few years ago, I have maintained hilite, a tool for doing build-time syntax highligting.
It is being used on the ocaml.org website, in yocaml_markdown and also in Michael's webplats (when it works...).
And it was Michael who led me to finally fixing and adding syntax highlighting support for Python and Go. Once I was on this roll, I finally took a look at fixing the long-standing bug of trying to highlight ocaml-mdx code, like the following:
# 50.123;;
# 1 "file.ml";;
In fact, this code now highlights fine, but was the source of the bug. The syntax highlighting grammer confuses the ocaml-mdx # as a toplevel directive and trouble ensues.
Ppxlib release and Merry updates [weekly-2026-w13]
- March 30, 2026
- Patrick Ferris
Ppxlib Releases › 0.38.0 [ppxlib-release-0-38-0]
- March 30, 2026
- Patrick Ferris
Nathan and I released ppxlib.0.38.0 last week. Its main feature is full migration support for the upcoming OCaml 5.5 compiler (currently in its alpha3 release). This means supporting the handful of new features landing in OCaml 5.5: modular explicits, external type declarations and arbitrary "local" structure items.
As Nathan and I continue to find a plausible maintenance story for ppxlib, Nathan has opened an issue on the OCaml compiler to discuss the idea of adding additional extension points to the language.
This comes from the desire to be able to store encoded versions of new OCaml features inside older abstract syntax trees.
There are also some nice bug fixes in there too:
A potential OOM loop has now been removed.
Merry updates
- March 30, 2026
- Patrick Ferris
It turns out writing a POSIX(ish) shell is hard; at least, there is a vast number of slightly obscure features that one needs to support. I think this is surprising because most people writing shell scripts write simple shell scripts; scripts that use a much smaller subset of features. In the same breath, those same developers are likely to use something like apt-get install bash which runs a plethora of more advanced (and non-POSIX) shell scripts!
Exec redirects
- March 30, 2026
- Patrick Ferris
In a shell script, you can use the built-in command exec to replace the current process with a new one (e.g. exec vim). However, there is a different mode of operation for exec:
If exec is specified with no operands, any redirections associated with the exec command shall be made in the current shell execution environment.
One of my litmus tests for Merry is the Debian debootstrap scripts (h/t Anil). One thing that it does is the following:
err () {
  printf "err $1" >&4
}

exec 4>&1
A lot of detail has been elided for clarity. exec 4>&1 sets up a redirection for the shell's execution environment in which file descriptor 4 is now an alias for standard output. So, writing to 4 (by redirecting a command's standard output to 4 i.e. >&4) will output to where standard output is going (most likely the terminal).
For this to work, shell's must dup2 the relevant file descriptors which have the following condition:
If the file descriptor newfd was previously open, it is closed before being reused; the close is performed silently (i.e., any errors during the close are not reported by dup2()).
This is all very well, unless your program has an important file already open that happens to have file descriptor 4. The Eio Linux and POSIX backends suffer from this problem. Both make use of a file-based synchronisation mechanism for waking up the eventloop should another domain push a completion to the scheduler's run queue. On Linux this is via an eventfd and in POSIX, a pipe.
This dup2 will close the eventfd and will likely grind Eio to a halt (or an assert false). For now, I have resorted to vendoring Eio and moving the eventfd file descriptors to higher values, though I have opened a PR to make this more configurable. This bug is quite easy to write up... it was not so easy to find!
As a random example, consider the debconf/confmodule script which offers very little room for a buggy implementation!
Outreachy
- March 30, 2026
- Patrick Ferris
The presentations from the demonstrations for this round of Outreachy are now online!
Write support in OCaml TIFF library [outreachy-ocaml-tiff]
- February 9, 2026
- Patrick Ferris
I am mentoring Tambe Salome during the December 2025 Outreachy round to add support for writing TIFF files in the ocaml-tiff library.
You can now see the video of the demonstration day presentation:
A POSIX Shell in OCaml [weekly-2026-w12]
- March 19, 2026
- Patrick Ferris
Long time, no weekly. Since the start of this year I have been building a POSIX shell in OCaml called msh (with the underlying library called Merry). Merry is available online now.
A POSIX(ish) shell in OCaml
- March 19, 2026
- Patrick Ferris
Merry is a POSIX(ish) in OCaml. It uses Eio alongside Morbig (a static parser for POSIX shell).
Why another (POSIX) shell?
- March 19, 2026
- Patrick Ferris
Shells have been around for a long time. In my research on the notion of metashell I wrote about Louis Pouzin originally coining the term:
Metashells › Louis Pouzin's "SHELL" [pouzin-shell]
- May 19, 2025
- Patrick Ferris
I spent some time reading part of the multics design documentation this week. Louis Pouzin coined the term "SHELL" in this document, and I was reminded yet again just how important it is to be a good writer even as a "computer science researcher". For example, this excerpt from the requirements section of the document
The previous definitions imply that a command MUST be designed while keeping in mind the user, sitting at his console, wondering about what might be going on, mistyping or forgetting arguments, even if fully aware of the conventions, and possibly interfering with the command by hasty quits, carriage returns, and other temperamental reactions.
And then later, when defining the "SHELL".
We may envision a common procedure called automatically by the supervisor whenever a user types in some message at his console, at a time when he has no other process in active execution under console control (presently called command level). This procedure acts as an interface between console messages and subroutine. The purpose of such a procedure is to create a medium of exchange into which one could activate any procedure, if it were called inside of another program. Hereafter, for simplification, we shall refer to that procedure as the "SHELL".
It still surprises how little the undergraduate degree in computer science at Cambridge focuses on writing skills.
I built Shelter exploring the idea of a shell-like interface that allowed users to undo their shell actions (amongst other cool tricks). Unfortunately shell-like is not enough. Shelter cut many corners to masquerade as a shell (e.g. appending env to understand how a command may have altered the execution environment). I felt it was necessary to make Shelter a "SHELL"! To do that, I needed a solid foundation to build on.
msh, the POSIX shell that comes with Merry, is by no means POSIX-complete in terms of features. But it is my daily driver at this point. It includes a pure OCaml rewrite of linenoise (a small, self-contained alternative to the venerable readline) called bruit.
If you have docker installed on your machine, you can take it for a spin today:
docker run -it --rm patrickferris/msh
The patrickferris/msh docker image is just for trying it out. It is based on the OCaml 5.3 alpine image.
Alternatively, you can build msh from source and have it available in your opam switch.
opam pin git+https://tangled.org/patrick.sirref.org/merry
There are many small paper cuts left to patch over, but most of it is porcelain (e.g. ctrl+left-arrow for moving in bruit). Unfortunately, these are the kinds of things that you will immediately stumble upon.
What makes Merry different?
- March 19, 2026
- Patrick Ferris
Nothing.
Merry is supposed to be a solid, POSIX-ish base to build on. Unfortunaltely, as it turns out, the subset of features from the POSIX specification that people actually use... is pretty much all of it. Every possible redirection, variable expansion, shell built-in and compound command make some appearance. Not to mention the non-POSIX bits of shell we all take for granted (e.g. &>-redirection).
Merry and msh are useable. You will most likely find bugs if you use them. If, when using msh, you find something obscure happening you can enable debug mode either my setting the variable MSH_DEBUG or by invoking msh with -v -v.
What's next?
- March 19, 2026
- Patrick Ferris
It is soon time to combine Shelter and Merry into the time-travelling, POSIX-ish shell that I have been trying to build since I first started working on Shelter.
For this to be successful, I need Merry to be able to pass plenty of tests and right now that involves trying to install plenty of packages using tools like apk and apt.
Shell MRDT
- March 19, 2026
- Patrick Ferris
What I am particularly interested in reasoning about, is the execution context in Merry. This value, alongside the file-system, constitutes a fairly deep understanding of the state that changes in each step of a shell's evaluation loop.
This was, in terms of Shelter, the missing piece for truly building some kind of MRDT across shell sessions.
TIFF in OCaml
- March 19, 2026
- Patrick Ferris
I picked up from the excellent Outreachy work of Tambe Salome in getting write-support in ocaml-tiff. We are getting closer to the kind of API I envisaged in this latest round of refinement and review.
let ( / ) = Eio.Path.( / )

let checkerboard ~size =
  let v = Nx.zeros Nx.uint8 [| size; size |] in
  for row = 0 to size - 1 do
    for col = 0 to size - 1 do
      if (row + col) mod 2 = 0 then Nx.set_item [ row; col ] 254 v
    done
  done;
  Nx.to_bigarray v

let () =
  Eio_posix.run @@ fun env ->
  Tiff_eio.with_open_out (env#cwd / "example.tiff") @@ fun w ->
  let tif = Tiff.make (checkerboard ~size:256) in
  Tiff.to_file tif w
I have also been extremely pleased to see further external collaborators appearing:
Below are weeklies from 2025.
Data Provenance in Shelter [weekly-2025-w49]
- November 24, 2025
- Patrick
A late update that stretches more than a week...
failed to render transclusion https://shelter.sirref.org/shelter-log-002/OCaml Roundup: November 2025 [ocaml-roundup-november-2025]
- December 9, 2025
- Patrick Ferris
A roundup of some of my OCaml activity this month!
Ppxlib Updates
- December 9, 2025
- Patrick Ferris
I managed to get a substantial amount of ppxlib work completed in the last month. Some of those bits are described in detail below.
Initial OCaml 5.5 Support [ppxlib-5.5-support]
- December 9, 2025
- Patrick Ferris
We recently merged 5.5 support into our main branch (thanks to Nathan for the review). It cast a light on some new features coming to OCaml including the ability to define any structure locally. Most OCaml programmers will be familiar with things like local opens (e.g. let open M in). This has now been extended to include any structure item (more or less, you cannot nest value bindings).
External types have also landed, bringing with them a new "type kind" in the AST. You can read about them in the manual.
Bug Fixes for Attribute Rewriters
- December 9, 2025
- Patrick Ferris
There was a bug in the error handling for attribute rewriters -- a relatively new feature to have been added to ppxlib.
In some places, ppxlib makes use of a With_error.t monad. Unlike the Result.t monad, With_error.t allows you to collect errors rather than find the first error and thread it through your program. This can make sense if your program can meaningfully do work after encountering an error. Unfortunately, in the logic for replacing attributes, the code could not recover from an error where there were duplicate attributes.
Value binding constraints in ppxlib
- December 9, 2025
- Patrick Ferris
I spent a good few hours understanding why the CI tests in my PR to mirage/repr were still failing. It turns out, the bug, is fairly simple to reproduce. Consider the following OCaml code:
let g : int = 1
We have a let-binding that contains a type constraint. Where, in the abstract syntax tree sense, do we attach the constraint? Since OCaml 5.1, we have quite a few options for how this can be represented.
The first is using the Ppat_constraint AST node which allows you to attach a type constraint to any pattern.
    | Ppat_constraint of pattern * core_type
    (* (P : T)*)
This tends to be used for things like function arguments (e.g. fun (x : int) -> x + 1). So it doesn't quite capture what we want for this binding constraint.
On older OCaml compilers, let g : int = 1 also includes a Pexp_constraint on the body of the value binding. This makes sense if we consider a more general case of the syntax where we allow functions.
let g x : int = x + 1
In this example, we no longer parse a Ppat_constraint and instead this is treated as syntactic sugar for:
let g x = (x + 1 : int)
In OCaml 5.1 a new field for value bindings was added allowing type constraints to be tracked directly in the bindings themselves.
and value_binding =
  {
    pvb_pat: pattern;
    pvb_expr: expression;
    pvb_constraint: poly_constraint option;
    pvb_attributes: attributes;
    pvb_loc: Location.t;
  }(** [let pat : type_constraint = exp]*)
Our type constraint (: int) can be recorded in the pvb_constraint directly. This is a nice change, bringing the concrete syntax of the language closer to the parsetree. For ppxlib, however, it does create a bit of a headache as we now have to encode the different versions of expressing type constraints into the AST of the compiler before 5.1!
So what was the bug? The author's of repr had added some value bindings to circumvent some "unused value warnings" in OCaml. They choose to write these bindings like:
let (_ : int) = 1
Here, I have simplified the types and the body of the binding. The significant thing to notice is the parentheses surrounding the value binding's pattern. This forces the AST representation to be a single Ppat_constraint node regardless of the current compiler version. No Pexp_constraint and no pvb_constraint.
However, using ppxlib with a compiler less than 5.1 meant that this did not roundtrip cleanly. Instead, the value after passing through ppxlib's migrations was:
let _ : int = 1
After bottoming out at the issue, I discovered we already had a test case for this in ppxlib! Whatsomore, ocamlformat.0.20.0 (which repr was still using) actually transforms instances of let x : t = ... into let (x : t) = ...! This limitation does not seem inherent to the parsetree, the printer or the migrations. But I have asked the (very kind and friendly) previous maintainers about these changes.
Outreachy
- December 9, 2025
- Patrick Ferris
December 8th 2025 marks the start of the next round of Outreachy. I have been preparing some issues for geocaml/ocaml-tiff and I am excited to get started with Tambe Salome!
Graft and Bib [graft-and-bib-update]
- December 9, 2025
- Patrick Ferris
I spent some time at the start of the month updating and fixing Graft and Bib.
I added named subtrees to the markdown syntax. This allows users to create subtrees with headings that are also externally linkable.
With some more bug fixing, I hope to release both libraries before the new year!
Shelter imports [weekly-2025-w46]
- November 15, 2025
- Patrick Ferris
Most of this week was spent fixing bugs in Shelter in an attempt to get it ready to run the LIFE pipeline.
To do so, Shelter requires a mechanism by which to pull in files from the outside world. That could be configuration files, source trees, data etc. For now, this has taken the form of a crude @ import statement. In true Forester fashion, I have transcluded the foreign tree from my Shelter logs.
Eio Debugging [eio-cap-debugging]
- November 15, 2025
- Patrick Ferris
One of the promises of Eio's capability model is an improved debugging experience. Your program must be designed in such a way as to make resources explicit. If you have a load_config function, more than likely it will need access to the file-system.
val load_config : _ Eio.Path.t -> Config.t
(** [load_config path] loads a configuration from [path].*)
Once all of your resources are explicit and threaded through your program, it becomes much easier to swap out one resource for another (provided they have the same interface).
This week I was trying to get the LIFE pipeline running in shelter. Part of that involves pulling the appropriate geospatial container image, but my code was terrifically broken, failing with what looked to me with a Docker error.
With only this clue, I knew that it was probably in the execution of some command in a child process, but which one? To trace this quickly, I could plug in a slightly different instance of the _ Eio.Process.mgr capability. Essentially unchanged from the one provided by the unix backend except that it would also print to stderr the command it was trying to run!
let debug_process_mgr (mgr : 'a Eio_unix.Process.mgr) : 'a Eio_unix.Process.mgr
    =
  let module D = struct
    type t = unit

    let spawn_unix () ~sw ?cwd ?pgid ?uid ?gid ~env ~fds ~executable args =
      Eio.traceln "Spawning subprocess... %a" Fmt.(list string) args;
      Eio_unix.Process.spawn_unix ~sw ?cwd ?pgid ?uid ?gid mgr ~env ~fds
        ~executable args
  end in
  let module V = Eio_unix.Process.Make_mgr (D) in
  Eio.Resource.T ((), Eio_unix.Process.Pi.mgr_unix (module V))
Whist there is a fair amount of jumping through first-class-module-shaped hoops here, all I am doing is rewrapping an existing "method" to a spawn a unix child process. Then using this helper function, I can push that into my standard environment.
let env =
  Eio_unix.Stdenv.with_env
  ~process_mgr:(debug_process_mgr env#process_mgr)
  env
in
Shelter.main config (env :> _ Shelter.env) dir cmd_file
And sure enough I was querying for the Docker user before pulling the image! I hadn't run into this, as for the last while I have been using alpine and debian images that already exists locally.
Taking stock & Graft updates [weekly-2025-w45]
- November 10, 2025
- Patrick Ferris
I ended up working on a real mix of things last week. I managed to get two large posts uploaded to this site: an ICFP recap and a deeper-dive into the random bits of OCaml hacking. This was pretty useful in terms of taking stock of where I was at, I always find post-conference, I'm a little lost. The conversations and ideas from ICFP are simultaneously exciting but also pretty inactionable.
Graft Updates [graft-updates]
- November 10, 2025
- Patrick Ferris
It would seem that there is a potential second user of Graft! A great source of motivation for some tidying and feature implementing. At the end of last week I fixed some little bugs in Graft and (more importantly) allowed users to name their subtrees. Upstream Graft also now pins and uses my Bibtex implementation.
OCaml Geotessera
- November 10, 2025
- Patrick Ferris
As I discussed in my OCaml roundup, I spent a bit of time polishing the OCaml geotessera code. In particular this meant starting to handle low-level geospatial transformations allowing users to project latitudes and longitudes into the rows and columns of their raster data. I feel like I'm stumbling onto a path Michael has carved out with Yirgacheffe. I'm following along with his work excitedly and we had a good catch-up last week discussing how libraries should handle things like automatic, numeric precision conversion.
As a fully paid-up member of the static types fan club, I'm often evangelising the benefits of types. However, I hit a little quirk of the Nx library in OCaml (a numpy equivalent). Take a look at this sum function:
let sum nx = Nx.sum nx |> Nx.item [];;
val sum : ('a, 'b) Nx.t -> 'a
let arr = Nx.create Nx.int8 [| 2 |] [| 64; 64 |];;
val arr : (int, Bigarray.int8_signed_elt) Nx.t
sum arr;;
- : int = -128
Even though sum takes an ('a, 'b) Nx.t array that stores elements with representation 'b and allows you to read/write to the elements with OCaml values of type 'a, the sum function performs the calculation in the world of the 'b representation type (here signed 8-bit integers). So we get an overflow! Perhaps not too surprising but easy to overlook! The moral of the story is that we still need to be careful in the OCaml world too.
Shelter
- November 10, 2025
- Patrick Ferris
I did a little cleaning up of the Shelter code too. I noticed a few bugs from the demos I did at ICFP. Most were pretty straight-forward to fix, and the test-suite is now checking parallel for-loops and conditional execution are working.
This week
- November 10, 2025
- Patrick Ferris
I hope to get a few things done this week:
Deploy the Shelter daemon allowing other people to connect and take it for a spin.
Spend some time writing and reading, pulling ideas together rather than always writing code!
I have a slightly harebrained scheme that combines Shelter, atproto, Forester, capn(proto/web) and webcomponents... I want to see if I can pull that together.
Back to shelter [weekly-2025-07-18]
- July 18, 2025
Capnproto Interface to Shelter
- July 18, 2025
I spent some time this week thinking about decoupling Shelter's builds from the CLI tool. This would allow users to connect to a remote daemon to build and store their sessions, opening up the possibility of using Shelter on Windows and macOS.
The design so far keeps the metadata local, in an Irmin database. I will probably then augment the stored information with some kind of unique daemon identifier to know where the actual data is.
This is all still quite fresh, and I will have more by the end of next week.
OCaml-related Things
- July 18, 2025
Something I decided to do last week, was to make a clearer delineation between my OCaml work and research. That line is not always very distinct, but I have split of a separate set of weeklies for OCaml related things.
Fear not, the OCaml weeklies are a subset of these weeklies and so I will, when I remember, transclude them for you.
OCaml Weekly 2025 w29 [ocaml-weekly-2025-w29]
- July 15, 2025
- Patrick Ferris
Ppxlib
- July 15, 2025
- Patrick Ferris
I met with Nathan this week to discuss future plans for ppxlib. The current state of affairs is that ppxlib is becoming unmaintainable. This is primarily a knock-on effect from changes being made to OCaml's parsetree (e.g. labelled tuples being added in 5.4). Nathan has a plan that will provide two key properties.
Migrations, which allow old compilers to be used with new ppxlib releases, will be more compatible. For example, we will be able to migrate new features downwards and back up without raising an error.
Ppx authors will be able to use new features in an opt-in workflow, rather than ppxlib bumping the internal AST (like we did in ppxlib.0.36.0). This will reduce the maintenance burden significantly whilst still allowing users to write ppxes for new OCaml features.
I also started looking into some older issues in ppxlib related to performance. This is work-in-progress, but I am trying to improve the performance of some passes done by ppxlib. To better understand what was making ppxlib slow, I wanted to use runtime_events_tools but I was dismayed to see it wanting to install over 100 packages! I opened a PR to reduce the number of packages. I think this kind of work goes a little unrecognised as it is not very glamorous. However, I think it really benefits the OCaml community in the long run.
Outreachy
- July 15, 2025
- Patrick Ferris
In Outreachy news, we had a wonderful mid-internship video call with all the interns and mentors to catch-up on how everyone is getting along. Seeing the progress everyone has made was great! I am very grateful for the work that Michael and Steve have put in so far to make this a very successful Outreachy round for OCaml.
In sadder news, an email was shared with all Outreachy mentors detailing the increasingly critical financial situation the project finds itself in. There are ongoing discussions about how costs can be cut including potentially only running a single round a year.
Graft
- July 15, 2025
- Patrick Ferris
With the release of Forester.5.0, I made a plan to make a release of Graft.0.1. Unfortunately this is blocked by a new release of hilite, a tool I built for doing build-time syntax highlighting for OCaml code. This powers the syntax highlighting on ocaml.org.
PhD Work and Scientific Programming [rest-of-monthly-2025-06]
- June 30, 2025
- Patrick Ferris
I have been away on holidays. Some of that was spent hiking in the Massif de Calanques in Marseille, unfortunately this week they were on fire. Anyway, this "weekly" fills in the blanks for the rest of June 2025.
Revisiting hazel_of_ocaml
- June 30, 2025
- Patrick Ferris
I spent some time thinking and writing about hazel_of_ocaml and the benefits of OCaml as source language and Hazel as a target language. The stability of OCaml with a powerful type-system makes it very expressive.
Hazel, on the other hand, is a hotbed of PL theory research. The typed holes, which are fully supported within the language, are particular powerful targets for a transpiler. They allow transpiler developers to incrementally support the language whilst still getting full feedback of their generated source code. Whilst it is a niche use-case, I thought it was an interesting point to note.
A second year report
- June 30, 2025
- Patrick Ferris
I wrote my second year report at the end of June. The process was a bit chaotic, but I think ultimately it was useful for clarifying some ideas I had rattling about in my head.
Part of that was working on my publications page and, through a conversation with Anil, realising that my work on Graft was in many ways a part of my own research.
If you are interested, feel free to peruse both my first year and second year reports. Take them with a pinch of salt! I think it is useful to be fairly open with this sort of thing when you can be. Maybe someone will find them useful.
What is scientific programming?
- June 30, 2025
- Patrick Ferris
This question arose whilst writing my second year report. It got me thinking about how we distinguish scientific programming from other kinds of programming. I came across a paper by Tim Storer: Bridiging the chasm: A survey of Software Engineering Practice in Scientific Programming. I enjoyed a few aspects of this paper.
Relating scientific programming to the scientific method so directly was pretty useful insight for me. Falsifable hypotheses, repeatable experiments and reproducible results when applied as characteristics of the computer stack (e.g. OS, programming language, filesystem etc.) might be a useful lens to argue for better tools to enable this.
The breadth of Storer's case-study analysis on how scientific programming has "gone wrong" is very good, if anyone needs a reference to draw on to help support their tools or research, this seems like a good index to use.
Ppxlib
- June 30, 2025
- Patrick Ferris
I was reminded again of the pain of helping maintain ppxlib. We are coming to the conclusion, that in its current form, it is becoming unmaintainable. I took a stab at updating bisect_ppx to the latest ppxlib. With OCaml entering a potentially turbulent parsetree era, it might be time to take stock of this and propose some fillers to help. Nathan Rebours and I are meeting next week to discuss ideas he has to make parsetree migrations smooth sailing for all!
Geocaml
- June 30, 2025
- Patrick Ferris
Work on ocaml-tiff has stalled, which is totally fine. Michael and I independently are working on other things and have obligations to fulfill. Maybe some day we'll carve out enough time together to push forward on this project, but not this week.
Forester as a Target Syntax [weekly-2025-06-02]
- June 2, 2025
- Patrick Ferris
This week included some time finishing opentrace and subsequently folding it into shelter. I have been writing up some more of the draft paper for shelter which I am excited to share in the near future.
I revisited the upgrading vpnkit PR and pushed some more fixes. I have been thinking, again, about the promise of a direct-style world for OCaml that just hasn't quite landed yet. C'est la vie.
Forester and Graft
- June 2, 2025
- Patrick Ferris
I spent a bit of time finally pulling out my changes to Forester to add markdown and bibtex support into a standalone tool: graft.
Graft [graft]
- June 2, 2025
- Patrick Ferris
- https://github.com/patricoferris/graft
Graft is a Forester preprocessor.
It takes a forester (a directory of trees) written in a mixture of Markdown, Bibtex and Forester syntax and produces a new forest completely written in Forester syntax.
Usage
- June 2, 2025
- Patrick Ferris
graft simply preprocesses a forest generating Forester trees from .md, .bib and .tree files. It will copy the structure of the input directory in the output directory.
$ graft preprocess --output=grafted-trees trees
$ forester build
This assumes that you have updated your Forester toml file to put the grafted-trees directory as your source of trees.
[forest]
trees = [ "grafted-trees" ]
Example
- June 2, 2025
- Patrick Ferris
A typical "tree" might look something like
---
title: Opentrace and Supervisions
date: 2025-05-26
author: Patrick Ferris
---

Over the past two weeks I have mainly split my time (amongst many things) developing [opentrace](open-trace)
and doing revision supervisions.

```forester
\put\transclude/numbered{false}
\transclude{open-trace}
```
A few things to note:
The
yamlfrontmatter allows you to add some of the metadata fields from Forester.At any point in your markdown there is an escape hatch to Forester using a
forestercodeblock.
It is very satisfying to find the separation of concerns works quite well. For a while I had been rebasing my development branch on Forester. I was also worried about trying to get the code upstream as it pulled in many dependencies. It seems that I have a very workable solution. I welcome contributions to graft including extra input formats. I am also considering extending the Forester configuration to contain some graft configuration for how it should generate new trees (e.g. at the moment every entry in a bibtex file is given a new tree).
Maths Support
- June 2, 2025
- Patrick Ferris
As part of that process, graft now supports Markdown KaTeX. For example:
Definition. Mergeable Replicated Data Type Implementation [mrdts]
- Patrick Ferris
A mergeable replicated data type (MRDT) implementation for a data type \tau is a tuple D_{\tau } = (\Sigma , \sigma _{0}, do, merge) where:
\Sigma is the set of all possible states at a branch,
\sigma _{0} \in \Sigma is the initial state,
do : Op_{\tau } \times \Sigma \times Timestamp \rightarrow \Sigma \times Val_{\tau } implements every data type operation,
merge : \Sigma \times \Sigma \times \Sigma \rightarrow \Sigma implements the three-way merge strategy.
Definition 2.1 from "Certified Mergeable Replicated Data Types".
Revision Supervisions
- June 2, 2025
- Patrick Ferris
I have been doing revision supervisions for Discrete Maths and Foundations of Computer Science. I have also been marking Operating Systems past paper questions for the same group of first years.
Opentrace and Supervisions [weekly-2025-05-26]
- May 26, 2025
- Patrick Ferris
Over the past two weeks I have mainly split my time (amongst many things) developing opentrace and doing revision supervisions.
Opentrace [open-trace]
- May 19, 2025
- Patrick Ferris
- https://tangled.sh/@patrick.sirref.org/opentrace
Thanks to Koonwen's excellent libbpf bindings in OCaml, I have been building a little tool called opentrace to make it easier to track an executable's inputs and outputs.
This work was inspired my Michael's self-proclaimed "gross hack": pyshark. Whilst pyshark achieves its goals by injecting code into commonly used python objects and methods, opentrace uses eBPF. By using a lower-level API (hooks in the kernel), opentrace can remain programming language agnostic. However, less information is none about the user's intent compared to something like pyshark.
Monitoring the System
- May 19, 2025
- Patrick Ferris
opentrace has an all command that will trace the entire system.
$ sudo opentrace all --flags=O_WRONLY
pid,cgid,comm,kind,flags,mode,filename,return
16324,4417,".nheko-wrapped",openat,577,438,"/home/patrick/.cache/nheko/nheko/curl_alt_svc_cache.txt",47
16324,4417,".nheko-wrapped",openat,193,33188,"/home/patrick/.cache/nheko/nheko/cr3ZUHqBErIOe3PlwJ1SuU8zFKKxL12VzrRoHYMH.tmp",47
16324,4417,".nheko-wrapped",openat,577,438,"/home/patrick/.cache/nheko/nheko/curl_alt_svc_cache.txt",47
16324,4417,".nheko-wrapped",openat,193,33188,"/home/patrick/.cache/nheko/nheko/QfZTdZSuC56NdcDQ3aMxJc3BhMhAj8PmtYW1zFDP.tmp",47
2530,4235,"systemd",openat,524865,438,"/sys/fs/cgroup/user.slice/user-1000.slice/user@1000.service/app.slice/gammastep.service/cgroup.subtree_control",41
2530,4235,"systemd",openat,524545,0,"/sys/fs/cgroup/user.slice/user-1000.slice/user@1000.service/app.slice/gammastep.service/memory.min",41
2530,4235,"systemd",openat,524545,0,"/sys/fs/cgroup/user.slice/user-1000.slice/user@1000.service/app.slice/gammastep.service/memory.low",41
2530,4235,"systemd",openat,524545,0,"/sys/fs/cgroup/user.slice/user-1000.slice/user@1000.service/app.slice/gammastep.service/memory.high",41
2530,4235,"systemd",openat,524545,0,"/sys/fs/cgroup/user.slice/user-1000.slice/user@1000.service/app.slice/gammastep.service/memory.max",41
The --flags=O_WRONLY argument filters the events where the O_WRONLY flag was set in the call to open.
We also get the name of the current executable linked to the task (comm). The -wrapped is an artefact of using Nix.
Tracing an Executable
- May 19, 2025
- Patrick Ferris
The primary use case for this tool is to inspect what files your program might be reading and writing.
$ sudo opentrace exec --format=json --flags=O_CREAT -- opam list
$ cat trace.json | jq ".[] | .fname"
"/home/patrick/.opam/cshell/.opam-switch/packages/cache"
"/home/patrick/.opam/log/log-118747-29da3d.out"
"/home/patrick/.opam/log/log-118747-29da3d.err"
"/home/patrick/.opam/log/log-118747-29da3d.env"
"/home/patrick/.opam/log/log-118747-29da3d.info"
The "flags" argument can specify a small boolean formula for checking the open flags of a particular event with | (or), & (and), and ~ (not). Parentheses can be used for precedence.
$ sudo opentrace exec --flags="O_WRONLY|O_RDONLY" -- ocaml --version
Spawning Subprocesses
- May 19, 2025
- Patrick Ferris
One feature opentrace needs (in this proof-of-concept phase) is the ability to also trace subprocesses.
opentrace is primarily an eBPF program that is loaded into the kernel and communicates with an OCaml program. Events are communicated via a ring buffer and most of the post-processing happens in OCaml. To capture subprocesses, opentrace creates a new control group (cgroup) and places the new process into that group. This gives opentrace a new identifier to track, namely the cgroup.
So consider the following program.
let () =
  Eio_posix.run @@ fun env ->
  Eio.Path.(save ~create:(`Or_truncate 0o664) (env#fs / "hello.txt") "hello");
  Eio.Process.run env#process_mgr
    [ "/bin/bash"; "-c"; "echo 'heya' > heya.txt" ]
It first creates a file using direct calls to functions like openat. Then it spawns a process which creates a new file called heya.txt. This happens in a separate process. However, with the --cgroups flag we can capture both interactions with the operating system.
$ sudo opentrace exec --cgroups --flags="O_CREAT|O_TRUNC" ./main.exe
pid,cgid,comm,kind,flags,mode,filename,return
153187,530807,"main.exe",openat,526914,436,"hello.txt",5
153192,530807,"bash",openat,577,438,"heya.txt",3
Eio's Process API
- May 19, 2025
- Patrick Ferris
I have used the Eio_unix fork action process API to be able to extend what happens in the child process. Loading most eBPF programs into the kernel requires special privileges hence the need for sudo. When a user requests for a particular program to be executed and traced, opentrace spawns a process via the Eio Process API. Opentrace defines a few new so-called "fork actions", little fragments of C code that are run after the call to fork (clone). Most likely this ends with a call to execve, but other calls are possible for example setuid allowing opentrace to change the user of the child process so it does not run as root. Similarly, this is where (if used) we create the cgroup and place the process into that group.
Limitations: Io_uring
- May 19, 2025
- Patrick Ferris
Whilst testing opentrace against some of the tools I use nearly daily, I noticed some events were being missed. I tried tracing forester, and only the initial read of forest.toml was logged. It dawned on me that the reason for this was that forester (via eio) was using io_uring to perform most of the IO. Most attempts to open files were bypassing the open system calls, and instead they were being performed by the kernel after reading a submission request for an openat2-style call!
This is not news to seasoned, Linux systems programmers. Io_uring bypasses SECCOMP filters for exactly the same reasons.
$ sudo opentrace exec -- forester build
$ cat trace.csv
pid,cgid,comm,kind,flags,mode,filename,return
155007,535570,"forester",openat,524288,0,"forest.toml",5
155007,535570,"forester",Uring,2621440,0,"",0
155021,535570,"cp",openat,131072,0,"/home/patrick/documents/forest/theme/favicon-32x32.png",4
155007,535570,"forester",Uring,2686976,0,"",0
155007,535570,"iou-wrk-155007",Uring,557634,420,"",0
155007,535570,"iou-wrk-155007",Uring,557634,420,"",0
155007,535570,"iou-wrk-155007",Uring,557634,420,"",0
It is interesting to note two things here:
We can tell that forester reads the configuration file probably using something like
In_channelin OCaml (it does).It appears that Uring is performing IO in both worker threads and directly.
The file paths are empty at the moment as I cannot find a clean way to trace openat submission requests into Uring without it sometimes going very wrong. I have tried quite a few methods (e.g. tracing do_filp_open) and at the moment I am tracing io_openat2, but this seems quite brittle, and often the filename is completely garbled, so I do not set it. If anyone has any ideas to trace Io_uring more reliably, I am all ears!
Supervisions
- May 26, 2025
- Patrick Ferris
The first year students I teach will be doing their first year exams soon. I have been helping them revise for foundations of computer science and discrete mathematics. Whilst doing so, I have been thinking a good deal about Jon Sterling's post about assessment bureaucracy. In particular:
At moments like this, it is a good idea to pause and reflect on whether it is better for our students that each faculty member spend a cumulative two months doing literally nothing but assessment and higher-order practices related to assessment, vs. other activities that could benefit our students more (including actual teaching, of which we do astonishingly little at Cambridge).
Metashells [weekly-2025-05-12]
- May 19, 2025
- Patrick Ferris
This week, I feel I have been stuck fighting the OCaml ecosystem trying to keep my OxCaml work afloat. Aside from that, Ryan and I made some really nice progress with Shelter, culminating in Ryan describing it as a metashell.
Shelter the metashell
- May 19, 2025
- Patrick Ferris
The main progress this week with Shelter was composing runc's terminal mode with entering raw terminal input mode on the Shelter side. This is inspired by Ryan's own work on capability interfaces.
Shelter remains mostly intact, acting as an interactive shell. However, just before executing a command we switch to receiving and sending raw terminal inputs and outputs. This means tools like vim now work in Shelter! Not only that, but users can now activate an inner shell (e.g. zsh) and enjoy all the usual features of a fully-fledged shell (tab complete, fuzzy history search etc.) and upon exiting that shell, Shelter will snapshot the session. This lets you alter the granularity of snapshots from the command-line.
Louis Pouzin's "SHELL" [pouzin-shell]
- May 19, 2025
- Patrick Ferris
I spent some time reading part of the multics design documentation this week. Louis Pouzin coined the term "SHELL" in this document, and I was reminded yet again just how important it is to be a good writer even as a "computer science researcher". For example, this excerpt from the requirements section of the document
The previous definitions imply that a command MUST be designed while keeping in mind the user, sitting at his console, wondering about what might be going on, mistyping or forgetting arguments, even if fully aware of the conventions, and possibly interfering with the command by hasty quits, carriage returns, and other temperamental reactions.
And then later, when defining the "SHELL".
We may envision a common procedure called automatically by the supervisor whenever a user types in some message at his console, at a time when he has no other process in active execution under console control (presently called command level). This procedure acts as an interface between console messages and subroutine. The purpose of such a procedure is to create a medium of exchange into which one could activate any procedure, if it were called inside of another program. Hereafter, for simplification, we shall refer to that procedure as the "SHELL".
It still surprises how little the undergraduate degree in computer science at Cambridge focuses on writing skills.
OxCaml
- May 19, 2025
- Patrick Ferris
Last week, I got a toplevel with OxCaml working. This required a serious amount of work to understand the changes Janestreet have made to obscure parts of the OCaml compiler and then working those into tools like js_of_ocaml.
This week, Janestreet pushed their latest rounds of changes and of course everything broke! I spent some more time fixing it all back up. I'm not entirely sure how maintainable this is. The problem is that, whilst things compile, the programs do not work together! Only when someone uses the program do the bugs surface.
Other OCaml Work
- May 19, 2025
- Patrick Ferris
I worked on some other parts of the ecosystem this week.
Ppxlib
- May 19, 2025
- Patrick Ferris
I helped review some changes to enable Janestreet to have ppx rewriters via attributes (usually they are via extension points). It is a bit of a controversial change to ppxlib as we try to keep the API predictable for users:
Extension points are rewritten: this means the part that is rewritten is nicely delimited by the extension points start and end.
Attributes extend: attributes do not rewrite the code they are attached to but rather extend the code with new AST nodes.
Tiff
- May 19, 2025
- Patrick Ferris
I spent some time trying to speedup the LZW decompression of TIFF files in the pure OCaml tiff library this week(end). The two big changes to help with this are pretty common when speeding up these parts OCaml programs:
Allocate less
Does less work
In terms of allocating less, the original implementation was using a char list to represent LZW strings. Manipulating these becomes quite costly, particularly since the most common operation is appending a single character to the end of a list. Converting this to use OCaml's immutable string saved a ton of allocations.
In terms of doing less work, I opted to bypass Cstructs sane (but slow) bounds checks in some of the "hotter" parts of the code. In particular, LZW ends up reading potentially huge arrays full of bytes one-by-one. So reading each byte needs to be quite snappy. This is a bit of a trade-off in terms of "safety" but we are in control of this code so I'm not too worried about that.
Here are some results decompressing a fairly large array of some elevation data.
before: | tiff/lzw/cea │ 523851.2259 mjw/run │ 3289761.5414 mnw/run │ 9806796.7121 ns/run│
after:  │ tiff/lzw/cea │  27846.2408 mjw/run │  587928.7527 mnw/run │ 8457161.3761 ns/run│
Hazel and OxCaml [weekly-2025-05-04]
- May 10, 2025
- Patrick Ferris
I missed a week of posting last week, mainly because I spent more time writing posts.
Hazel of OCaml
- May 10, 2025
- Patrick Ferris
I mentioned previously that I was building a tool to transpile OCaml code to Hazel. This work is now in a good enough state that, along with one of my students, we have transpiled a good number of OCaml programs to help them write their evaluation for their third-year project.
I wrote up a little summary of that work, which I've transcluded below.
A Transpiler from OCaml to Hazel [hazel-of-ocaml]
- May 2, 2025
- Patrick Ferris
Over the past few months, I have been piecing together a transpiler from Hazel to OCaml. This is, in part, to help one of my third-year undergraduate students who is working on type error debugging in Hazel.
Typed Holes
- May 2, 2025
- Patrick Ferris
Hazel is a functional programming language with typed holes. Holes are pieces of your program that have not yet been filled in. Holes can appear anywhere in your program both as expression or types. Hazel can still evaluate your program in the presence of holes.
To get a flavour of Hazel, take a regular map function for lists.
let map = fun f -> fun xs -> case xs
  | [] => []
  | x :: xs => f (x) :: map(f)(xs)
end in
map(fun x -> ?)([1, 2, 3])
The question mark (?) is a hole. The program evaluates to the following expression of type [?] (for people more familiar with OCaml types ? list).
[ ?, ?, ? ]
Hazel supports local type inference but nothing involving unification variables. For example, a simple add_one function in Hazel (fun x -> x + 1) has type ? -> Int.
From OCaml to Hazel
- May 2, 2025
- Patrick Ferris
The ability to transpile OCaml programs to Hazel programs is motivated by one simple thought: there are more OCaml programs than there are Hazel programs. This could help bootstrap projects by alleviating the need to rewrite boilerplate code (e.g. URI parsing or standard library functions for strings).
A Transformation of Syntax
- May 2, 2025
- Patrick Ferris
Hazel markets itself as an "Elm/ML-like functional programming language". From the previous example of map, it should be apparent just how close to OCaml the language is.
It turns out that a majority of the transpiler is a transformation of syntax. Take a simple ADT for an arithmetic programming language.
type expr =
  | Float of float
  | Add of expr * expr
  | Sub of expr * expr
  | Mul of expr * expr
  | Div of expr * expr
And when we run hazel_of_ocaml over this OCaml type declaration.
type expr =
  + Float(Float)
  + Add((expr, expr))
  + Sub((expr, expr))
  + Mul((expr, expr))
  + Div((expr, expr))
 in ?
Not much has changed expect some syntax. Hazel does not have a notion of top-level expression so hazel_of_ocaml wraps the program into one set of value bindings. For the most part, Hazel acts as a subset of the pure, functional part of OCaml. At the time of writing, this subset is fairly limited with no support for modules or labelled records out of the box (there are plenty of development branches with these features).
If we try out the same map function but written in OCaml and transpiled to Hazel we get.
let rec map f = function
  | [] -> []
  | x :: xs -> f x :: map f xs
Which becomes the following hazel program.
let map = fun f -> fun x1 -> case x1
  | [] => []
  | x :: xs => f(x) :: map(f)(xs)
end in ?
We could have a field day discussing the syntax of OCaml and Hazel (parentheses for function arguments, well-scoped cases for pattern-matching, a different arrow for pattern-matching etc.). What would be more interesting is taking a look at how to handle polymorphism in Hazel.
Explicit Polymorphism
- May 2, 2025
- Patrick Ferris
Hazel has explicit polymorphism. So far, we have not seen it as we have let the types have holes in them. The map function in OCaml has the following type.
val map :
  ('a -> 'b) -> 'a list -> 'b list
We must remind ourselves (by reading Craig's excellent blogpost on the matter) that in OCaml
... type variables in signatures are implicitly universally-quantified
So in reality, we have that map has the following type.
val map : ∀ a b. (a -> b) -> a list -> b list
In Hazel, we have to explicitly type our map function to be polymorphic. Not only does this mean the type annotation requires universally quantified type variables, but we must also perform type application wherever we choose to apply the map function (whether that be recursively or somewhere later in our program).
let map : forall a -> forall b -> (a -> b) -> [a] -> [b] =
  typfun a -> typfun b -> fun f -> fun xs -> case xs
    | [] => []
    | x :: xs => f (x) :: map@<a>@<b>(f)(xs)
end in
map@<Int>@<Int>(fun x -> ?)([1, 2, 3])
forall introduces a universally quantified type variable into our type annotation, and typfun introduces it into the function itself (à la System F). Type application requires @<T> where T is some type. This allows hazel to quite easily support higher rank polymorphism, but we will not worry too much about that.
Propagating OCaml Types into Hazel
- May 2, 2025
- Patrick Ferris
Most often, OCaml users interact with prenex polymorphism (rank-1) where the universal quantifiers are at the front of the type. OCaml does support quantifiers inside certain types like records.
What this means for the transpiler is that we can reuse OCaml's type inference to safely instantiate the correct type annotations and type applications in Hazel! To do this, hazel_of_ocaml uses Merlin to inspect the type of the function in either a value binding or at the point of a function application.
Take a simple, polymorphic length function.
let rec length = function
 | [] -> 0
 | _ :: xs -> 1 + length xs

let int_len = length [ 1; 2; 3 ]
let str_len = length [ "only"; "two" ]
When we run this through hazel_of_ocaml with the -type flag we get.
let length : forall a -> [a] -> Int = typfun a -> fun x1 -> case x1
  | [] => 0
  | _ :: xs => 1 + length@<a>(xs)
end in
let int_len : Int = length@<Int>(1 :: 2 :: [3]) in
let str_len : Int = length@<String>("only" :: ["two"])
in ?
hazel_of_ocaml has correctly instantiated the type for length inside the recursive function and then in each case with the integer list and the string list.
A Corpus of Hazel Programs
- May 2, 2025
- Patrick Ferris
The impetus for this work was to derive a corpus of ill-typed Hazel programs. Luckily, such a corpus exists for OCaml! Seidel et al. created a corpus of OCaml programs from their undergraduate students at UC San Diego. Some of these programs have been transpiled to Hazel.
Future Work
- May 2, 2025
- Patrick Ferris
Hazel is a fun, research programming language. Potential third-year students may find it interesting to take this work further. For example, how would this look in terms of a module system? From a purely engineering perspective, plenty of work would be needed to convert a multi-library OCaml project to Hazel (e.g. handling the cmi files).
Another line of research would be to have Hazel target one of the intermediate representations in OCaml which would give Hazel a fully functioning compiler to "native" code?
OxCaml
- May 10, 2025
- Patrick Ferris
I spent some time this week getting more familiar with Oxidized OCaml. I have a habit of wrapping new OCaml tools and libraries into toplevel, browser applications. For example, try-irmin and try-eio.
Naturally, I tried to wrap OxCaml into a toplevel so people could play around with the new modes that are part of the OxCaml type system. This turned out to be a lengthy debugging session (where type declarations did not align so the raw Obj.repr js_of_ocaml representation was broken for some parts of the toplevel). I would say that I do question the time-spent/value trade-off, but a mostly working toplevel with OxCaml is available at: https://patrick.sirref.org/oxcaml.
Shelter in the Forest [weekly-2025-04-21]
- April 21, 2025
- Patrick Ferris
I spent much of this week working on Shelter and things related to it. Some of that time was also spent on Forester.
Forester
- April 21, 2025
- Patrick Ferris
I added two important quality-of-life features to my frontend to Forester this week.
Bibtex Support
- April 21, 2025
- Patrick Ferris
I had previously mentioned adding support to Forester for Markdown. This week I added support for Bibtex too. From any *.bib file in your forest, Forester will now dutifully recognise it as a Bibtex file and convert, as best it can, all the entries into Reference trees.
I'm becoming quite convinced of this model at the moment. I'm using Forester's Code.t as a target representation. In fact, to ease the process, I really shouldn't spend all my time on my website, I have reused my Yaml.t -> Code.t and Markdown.t -> Code.t functions in the Bibtex parser.
To see it in action, you could have a look at the Build Systems à la Carte paper which is generated completely from Bibtex.
Full Heading Support
- April 21, 2025
- Patrick Ferris
The eagled-eyed viewer may have noticed that the table of contents for this page has more than one level. I finally caved and spent an evening rejigging my Cmarkit.Doc.t -> Tree code which was hacky and broken and is now less hacky and less broken.
In addition, headings support links and emphasis etc.
Lunch with Jon Sterling
- April 21, 2025
- Patrick Ferris
I had a delightful lunch with Jon Sterling discussing the future of Forester, the nature of the Web (old and new) and the success posting weekly updates for our colleagues. Thanks Jon.
Shelter Fixes
- April 21, 2025
- Patrick Ferris
I spent a good chunk of my week fixing bugs in Shelter with the aim to perhaps setup a VM somewhere and let people kick the tyres of what we've got so far.
The first bug is pretty annoying. At the moment, our filsystem backend is ZFS and we make heavy use of snapshots and cloning in order to provide time-travelling capabilities. Unfortunately, ZFS will take a snapshot before data has fully made it to disk (or whatever is the equivalent point it should reach in ZFS). Commands that generated lots of disk activity would be snapshotted in a half finished state and this would cause all sorts of problems. Thanks to Mark Elvers for the pointer to how OBuilder uses ZFS for the OCaml macOS builders which unmount datasets immediately therefore inducing a flush of sorts. Shelter now follows a similar model with all of the slow downs that create. Anil and I discussed some amalgamation of overlayfs, tmpfs and ZFS to alleviate some of this but for now that's a premature optimisation.
A small eDSL for Shelter
- April 21, 2025
- Patrick Ferris
Whilst testing Shelter, I ended up wanting a way to programmatically invoke the different run commands. This is similar to say a Dockerfile, but maybe with a little more expressivity.
This lead me to revisit the Build systems à la Carte paper and rediscover selective applicative functors.
I started playing around with a selective applicative interface to Shelter, this would allow you to express your dependencies statically but select them dynamically (as the paper says).
module D = Shl (Identity)

let shelterfile =
  let open D in
  let base_image = from "alpine" in
  let is_node_lst img = String.equal "v22.15.0" (stdout img) in
  let cmds base =
    let node_version = run "node --version" base in
    Select.if'
      (Select.map ~f:is_node_lst node_version)
      (run "node -e 'console.log('success!')")
      (run "node -e 'console.log('failure!')")
      base
  in
  with_session "node" (cmds base_image)
From this, we get a slightly more expressive way to describe images.
Geocaml TIFF Library
- April 21, 2025
- Patrick Ferris
I was pleasantly surprised to receive a pull request from Michael adding support to ocaml-tiff for reading TIFF files compressed using LZW. I was also surprised to hear the TIFF LZW is a little different to others.
In trying to get this PR merged, I moved the initialisation of the Eio eventloop to outside each individual test case. This one change then completely broke the entire test suite. After a period of debugging and help from Thomas Leonard the root cause was OCaml's OUnit2 library using process-level parallelism (via Unix.fork), sharing the ring between the parent and the child lead to the issues.
Part II Students
- April 21, 2025
- Patrick Ferris
As the new term begins, it signals that there are only just over two weeks for the final year undegrads at Cambridge to submit their dissertations.
The four students that I help supervise have been sending me drafts of their work (and reminder you can read about their projects) and I'm very impressed. I'm sure the next two weeks will be stressful, but I'm proud of what they have accomplished over the past academic year.
Catching Up! [weekly-2025-04-14]
- April 21, 2025
- Patrick Ferris
This is a bit of a catch-up post. A week or so in Belfast has thrown me a little off course with the weeklies.
Outreachy December 2024 and Beyond
- April 21, 2025
- Patrick Ferris
In the last week or so, we have come to the end of the December 2024 round of Outreachy. For those who do not know about Outreachy, it facilitates and organises internships in open-source. Internships for those who are historically underrepresented and impacted by systematic bias in tech.
We, the OCaml community, held our biannual Demo Day where our current cohort of interns can show off what they have been building for three months. This round, we only had one intern, Abdulaziz, who worked on the OCaml API diffing tool.
The next round has just completed the contribution phase and our next cohort of interns is being selected.
Ppxlib Supports OCaml 5.4 (mostly)
- April 21, 2025
- Patrick Ferris
This week, I added support for OCaml 5.4 to ppxlib. A rather non-trivial change to the codebase due to changes in the representation in Longidents (which now have location information for all segments of the Longident). OCaml 5.4 has labelled tuples, a light-weight record-like syntax similar to labelled arguments in functions.
let x = ~x:1, 10, ~y:1
val x : x:int * int * y:int

let add (~x, ~y) = x + y
val add : (x:int * y:int) -> int
As of writing this post, we are waiting for the full OCaml 5.4 feature freeze and magic number bump. Note this is support for OCaml 5.4 (in ppxlib terms, we know have migration functions for 5.3 <-> 5.4) not a bump to use the 5.4 parsetree in ppxlib.
The Future of Ppxlib
I have now been helping maintain Ppxlib for a while and I am beginning to wonder about the long-term vision for the project. Ppxlib is a central component to any modern OCaml library or tool, Sherlocode reckons there's 18.3k instances of [@@deriving. Yet, every compiler release is a painful, two-phase process for the maintainers. First, we have to support the new release of the compiler. This is mostly okay but does involve adding lots of code to Ppxlib (we need a whole copy of the Parsetree!). Later on down the line, we have to bump the AST and this often breaks many ppxes.
The biggest issue is still the tension between abstract types and pattern-matching. By exposing the Parsetree directly to user's, they can pattern-match against the AST and build their ppxes in a rather straight forward way. However, this comes with the risk that the type may change thus breaking their code.
I have mentioned before about plans to use "views" to help with this, but I do not see that happening any time soon. It feels to me, we should be able to allow a user to select their AST to work with. How this interacts with modules like Ast_builder is unclear to me, but it would mean user's can remain on older ASTs even when ppxlib bumps the internal, main AST.
Sherlorocq
- April 21, 2025
- Patrick Ferris
Rocq is a theorem prover (originally called coq) from many of the same folks who brought you OCaml. I have been interested in theorem provers for a while, more from an engineering perspective and less from a theoretical one. My good friend, Derek Sorenson, taught me about Rocq when we encoded mergeable replicated datatypes. Later I had a go at encoding decentralised information flow control (also in Fstar).
During this process, I found it quite challenging to find Rocq code that I could learn from. Compared to using say OCaml's Stdlib, using Rocq's standard library of datatypes and proofs did not come naturally (not helped by the fact that at the time I could not get the LSP to play ball).
This lead me to port Arthur Wendling's excellent Sherlocode to do the same thing only for Rocq code. Luckily, it uses regular expression matching with a trigram index so it is not tied to any particular programming language. Additionally, it is somewhat opam-centric (not actually that much) which is perfect for Rocq!
Anyway, I've had some interest from the people at Inria to bring the server back to life. Their wish is my command!
Sherlorocq is back online!
Shelter, Hazel and More! [weekly-2025-03-31]
- March 31, 2025
- Patrick Ferris
Last week I focused on Shelter -- our idea that shells should have the same ability as reproducible build tools like Nix or Docker. To this end I now have a fairly fleshed out prototype.
Shelter Prototype
- March 31, 2025
- Patrick Ferris
Forester Hacking
- March 31, 2025
- Patrick Ferris
As you can probably tell, my website is still using Forester. I rebased my Markdown branch to include the new Atom syndication feature.
Alongside that I added support for arbitrary HTML injection into Forester via codeblocks in Markdown. This was actually very straightforward thanks to Markup and being able to re-parse Forester syntax in the middle of converting a Markdown document. The HTML for the shell in Shelter uses this feature.
If you are interested in taking this custom Forester for a spin, there's a branch on Github. In fact, nearly the only change beyond letting the core engine know about markdown files, is adding a new parser frontend.
Hazel
- March 31, 2025
- Patrick Ferris
For one of my Part II students, I've been prototyping a transpiler from OCaml to Hazel. This has gone pretty well and now supports type annotations as well as straight-forward implementation translation.
Consider the following OCaml map function.
let rec map f = function
  | [] -> []
  | x :: xs -> (f x) :: map f xs
The tool, hazel_of_ocaml can translate this to Hazel code, including making the polymorphism explicit.
let map : forall a -> forall b -> (a -> b) -> [a] -> [b]
  = typfun a -> typfun b -> fun f -> fun x1 -> case x1
  | [] => []
  | x :: xs => f(x) :: map(f)(xs)
end in ?
You can copy and paste that codeblock into the hazel playground. But do note that it still needs some manual editing to add the type applications in directly (map@<a>@<b>). With the right amount of type-inferencing and scoping I actually think that you could place those type applications in yourself. This could make a nice Part II project I think.
Ppxlib
- March 31, 2025
- Patrick Ferris
I recently wrote about the painful experience of miragrating ppxlib to the 5.2 OCaml AST. This week, Nathan Rebours and I merged a PR to add the 5.3 AST! Ppxlib has been playing catch-up with the compiler and we decided it was best to try to catch up quickly and deal with the ecosystem fallout all at once rather than incrementally. With this new AST merged, ppx authors can now use the new Pexp_effect parsetree node. I'll write a little more about this in a separate post soon.
Vpnkit, Void Processes, LSP Servers [weekly-2025-02-17]
- February 17, 2025
Previous weeklies used strong emphasis to distinguish sections. This comes from Forester's philosophy about atomicity of the content in your forest.
However, subtrees are supported! I quickly hacked together the ability to use subheadings to indicate subtrees. This is strictly less expressive than the \subtree{} of Forester's default syntax as we cannot close heading sections in Markdown.
This weekly uses subtrees.
Vpnkit
- February 17, 2025
I spent some time this week trying to upgrade vpnkit to OCaml 5. I was originally working on a paper idea which might need benchmarks, but Anil and I decided we could simply point to the port I did and show how it has simplified much of the code.
Void Processes [void-processes]
- February 17, 2025
Work continued on implementing (and fully exploring) void processes. A lot of the groundwork already exists in Jake Hillion's master's thesis.
This week I added a feature that I needed to help build the processes we need for the shell I'm building: mount points with modes!
In addition to the root mount (taken care of with pivot_root), we need to be able to add additional mounts into the process' environment. These can now be added. All mount points can be mounted readonly or readwrite.
Here is the "Hello, World!" example (the /say/hey program has been statically compiled using musl-gcc).
let status =
  let void =
    empty
    |> mount ~mode:R ~src:hey_dir ~tgt:"say"
    |> exec [ "/say/hey" ]
  in
  let t = Void.spawn ~sw void in
  Promise.await (Void.exit_status t)
There really is nothing else in there. Without specifying a root mount, the void process is started with an empty tmpfs root. Next on the list is networking!
LSP Servers
- February 17, 2025
I got a little side-tracked building a library for writing LSP servers in OCaml: mlsp. This may seem a little unrelated, but it isn't. The LSP has become the de facto standard for communicating between an editor and a programming language environment. If you have used VSCode to write a program in Python, chances are you are using the official extension which gives you linting, formatting, code navigation etc. All of these features are communicating using the LSP.
It seems Code Mirror can already proxy over a websocket for LSP support too (we might not even need that as we can compile OCaml directly to JavaScript/Webassembly and have the whole thing running locally!).
Open-Source & Community
- February 17, 2025
Anil and I had a great conversation this week about building community especially as it pertains to open-source and OCaml.
I've been going back over Governing the Commons, but have already discovered The Real World of Technology!
More thoughts on all of this soon... maybe
Teaching, teaching, teaching... [weekly-2025-02-10]
- February 10, 2025
On paper, I don't have that many students. I teach four undergraduates (first year students at Pembroke College) Discrete Maths. I supervise three third year students for their final year project and another one I co-supervise with Michael Dales. However, I do end up spending at least two full days a week on teaching. Something I really enjoy and take seriously. The time it takes is also quite unpredictable; last week for instance all the third year students had their mid-project demonstrations (a five-minute presentation in front of their peers and a few professor-types). My first year students also found two slides particularly challenging to understand from their lectures and asked if I could help explain what was going on, so I produced some materials for that.
OCaml
Within the OCaml universe I spent a good bit of time trying to maintain a couple of different packages:
Mirage Crypto: this library provides cryptographic primitives for OCaml programs. Unfortunately, the maintainers removed direct support for Eio replacing it with a "Unix" alternative. This is not a fair swap as now Eio programs must make a dependency to Unix! Speaking to Anil, the best approach might be to make Eio programs handle this directly. I think this highlighted how fragmented open-source maintenance can be as no user of Eio seems to have bumped into this yet and the upstream maintainers did not communicate a rather large breaking change.
Ppxlib: In addition to the 5.2 AST bump (which is nearly ready to be merged), I queued up a 5.3 AST bump right behind it. I plan to write up a more detailed post about the challenges of maintaining this part of ppxlib.
Paris
I spent some time in Paris at the end of the week. I enjoyed visiting the Musée d'Orsay and in particular their collection of impressionist paintings. Here's my favourite from that visit by Camille Pissarro.

AT Protocol and an IR for Wikis [weekly-2025-01-27]
- January 27, 2025
AT Protocol
This week I've been diving into the AT Protocol.
The Authenticated Transfer Protocol, aka atproto, is a decentralized protocol for large-scale social web applications.
The protocol could be a candidate for the glue that holds together a distributed, computational wiki network. The protocol, it seems, is very similar to IPFS. Thankfully, a few years ago, I was working on building out a suite of OCaml libraries for working with IPFS. For example, ocaml-cid, self-describing content-addressed identifiers.
# let s = "zb2rhe5P4gXftAwvA4eXQ5HJwsER2owDyS9sKaQRRVQPn93bA";;
val s : string = "zb2rhe5P4gXftAwvA4eXQ5HJwsER2owDyS9sKaQRRVQPn93bA"
# let cid = Cid.of_string s |> Result.get_ok;;
val cid : Cid.t = <abstr>
# Cid.pp_human Format.std_formatter cid;;
cidv1 - base58btc - raw - ident(sha2-256) length(32) digest(6e 6f f7 95 0a 36 18 7a  80 16 13 42 6e 85 8d ce
                                                            68 6c d7 d7 e3 c0 fc 42  ee 03 30 07 2d 24 5c 95
To this end I have built out some more OCaml libraries for working with atproto, including:
atproto-data: the atproto data model, similar to JSON-LD.
ocaml-did: an OCaml library for working with decentralized identifiers.
atproto-lexicon: atproto's schema format, I've been building a quick tool for doing an OCaml translation from these schemas.
I managed to get a post published from the OCaml library after fixing it up and porting it to Eio.
An IR for Wikis
I started working on a proof-of-concept intermediate representation for Wikis -- I imagine it a bit like malfunction but for computational wikis i.e. a target for Wiki building tools that allows different front-ends and servers to communicate in a common IR for exposing key functionalities of a wiki:
Links: External links, cross-wiki backlinks
Versioned, temporal feeds
Etc.
Other PhD Work
I met with most of my Part II students this week, and I'm excited about their work. Progress reports are due this week and next they have a presentation to give.
In discrete maths this week we did induction. Next up is a big section on sets, functions, bijections etc.
Misc.
I was happy to find the Information Controls Fellowship Program.
The Information Controls Fellowship Program (ICFP) cultivates research, outputs, and creative collaboration on topics related to repressive internet censorship and surveillance.
Forester, ICFP, Wikis [weekly-2025-01-20]
- January 20, 2025
This week was my first full week back from the break and I found it challenging trying to get back into what I had been working on previously.
ICFP Papers
In conversation with Anil, we looked at options for submitting a paper to ICFP. I wrote up some notes on some options we discussed.
Forester
I spent some time this week converting this website to using Forester. I'm not a huge fan of the syntax, especially as a lot of my site's content was already in markdown. So I wrote a markdown frontend to forester which is available on Github.
The markdown frontend integrates very nicely and only a few changes were needed in the core logic of Forester itself. Additionally, for any features not directly supported in markdown there is an escape hatch using code blocks such as:
```forester
\put\transclude/numbered{false}

\transclude{pxf-1000}
```
Personally, I'm still getting to grips with the bottom-up approach to building this site, atomically creating notes and reference cards that then are linked in many places.
I'm excited to see how I can integrate some of the Forester concepts into "Shark".
OCaml
In the OCaml world, I spent time on ppxlib, reviewing PRs to update the lower bounds of the library, fixing effect syntax problems and bumping internal AST to 5.2. I've also spent some time looking into de-objecting Eio, making the OCaml types more friendly to new users. I need to revive my port of Vpnkit to Eio for the thoughts on ICFP 2025 too.
I also want to modernise and make more public my OCaml code for creating little shells in OCaml too -- I think the ideas here really have legs and would like to find a conference to submit them too.
I also met with the single, OCaml Outreachy intern working on ocaml-api-watch.
Misc.
I met with most of my Part II students this week which was nice to catch up and see how their projects are going. I also started marking work for my first year students who are at the induction part of their Discrete Maths course.
Software [software]
- Patrick Ferris
This page enumerates all the software I maintain and release. The sources for most of my software can be found at git.sirref.org and mirrored on tangled.
Where possible my software is released under the ISC. No AI was directly used in the making of my software.
Software. Bib [bib]
- Patrick Ferris
- https://git.sirref.org/ocaml-bibtex
Bib is a simple bibtex codec for OCaml.
Documentation
- Patrick Ferris
Releases
- Patrick Ferris
All versions of Bib are available:
Bib: Initial release (0.1.0) [bib-release-0-1-0]
- August 21, 2026
- Patrick Ferris
- https://patrick.sirref.org/software/bib/releases/bib-0.1.0.tbz
Initial release of Bib, a bytesrw-codec for reading and writing bibtex files.
Please consult the documentation for how to use the library.
Posts [posts]
Occasionally I write posts, mostly about OCaml or something related.
Merging pure shell histories [merging-pure-shell-histories]
- September 3, 2026
- Patrick Ferris
We define a pure shell history as an execution trace from a shell that only changes the shell's execution environment, that is, there are no external side-effects. In this article, we will reason about merging independent pure shell histories.
We can make a simplifying assumption that our shell executes commands on a readonly filesystem without any network connectivity. So for example, we could have the following script:
export DOWNLOAD_DIR=/home/bactrian/downloads
export PATH=/bin

exit () {
  echo "Goodbye!"
}

trap exit EXIT

analyse $DOWNLOAD_DIR
The shell execution environment is state managed by the shell. It may be materialised concretely in the shell's runtime (e.g. a map of function names to function definitions) or managed by the kernel in the process state of the shell (e.g. open file descriptors).
Each pure shell command has a dynamic dependency cone. For simplicity, we will restrict this dependency cone to just the shell execution environment excluding resources like files or the network. When a command is run, we can evaluate that dependency cone using a custom eBPF program in addition to information provided by the shell (see Merry).
Only shell built-ins can modify the shell execution environment; therefore these operations are known by their constructor. For example, export FOO modifies the variable FOO to be marked as exported — in general it is not known statically what precise modifications are made due to, for example, word expansion or the dynamic lookup of functions. An executable cannot perform such a modification on the shell execution environment.
We can think of pure shell scripts in terms of a mergeable replicated data type.
Definition. Mergeable Replicated Data Type Implementation [mrdts]
- Patrick Ferris
A mergeable replicated data type (MRDT) implementation for a data type \tau is a tuple D_{\tau } = (\Sigma , \sigma _{0}, do, merge) where:
\Sigma is the set of all possible states at a branch,
\sigma _{0} \in \Sigma is the initial state,
do : Op_{\tau } \times \Sigma \times Timestamp \rightarrow \Sigma \times Val_{\tau } implements every data type operation,
merge : \Sigma \times \Sigma \times \Sigma \rightarrow \Sigma implements the three-way merge strategy.
Definition 2.1 from "Certified Mergeable Replicated Data Types".
Treating \tau as the shell execution environment and Op_{\tau } as pure shell commands we can reason about our shell using MRDTs.
There are some nice properties that fall out of algebraic properties of the operations that are allowed on your data type. For instance, commutative operations.
Notes
- September 3, 2026
- Patrick Ferris
Orthogonal MRDT operations — where it is possible to compute a single operation that lead to a particular state.
A Shell is Born [a-shell-is-born]
- June 17, 2026
- Patrick Ferris
Merry passed a milestone this week after installing the following packages vim fakeroot fakechroot debootstrap and successfully performing a fakechroot debootstrap.
To me, this signals that Merry is closer than ever to being an actual POSIX-ish shell. This is exciting because we now have a completely customisable, OCaml implementation of a shell that can run a significant number of existing shell scripts in the world. Let the hacking commence!
Installation
- June 17, 2026
- Patrick Ferris
You can install the binary, msh, today:
opam pin git+https://git.sirref.org/merry
eval $(opam env)
msh
What's next?
- June 17, 2026
- Patrick Ferris
There are a few avenues to try next. In the short-term, more testing of the shell is probably worthwhile. In particular, trying to boot an Alpine Linux image with msh as the default shell would be good.
Integrating the various components of Shelter is also on the list. A time-travelling POSIX shell is within reach; the actual semantics still need to be ironed out.
I know for certain that some shell options and built-ins will be the first issues to arise going forward.
As a fun experiment, Anil's vibecoded OCaml busybox translation could be plumbed into msh. This would allow a very versatile, but zero-forking shell! Throw in an in-memory Eio filesystem into the mix and the whole thing becomes in-memory... mirageSH.
Weeknotes
- June 17, 2026
- Patrick Ferris
Below are a collection of weeknotes for Merry.
Shell Benchmarks, Back to Writing [weekly-2026-w26]
- July 4, 2026
- Patrick Ferris
A little late due to travel, but I did a little benchmarking of Merry.
Signal Handling in Merry
- July 4, 2026
- Patrick Ferris
In order to even run shellbench, I first had to fix some bugs in the shell implementation. Shellbench aims to warm up the shell before starting any benchmarks; it includes this prelude before getting started:
__ready=
trap __ready=1 HUP
kill -HUP "$MAIN_PID"
until ["$__ready" ]; do __dummy=; done
Whilst writing Merry, I hadn't really considered that the return context from a trap needed to be taken into consideration! I had assumed they would be silently ignored, how else would we know where to thread that context back into the shell's execution.
Even after reading through the specification for trap I am still none the wiser. I've opted to place some sensible signal polling points during the execution of the commands to run any signals that have come in. The single handlers in Merry simply push thunks onto a run queue. Looking at the Dash source code, it seems to be something that happens just before evaluation.
Benchmarking Merry [merry-benchmarks]
- July 4, 2026
- Patrick Ferris
Medium-to-small potatoes
- July 4, 2026
- Patrick Ferris
I used shellbench to understand where some of the performance pitfalls were coming from.
$ ./shellbench -s bash,zsh,msh sample/func.sh
-----------------------------------------------------------------------------------
name                                                     bash        zsh        msh
-----------------------------------------------------------------------------------
func.sh: no func                                      775,539  1,124,485      5,229
func.sh: func                                         398,861    197,169     93,424
-----------------------------------------------------------------------------------
* count: number of executions per second
This particular benchmark first runs nothing (i.e. :) and then a function lookup and execution. Surprisingly msh is slower at doing nothing! I perf-ed a run of msh test.sh with just a single : in the file:
Test built-in
- July 4, 2026
- Patrick Ferris
After making various improvements to Merry that almost halved the memory usage (e.g., removing extraneous string manipulations, adding a fast-path to the PATH variable for resolving programs). I was still pretty far off the performance of these other shells. I decided to have a look at dash which has a simple implementation.
This flame graph is for the following shell script:
f () { :; }
while __count=$(($__count+1)) && ["$__count" -le 10000 ]; do
	f
done
echo "count is $__count"
And here are some rudimentary benchmarks:
$ time -p dash test.sh
count is 10001
real 0.01
user 0.01
sys 0.00
$ time -p msh test.sh
count is 10001
real 15.53
user 4.28
sys 12.28
It turns out the massive slowdown is very simple to explain. In the dash flamegraph there is a oexpr stack; which comes from the bltin/test.c file. dash, along with the other shells, does not spawn a process for the [-test command! Forcing dash to do use the binary [ gives:
$ time -p dash test.sh
count is 10001
real 7.55
user 3.95
sys 3.44
Which is much more respectable in terms of performance compared to msh. Plenty of work to do though!
Parsing arithmetic expressions
- July 4, 2026
- Patrick Ferris
There was some obvious low-hanging fruit to help improve some of the performance differences. The first was pre-parsing arithmetic expressions. Morbig, the static parser, does not implement arithmetic expression parsing; so Merry does it for us. Before, it was on-demand, as we encountered an expression of the form $((<e>)). Now, it happens up front. This should improve tight-loops.
Writing
- July 4, 2026
- Patrick Ferris
More on this soon, but I have started writing two separate papers bringing all of this work together.
Three weeks in the Shell [weekly-2026-w25]
- June 16, 2026
- Patrick Ferris
The last three weeks have been focused work on building Merry. In practice, I wanted to run the following two commands through Merry's shell: msh:
apt-get install debootstrap -y
debootstrap stable /stable-chroot http://deb.debian.org/debian/
Seemingly innocuous. But both commands run thousands of lines of shell script. Whether that's Debian package maintainer scripts or state-machines for processing package release files.
What follows is a handful of the bugs and the shell scripts that caused them.
Field Splitting
- June 16, 2026
- Patrick Ferris
Edge-cases abound in the POSIX shell specification; and field splitting is one of the most serious perpetrators. Field splitting happens after word expansion. It is a known footgun amongst shell script authors.
$ count () { echo "Count: $#"; }; FOO="hello world"; count $FOO
Count: 2
Quoting variables that need expanding will prevent field splitting from taking place, but it is an easy thing to forget.
Field splitting uses the IFS (internal field separator) environment variable to determine how to do the splitting, and it comes with some extra rules beyond "split on these characters".
$ IFS=" "; FOO=" hello    world"; echo $FOO
hello world
$ IFS=" "; FOO=" hello    world"; echo "$FOO"
 hello    world
$ IFS=":"; FOO="a:b:c:"; echo $FOO
a b c
$ IFS=":"; FOO="a:b::c:d"; echo $FOO
a b  c d
$ IFS=":"; FOO=":a:b:c"; echo $FOO
 a b c
$ IFS=; FOO="unset   IFS"; echo $FOO
unset   IFS
Variable assignment
- June 16, 2026
- Patrick Ferris
How a shell stores variables also impacts field splitting. Naively, Merry stored variables as strings, but really they should be stored as their expanded form.
Consider this example of saving a function output in a variable called base.
iter () {
 echo "a"
 echo "b"
 echo "c"
}

base=$(iter)

for n in $base; do
  echo "Got $n"
done

for n in "$base"; do
  echo "Got $n"
done
Later, when we come to iterate across the fields of $base we wouldn't be able to reconstruct the intial fields that $(iter) produced if we simply saved the result as a string. Too much information would have been lost.
Redirections
- June 16, 2026
- Patrick Ferris
Redirections control what file descriptors point to. Each redirection has a lifetime associated with it. For example: cat < README.md really says "open README.md and execute the cat program mapping the process's FD 0 to the FD of README.md". When cat returns that redirection is no longer valid.
Other redirections are not so simple. Consider:
$ echo "!dlrow olleh" > input.txt
$ (read line; echo $line) < input.txt | rev
hello world!
There are lots of redirections here too. Firstly the standard input for everything inside the braced command (read line2; echo $line) should be the open file descriptor for input.txt. The standard output of the braced command should be the writing end of a pipe whose reading end is passed to rev as that process's standard input. The final standard output for rev should be unchanged from what it was originally (the shell's standard output).
Getting redirections right is hard, consider this snippet from the debootstrap scripts (all in the context of stdout and stderr pointing to a debootstrap.log file and file descriptor 4 pointing at the true stdout).
for m in $MIRRORS; do
    pkgdest="$TARGET/$($DLDEST pkg "$s" "$c" "$a" "$m" "$path")"
    if [! -e "$pkgdest" ]; then continue; fi
    pkgs_to_get="$(download_debs "$m" "$pkgdest" $pkgs_to_get 5>&1 1>&6)"
    if [ -z"$pkgs_to_get" ]; then break; fi
done 6>&1
More niche built-ins
- June 16, 2026
- Patrick Ferris
As the dust begins to settle on the nuts and bolts of implementing a POSIX-ish shell, new challenges are allowed to emerge from deep within scripts.
One such challenge is the seemingly endless (I know, they're finite) shell built-ins! Whilst trying to run debootstrap using its fakechroot variant, I bumped into getopts... a whole command-line parsing shell built-in.
An In-memory Filesystem for Eio [eio_mem]
- June 16, 2026
- Patrick Ferris
Towards the end of last week and the beginning of this week, I threw together a prototype for an in-memory filesystem for Eio: Eio_mem. Concretely, this provides a means for constructing an Eio.Fs.dir_ty Eio.Path.t value that is completely in-memory.
Thanks to Eio's capability-first approach, any existing code implemented against the _ Eio.Path.t API should just work with the in-memory filesystem.
There's a convenient Eio_mem.Fs.load function that can take a path from one filesystem (most likely a normal one from Eio_linux or Eio_posix) and replicate it into the in-memory filesystem. For example, you might have a static web-server pointing to a directory like "/var/www". The following might be the only change you need to make it completely in-memory (example from ocaml-cohttp):
 let () =   let port = ref 8080 in
   Arg.parse
     [ ("-p", Arg.Set_int port, " Listening port number(8080 by default)") ]     ignore "An HTTP/1.1 server";
   Eio_main.run @@ fun env ->
+  Eio_mem.run @@ fun menv ->
   Eio.Switch.run @@ fun sw ->
-  (* Restrict to current directory: *)
-  let htdocs = Eio.Stdenv.cwd env in
+  (* Restrict to in-memory current directory: *)
+  Eio_mem.Fs.load ~filter (Eio.Stdenv.cwd env);
+  let htdocs = Eio.Stdenv.cwd menv in
   let socket =
     Eio.Net.listen env#net ~sw ~backlog:128 ~reuse_addr:true
       (`Tcp (Eio.Net.Ipaddr.V4.loopback, !port))
The keen-eyed reader might have noticed the filter parameter. This can be used to ignore certain paths (here I ignored .git and _build which were adding substantial time to loading the filesystem).
Using meio to debug Merry [weekly-2026-w23]
- June 4, 2026
- Patrick Ferris
During a large rewrite of Merry, I introduced a regression causing certain shell programs to hang indefinitely. I thought it might be a good opportunity to try out Meio.
First, let's look at a trace of Meio from some real-world programs. For example: meio -- msh -c "sleep 100".
One problem that comes up immediately from this example is that the tree hierarchy of tasks and cancellation contexts makes it tricky to reason about the logging. Here, we can see the pipeline's cancellation context clearly labelled pipeline-id1. This is an Eio.Switch.t for the pipeline sleep 100. The actual execution log for sleep 100 bubbles back up to the main fiber (that has no name, so it is called <task>). The daemon fiber, for ensuring the spawned process is reaped, is attached to the switch and is displayed below it.
Meio has a long way to go. Most programs are too fast to be monitored in this way. Using something like tokio-console's model might be a better idea here focusing less on the tree strucuture of the program, and more on the performance and monitoring of individual tasks. Without this, it turns out Meio was not all that useful for debugging this specific issue (which ended up being some bad pipe management on my part).
Shell forks revisited [weekly-2026-w17]
- April 28, 2026
- Patrick Ferris
Whilst I did get up to some other work last week, I decided to dedicate this weekly to fork-ing in the shell.
Must we fork?
- April 28, 2026
- Patrick Ferris
I have spent some time trying to figure out: can you implement a shell that never has to fork and run its own code (as opposed to fork+exec-ing, which is necessary)? There are, at least, two bits of POSIX shell semantics that make this hard: concurrency and redirects, particularly in the presence of shell built-ins.
Individual commands in a pipeline, according to the POSIX specification, will have their standard input and output connected up before other redirections.
The standard input, standard output, or both of a command shall be considered to be assigned by the pipeline before any redirection specified by redirection operators that are part of the command.
Additionally:
...each command of a multi-command pipeline is in a subshell environment; as an extension, however, any or all commands in a pipeline may be executed in the current environment.
Where a subshell is defined as:
Subshell: A shell execution environment, distinguished from the main or current shell execution environment.
We will note that subshell \neq child process. In practice, however, the two are used fairly interchangeably given the semantics of spawning a child process. Perhaps the two most crucial aspects of a given command in a subshell are that:
It is run in parallel with the other commands.
It should be reentrant.
In what follows we will assume that we are discussing a multi-command pipeline p.
\texttt {p} = \texttt {cmd}_1 | ... | \texttt {cmd}_n \text { where } n \geq 2
Pipeline parallelism
- April 28, 2026
- Patrick Ferris
The POSIX specification does not mandate parallelism explicitly for commands in a pipeline. However, in practice the semantics of a pipeline necessitate concurrency at the very least.
Suppose we have \texttt {cmd}_1 | \texttt {cmd}_2 where \texttt {cmd}_1 produces an infinite amount of output (e.g., cat /dev/urandom) and \texttt {cmd}_2 consumes a finite amount of input (e.g., hxd-xxd -l100). What is the result of running this pipeline with the default POSIX shell options?
$ dash -c "cat /dev/urandom | hxd.xxd -l100"
00000000: 5033 7981 ae44 d475 074c 5361 0a9e 3828  P3y..D.u.LSa..8(
00000010: f88c 1f9e 3b0e bcde 528a f78c b1e4 7195  ....;...R.....q.
00000020: 16f2 8325 c90b 9310 539c af04 8289 c3a0  ...%....S.......
00000030: 57c5 680a 2c81 a999 71b6 708e 95df e720  W.h.,...q.p....
00000040: 004c 407a 8365 9448 65c6 b435 bed2 4084  .L@z.e.He..5..@.
00000050: 62ea 96ab 2b23 0385 f9d2 fc30 d090 1719  b...+#.....0....
00000060: 68d1 c514                                h...
cat: write error: Broken pipe
There are three factors that influence the pipeline's execution behaviour (i.e. what is done about the commands that are run and the exit status we return).
pipefail: Withpipefailset tofalse(the default), the exit status of the pipeline is entirely decided upon by the exit status of the rightmost command (above \texttt {cmd}_2). Withpipefail, the pipe will exit with 0 if all commands exit with 0; otherwise the non-zero exit status of the rightmost command is taken.!: If the pipeline begins with!then this inverts the exit code in the way you might expect.All commands must terminate.
Whilst in theory \texttt {cmd}_1 does not terminate, the termination of \texttt {cmd}_2 closes the reading end of the pipe resulting in the Broken pipe system error.
Let's replace \texttt {cmd}_1 with the following compound command that also produces, left to its own devices, infinite output on stdout.
while echo "some bytes"; do
  :
done | hxd.xxd -l100
In this example, we no longer have the luxury of being able to fork and exec. The compound command (the while loop) forces our hand -- we must rely on the internal execution logic of the shell to keep it going. How then do we prevent \texttt {cmd}_1 from blocking our shell from spawning \texttt {cmd}_2?
For most shells, this is where they might fork themselves and allow the while loop to execute in the child. The parent continuing on. Alternatively, the work could continue on in a separate thread (in OCaml parlance, domain). Fibers (green threads, coroutines etc.) are only possible if there are a sufficient number of co-operative yields (which can be hard to track: any control flow or shell built-in would need to ensure they periodically yield to the other commands in the pipeline).
With that being said, it would seem we have workarounds to ensure the parallel aspects of pipelines are possible to build without forking the shell state itself.
Command Reentrancy
- April 28, 2026
- Patrick Ferris
Command reentrancy deals with the fact that commands in a pipeline run in subshells. In practice, this means any \texttt {cmd}_i should not impact the execution environment of any other \texttt {cmd}_j. Commands may certainly interfere with one another: a rogue rm might remove a file that some other command was about to read or was in the middle of reading!
\S 2.13 of the POSIX shell specification describes the execution environment. In Merry we lift this into the ctx type making it completely immutable; the only way to update the context is to destructively declare new fields, e.g., { ctx with cwd = "/home/bactrian" }. All shell built-ins work directly from the context as opposed to any state that might also be kept by the process itself (e.g., we do not call getcwd(3) to expand PWD, but instead read it from the context).
Most state is handled nicely by this functional implementation of the shell; except open (or not) file descriptors. The exec built-in is particularly thorny in this regard:
If exec is specified with no operands, any redirections associated with the exec command shall be made in the current shell execution environment.
So, exec 3>&1 says "in the current execution environment map file descriptor 3 to stdout" and exec > /dev/null says "in the current execution environment map stdout to /dev/null. This is often used to silence anything writing to stdout.
info () {
  echo "INFO: $1" >&3
}

exec 3>&1 > /dev/null
info "Starting up server..."
echo "Some noisy program spamming STDOUT"
info "All is quiet..."
If we are not running shell built-ins inside new child processes, then we must lift the file descriptor table into the context as well and disallow any two built-ins to run in parallel. Consider this example:
exec < ./hello.txt

while read line; do
  echo "Got $line" >&2
done | (exec < ./world.txt; cat)
If we allow exec to change the set of open file descriptors of the shell process directly, then individual commands in the pipeline are no longer re-entrant. The pipeline here is not being used to pipe bytes from one command to another, but instead to expose concurrency and the subshell behaviour.
The second exec < ./world.txt has no impact on the currently opened file on stdin, the while loop continues to read ./hello.txt. This is straightforward to implement with fork as you can dup2 any files you need. The bookkeeping and isolation is all provided by the POSIX process semantics. Without fork, the file descriptors would have to be saved and restored on every suspension and resumption to provide an illusion of isolation.
We could relax our rule to "disallow any two built-ins to run in parallel" by taking a lock on the file descriptor table, but considering the lock is held from the point of resumption until the next suspension it might not achieve very much in practice.
Some of the intricacies of scheduling are also covered in Michael Greenberg's An executable and formal semantics of the POSIX shell.
To motivate the question, consider the following two pipelines:
(1)
while true; do echo 5; done | true(2)
while true; do echo 5; done | { read x; echo $((x+42)); }Both pipelines spawn two processes, both of which use shell builtins exclusively: neither of these pipelines needs to make an
execvesystem call (though some systems may implement true or echo as executables, Smoosh and most shells build them in).
Scheduling is an opaque part of the POSIX specification. Indeed, as we have argued here, there is no semantics for scheduling. Here is a similar pipeline run through a script that straces for clone and fork calls on various shells:
% ./test/check_fork.sh "while echo 5; do : ; done | true"
bash  3
dash  3
yash  1
zsh   1
ksh   1
ash   3
It might make an interesting use case for effects in OCaml -- whilst we can certainly piggyback on Eio's existing suspension mechanisms, this is slightly different in that we need to ensure some preconditions are true before resuming certain computations. Fiber-local state is insufficient as programs implicitly depend on global state of the process (in particular the FD table). In this sense, we need some form of suspension-resumption hooks.
Forking in Shells & Library Maintenance [weekly-2026-w14]
- April 3, 2026
- Patrick Ferris
This week, Merry got close to executing apt-get install ca-certificates and running Debian's debootstrap scripts correctly. Nathan and I released Ppxlib 0.38.0, I added support to ocaml-proj for compiling to the browser and I fixed a long-standing bug in hilite.
Forking in Merry
- April 3, 2026
- Patrick Ferris
So far, Merry has managed to support many features of the POSIX shell specification without needing to do a fork(2) without an exec. Or, to put it another way, all the forking that Merry does, will only be followed by running C code. This is actually a feature of Eio's Process API. It is required to make process execution safe in the context of multiple domains in OCaml (mostly due to ensuring consistency within the garbage collector). However, it is perfectly okay to fork and run OCaml code provided there is only a single domain.
In a shell, many features of the shell language require that commands (or built-ins, function applications etc.) execute within a subshell. The specification does not go into detail about how shells should implement this, but many choose to fork in order to preserve some state in the parent (for example, the file descriptor table). Some shells try to minimise the number of forks as an optimisation. The korn shell (ksh) is one such shell.
Using the notation
$(command)will causecommandto execute in a subshell of the current ksh. In many instances, ksh will not actually fork/exec a subshell when command is a built-in or a shell function.
By trying to adhere to Multicore OCaml's "thou shalt not fork" commandment, Merry is much more similar to ksh in this regard. However, whenever there is an interaction with a shell built-in and semantics that need a child process, things get tricky very quickly. Consider the following:
while echo "hello"; do
  :
done | head -n 3
We have a mix of shell built-ins, normal commands, a compound command (the while loop) and a pipeline. Each individual command in the pipeline requires you to run them in a subshell and set them up before executing them. Without a fork for that first command, you may end up looping forever which is not the intended behaviour here. I had a good conversation with Michael about the implications of this for reproducibility.
For now, I have started implementing a fork for some of the shell features whilst still trying to maintain the functional core of the implementation.
An OCaml 5.5 compatible Ppxlib
- April 3, 2026
- Patrick Ferris
Nathan and I released an OCaml 5.5 compatible version of ppxlib.
Ppxlib Releases › 0.38.0 [ppxlib-release-0-38-0]
- March 30, 2026
- Patrick Ferris
Nathan and I released ppxlib.0.38.0 last week. Its main feature is full migration support for the upcoming OCaml 5.5 compiler (currently in its alpha3 release). This means supporting the handful of new features landing in OCaml 5.5: modular explicits, external type declarations and arbitrary "local" structure items.
As Nathan and I continue to find a plausible maintenance story for ppxlib, Nathan has opened an issue on the OCaml compiler to discuss the idea of adding additional extension points to the language.
This comes from the desire to be able to store encoded versions of new OCaml features inside older abstract syntax trees.
There are also some nice bug fixes in there too:
A potential OOM loop has now been removed.
Browser support for ocaml-proj [ocaml-proj-virt]
- April 3, 2026
- Patrick Ferris
A while ago I built some "modern" bindings to PROJ4 in OCaml. After reading Jon Ludlam's weeknotes (and speaking with him and Anil, I thought it might be nice to add a Javascript backend to those bindings). This was relatively straight-forward using Dune's virtual libraries and is available on Github.
With virtual libraries, your own data analysis could (if you wished) depend solely on the proj library and later choose to either link it with proj.c or proj.js depending on where the analysis is being deployed.
I briefly looked at WASM support, but quickly realised there was not much appetite for it and trying to compile around the C FFI was going to be hard.
Hilite updates
- April 3, 2026
- Patrick Ferris
Since I helped relaunch the ocaml.org website a few years ago, I have maintained hilite, a tool for doing build-time syntax highligting.
It is being used on the ocaml.org website, in yocaml_markdown and also in Michael's webplats (when it works...).
And it was Michael who led me to finally fixing and adding syntax highlighting support for Python and Go. Once I was on this roll, I finally took a look at fixing the long-standing bug of trying to highlight ocaml-mdx code, like the following:
# 50.123;;
# 1 "file.ml";;
In fact, this code now highlights fine, but was the source of the bug. The syntax highlighting grammer confuses the ocaml-mdx # as a toplevel directive and trouble ensues.
Ppxlib release and Merry updates [weekly-2026-w13]
- March 30, 2026
- Patrick Ferris
Ppxlib Releases › 0.38.0 [ppxlib-release-0-38-0]
- March 30, 2026
- Patrick Ferris
Nathan and I released ppxlib.0.38.0 last week. Its main feature is full migration support for the upcoming OCaml 5.5 compiler (currently in its alpha3 release). This means supporting the handful of new features landing in OCaml 5.5: modular explicits, external type declarations and arbitrary "local" structure items.
As Nathan and I continue to find a plausible maintenance story for ppxlib, Nathan has opened an issue on the OCaml compiler to discuss the idea of adding additional extension points to the language.
This comes from the desire to be able to store encoded versions of new OCaml features inside older abstract syntax trees.
There are also some nice bug fixes in there too:
A potential OOM loop has now been removed.
Merry updates
- March 30, 2026
- Patrick Ferris
It turns out writing a POSIX(ish) shell is hard; at least, there is a vast number of slightly obscure features that one needs to support. I think this is surprising because most people writing shell scripts write simple shell scripts; scripts that use a much smaller subset of features. In the same breath, those same developers are likely to use something like apt-get install bash which runs a plethora of more advanced (and non-POSIX) shell scripts!
Exec redirects
- March 30, 2026
- Patrick Ferris
In a shell script, you can use the built-in command exec to replace the current process with a new one (e.g. exec vim). However, there is a different mode of operation for exec:
If exec is specified with no operands, any redirections associated with the exec command shall be made in the current shell execution environment.
One of my litmus tests for Merry is the Debian debootstrap scripts (h/t Anil). One thing that it does is the following:
err () {
  printf "err $1" >&4
}

exec 4>&1
A lot of detail has been elided for clarity. exec 4>&1 sets up a redirection for the shell's execution environment in which file descriptor 4 is now an alias for standard output. So, writing to 4 (by redirecting a command's standard output to 4 i.e. >&4) will output to where standard output is going (most likely the terminal).
For this to work, shell's must dup2 the relevant file descriptors which have the following condition:
If the file descriptor newfd was previously open, it is closed before being reused; the close is performed silently (i.e., any errors during the close are not reported by dup2()).
This is all very well, unless your program has an important file already open that happens to have file descriptor 4. The Eio Linux and POSIX backends suffer from this problem. Both make use of a file-based synchronisation mechanism for waking up the eventloop should another domain push a completion to the scheduler's run queue. On Linux this is via an eventfd and in POSIX, a pipe.
This dup2 will close the eventfd and will likely grind Eio to a halt (or an assert false). For now, I have resorted to vendoring Eio and moving the eventfd file descriptors to higher values, though I have opened a PR to make this more configurable. This bug is quite easy to write up... it was not so easy to find!
As a random example, consider the debconf/confmodule script which offers very little room for a buggy implementation!
Outreachy
- March 30, 2026
- Patrick Ferris
The presentations from the demonstrations for this round of Outreachy are now online!
Write support in OCaml TIFF library [outreachy-ocaml-tiff]
- February 9, 2026
- Patrick Ferris
I am mentoring Tambe Salome during the December 2025 Outreachy round to add support for writing TIFF files in the ocaml-tiff library.
You can now see the video of the demonstration day presentation:
A POSIX Shell in OCaml [weekly-2026-w12]
- March 19, 2026
- Patrick Ferris
Long time, no weekly. Since the start of this year I have been building a POSIX shell in OCaml called msh (with the underlying library called Merry). Merry is available online now.
A POSIX(ish) shell in OCaml
- March 19, 2026
- Patrick Ferris
Merry is a POSIX(ish) in OCaml. It uses Eio alongside Morbig (a static parser for POSIX shell).
Why another (POSIX) shell?
- March 19, 2026
- Patrick Ferris
Shells have been around for a long time. In my research on the notion of metashell I wrote about Louis Pouzin originally coining the term:
Metashells › Louis Pouzin's "SHELL" [pouzin-shell]
- May 19, 2025
- Patrick Ferris
I spent some time reading part of the multics design documentation this week. Louis Pouzin coined the term "SHELL" in this document, and I was reminded yet again just how important it is to be a good writer even as a "computer science researcher". For example, this excerpt from the requirements section of the document
The previous definitions imply that a command MUST be designed while keeping in mind the user, sitting at his console, wondering about what might be going on, mistyping or forgetting arguments, even if fully aware of the conventions, and possibly interfering with the command by hasty quits, carriage returns, and other temperamental reactions.
And then later, when defining the "SHELL".
We may envision a common procedure called automatically by the supervisor whenever a user types in some message at his console, at a time when he has no other process in active execution under console control (presently called command level). This procedure acts as an interface between console messages and subroutine. The purpose of such a procedure is to create a medium of exchange into which one could activate any procedure, if it were called inside of another program. Hereafter, for simplification, we shall refer to that procedure as the "SHELL".
It still surprises how little the undergraduate degree in computer science at Cambridge focuses on writing skills.
I built Shelter exploring the idea of a shell-like interface that allowed users to undo their shell actions (amongst other cool tricks). Unfortunately shell-like is not enough. Shelter cut many corners to masquerade as a shell (e.g. appending env to understand how a command may have altered the execution environment). I felt it was necessary to make Shelter a "SHELL"! To do that, I needed a solid foundation to build on.
msh, the POSIX shell that comes with Merry, is by no means POSIX-complete in terms of features. But it is my daily driver at this point. It includes a pure OCaml rewrite of linenoise (a small, self-contained alternative to the venerable readline) called bruit.
If you have docker installed on your machine, you can take it for a spin today:
docker run -it --rm patrickferris/msh
The patrickferris/msh docker image is just for trying it out. It is based on the OCaml 5.3 alpine image.
Alternatively, you can build msh from source and have it available in your opam switch.
opam pin git+https://tangled.org/patrick.sirref.org/merry
There are many small paper cuts left to patch over, but most of it is porcelain (e.g. ctrl+left-arrow for moving in bruit). Unfortunately, these are the kinds of things that you will immediately stumble upon.
What makes Merry different?
- March 19, 2026
- Patrick Ferris
Nothing.
Merry is supposed to be a solid, POSIX-ish base to build on. Unfortunaltely, as it turns out, the subset of features from the POSIX specification that people actually use... is pretty much all of it. Every possible redirection, variable expansion, shell built-in and compound command make some appearance. Not to mention the non-POSIX bits of shell we all take for granted (e.g. &>-redirection).
Merry and msh are useable. You will most likely find bugs if you use them. If, when using msh, you find something obscure happening you can enable debug mode either my setting the variable MSH_DEBUG or by invoking msh with -v -v.
What's next?
- March 19, 2026
- Patrick Ferris
It is soon time to combine Shelter and Merry into the time-travelling, POSIX-ish shell that I have been trying to build since I first started working on Shelter.
For this to be successful, I need Merry to be able to pass plenty of tests and right now that involves trying to install plenty of packages using tools like apk and apt.
Shell MRDT
- March 19, 2026
- Patrick Ferris
What I am particularly interested in reasoning about, is the execution context in Merry. This value, alongside the file-system, constitutes a fairly deep understanding of the state that changes in each step of a shell's evaluation loop.
This was, in terms of Shelter, the missing piece for truly building some kind of MRDT across shell sessions.
TIFF in OCaml
- March 19, 2026
- Patrick Ferris
I picked up from the excellent Outreachy work of Tambe Salome in getting write-support in ocaml-tiff. We are getting closer to the kind of API I envisaged in this latest round of refinement and review.
let ( / ) = Eio.Path.( / )

let checkerboard ~size =
  let v = Nx.zeros Nx.uint8 [| size; size |] in
  for row = 0 to size - 1 do
    for col = 0 to size - 1 do
      if (row + col) mod 2 = 0 then Nx.set_item [ row; col ] 254 v
    done
  done;
  Nx.to_bigarray v

let () =
  Eio_posix.run @@ fun env ->
  Tiff_eio.with_open_out (env#cwd / "example.tiff") @@ fun w ->
  let tif = Tiff.make (checkerboard ~size:256) in
  Tiff.to_file tif w
I have also been extremely pleased to see further external collaborators appearing:
Merry Shell(e)y [weekly-2025-w50]
- December 15, 2025
- Patrick Ferris
Aside from a serious amount of admin, last week I decided to spend a majority of my time thinking about shells.
What is a shell?
- December 15, 2025
- Patrick Ferris
There is no single definition of what a shell is or isn't.
AI Blues [ai-blues]
- December 15, 2025
- Patrick Ferris
Undoubtedly last week, I suffered a severe case of "AI blues" (for lack of a better description).
I have been doing some thinking, trying to distil my own thoughts on what aspects of vibecoding seem to irk me so much. Ultimately, it seems it is more about attitudes than anything else.
Exploitative
- December 15, 2025
- Patrick Ferris
Increasingly, I am finding that other people's vibecoded work is my problem. I have been an active participant in OCaml's outreachy work for going on five years now, and a problem mentors have to face is deciding the appropriate amount of help to give to your intern when they come to you with questions. More than likely, you could answer with specifics and solve the problem at hand. However, this doesn't scale very well and doesn't help your intern learn where else they may look for answers (e.g. Dune's documentation, a project's README page, OCaml's package explorer, heck even just using some simple CLI tools!) or how they might go about debugging a certain problem.
LLMs, in my experience, make this problem worse. When they come up short, they can leave their programmer higher and drier than they would be had they hit a problem on their own. There is an inertia to understanding problems now that there's lots of code lying around. Turning to your colleagues has a few problems that it didn't before:
Your colleagues don't know whose understanding they are correcting: yours or the LLMs?
If it is the latter, there seems to me to be an exploitative quality to even asking for help until you yourself know what's going wrong.
Technological Accelerationism
- December 15, 2025
- Patrick Ferris
There is no doubt that LLMs are pretty good at writing large amounts of okay code. The generation of this code, and often subsequent publishing of it, completely outpaces the ability to maintain it.
Programmers may be able to release ten times more libraries than they could before, but at the moment, they certainly cannot maintain ten times more libraries than they could before.
Scale --
Modular Explicits in OCaml [modular-explicits]
- Patrick Ferris
Abstraction, in OCaml, often refers to hiding a particular type's implementation using a signature. For example:
module S : sig
  type t
  val add : t -> t -> t
end = struct
  type t = int
  let add = Int.add
end
In this post, however, I use abstraction to refer to the notion of code-reuse. Using features of the OCaml language to allow one piece of code to be used across different implementations or instantiations of a particular kind of value.
The goal of this post is to eventually discuss OCaml 5.5's modular explicits which is yet another feature that can allow a single piece of code to be used in various situations.
Polymorphism [abs-polymorphism]
- Patrick Ferris
The most prevalent kind of abstraction is polymorphism. For example, List.length will work for all lists regardless of what kind of elements the list contains. However, polymorphism requires you to keep the polymorphic part of the type at arm's length. This can lead to suboptimal performance and/or limited usefulness.
List.mem is a good example; in order to be polymorphic List.mem relies on Stdlib.(=), the polymorphic equality operator. In turn, this operator achieves its polymorphism by performing a structural comparison of the runtime representation of its arguments.
A common way to overcome this is to use higher-order functions (functions that take functions as arguments).
# let rec mem ?(eq=Stdlib.(=)) v = function
  | [] -> false
  | x :: xs -> eq v x || mem ~eq v xs
val mem : ?eq:('a -> 'a -> bool) -> 'a -> 'a list -> bool = <fun>
# let mem_int_list = mem ~eq:Int.equal
val mem_int_list : int -> int list -> bool = <fun>
This works well in plenty of cases (List.map, Hashtbl.iter, etc.), however, it doesn't scale well from a user's perspective if the body of the function requires lots of specific functions (e.g. compare, length, pp). At the same time, we want to avoid the precarious duck-typing of something like Python too.
Functors [abs-functors]
- Patrick Ferris
Functors are perhaps the second most prevalent feature of OCaml when it comes to code reuse. In the OCaml sense, a functor is a module that is parameterised by other modules. Set.Make is a functor that requires a module adhereing to the Set.OrderedType interface.
module IntSet = Set.Make (Int)
module StringSet = Set.Make (String)
Functors make it a lot easier to write implementations that depend on a large variety of functionality. Set.OrderedType is relatively tame in this sense, only needing a type t and a compare : t -> t -> int function.
Irmin, on the other hand, has functors that require users to provide Schemas. I have more thoughts about this API design in my Irmin retrospective.
It is important to consider the runtime costs of functors too. Whilst most of the time functors are instantiated at the toplevel, it does not come for free. You can have a play around with js_of_ocamlopt and see the generated output for how functors are applied.
First-class Modules and Existentials [abs-fcm-exist]
- Patrick Ferris
Sitting somewhere inbetween polymorphism and functors are first-class modules with existentials. This is a rather advanced use of OCaml's type system to be able to pack together a value of a particular type alongside a module that works with those kinds of values.
type set = Set : ((module Set.S with type t = 'a) * 'a) -> set
let size (Set ((module S), s)) = S.cardinal s
Packaging up integer sets is fairly straight-forward.
# let int_empty_set = Set ((module IntSet), IntSet.empty)
val int_empty_set : set = Set (<module>, <poly>)
From a user's perspective we are now closer to the realm of dynamic typing. Indeed, existentials are the way to do that in OCaml.
# type any = Any : 'a -> any
type any = Any : 'a -> any
# let any v = Any v
val any : 'a -> any = <fun>
Getting back into a typed world often involves some type witness gymnastics or runtime exceptions. Used sparingly, however, it can be very effective particularly when a user is none the wiser about the use of FCMs and existentials. I have made use of this trick to package together Irmin stores with implementations.
You could not, however, simply return the value that was packed away inside the existential.
# let woops (Set (_, s)) = s
Line 1, characters 26-27:
Error: The value s has type $a but an expression was expected of type 'a
       The type constructor $a would escape its scope
       Hint: $a is an existential type bound by the constructor Set.
There is also a runtime cost to the packing (and unpacking) of the module, not to mention the need for the extra allocation to create the existential in the first place. This will likely not be too significant, but is worth considering.
Modular Explicits [abs-modular-explicits]
- Patrick Ferris
OCaml 5.5 has module-dependent function types also known as modular explicits. The type of a function can now depend on types that come from a module that is also part of the function definition.
# let set_length : (module S : Set.S) -> S.t -> int =
  fun (module S) v -> S.cardinal v;;
val set_length : (module S : Set.S) -> S.t -> int = <fun>
# set_length (module IntSet) IntSet.empty;;
- : int = 0
# set_length (module StringSet) StringSet.empty;;
- : int = 0
In fact, we can now return values of a particular type that depends on a particular module!
# let empty_set : (module S : Set.S) -> S.t =
  fun (module S) -> S.empty;;
val empty_set : (module S : Set.S) -> S.t = <fun>
# empty_set (module IntSet);;
- : IntSet.t = <abstr>
# empty_set (module StringSet);;
- : StringSet.t = <abstr>
Or, we can dynamically select implementations and values.
# let with_impl :
    config:string -> ((module S : Set.S) -> S.t -> 'a) -> 'a =
  fun ~config fn ->
  match String.lowercase_ascii config with
  | "string" -> fn (module StringSet) StringSet.empty
  | "int" -> fn (module IntSet) IntSet.empty
  | c -> invalid_arg c
val with_impl : config:string -> ((module S : Set.S) -> S.t -> 'a) -> 'a =
  <fun>
This is like a more usable version of the FCM-existential trick, though does require more manual type annotations on functions. For instance, I tried switching out OBuilder's use of existentials with modular explicits:
-type builder = Builder : (module Obuilder.BUILDER with type t = 'a) * 'a -> builder
-
 let log tag msg =
   match tag with
   | `Heading -> Fmt.pr "%a@." Fmt.(styled (`Fg (`Hi `Blue)) string) msg
   | `Note -> Fmt.pr "%a@." Fmt.(styled (`Fg `Yellow) string) msg
   | `Output -> output_string stdout msg; flush stdout

-let create_builder store_spec conf =
+let create_builder :
+  Store_spec.store Lwt.t -> Native_sandbox.config ->
+    ((module B : Obuilder.BUILDER) -> B.t -> 'a) -> 'a Lwt.t =
+  fun store_spec conf fn ->
   store_spec >>= fun (Store_spec.Store ((module Store), store)) ->
   let module Builder = Obuilder.Builder (Store) (Native_sandbox) (Docker_extract) in
   Native_sandbox.create ~state_dir:(Store.state_dir store / "sandbox") conf >|= fun sandbox ->
   let builder = Builder.v ~store ~sandbox in
-  Builder ((module Builder), builder)
+  fn (module Builder) builder
I think the code is more pragmatic; there is no longer an indirection via a type called builder. The extra type annotations do add a little noise. Roll on modular implicits.
Vibecoding Etiquette [vibecoding-etiquette]
- March 9, 2026
- Patrick Ferris
I am yet to jump head-first into using LLM-based tools like Claude Code or even ChatGPT to help with my programming in any serious way. After using some "free"-tier tools to try to better understand some tricky eBPF problems and to make sense of the semantics of POSIX shells, I was left unimpressed and ultimately felt my time was wasted.
I feel unwilling to send my money to the corporations behind these tools. This is for a variety of reasons including the deeply worrying relationship with the US Department of War (I struggle to find the meaningful difference between "opertational planning" vs. "operational decision-making" given the leaders of the US DoW), environmental concerns, exploitation of human labour and a fast-and-loose approach to copyright laws. All of which leaves the entire industry very unattractive to me.
Everybody can draw their line where they want, and I am, in good faith, trying to find where mine should be.
Unfortunately, my own decision to not use these tools is not completely in my control. What do I do about pull requests to open-source libraries I maintain that include agentic code? I am, after all, participating in the idea of open-source and inclusive collaboration. Agentic code also comes in many flavours, from blatant LLM-generated pull requests to heavily edited, human-in-the-loop contributions.
An immediate first step for me is to develop some policy for contributions to projects I maintain regarding code where LLMs have had a hand. This can help set expectations for contributors. Eio's "AI-generated Code" subsection is succinct and prohibits contributions that solely use AI.
It obfuscates how you think. Purely AI-generated code tells us little about how you think and the problems you might be having. This makes it harder to provide good feedback on PRs and issues.
It is often more work to review. Particularly for the OCaml ecosystem and libraries like Eio, it seems that these tools are not very good and generate a lot of believable code that is in actual fact completely wrong. PR comments and the code submitted with them can say completely different things.
It is a grey area for licensing. Models like ChatGPT have been trained on lots of code with different licenses and has been known to simply copy code as an answer to a prompt. We would like to avoid this headache as best we can.
Additionally, I plead to other developers to own their use of these tools. Please, make Claude a co-author of the commits where Claude has generated any code at the very least. This is the bare minimum. I have strong feelings about the etiquette of sending AI summarised information or LLM-generated code to other people, but before any of that, the decent thing is to remove any uncertainty in the receiving party's mind of how the information they are receiving came to be. In this way, I appreciate the OCaml compiler's AI notice which includes:
If a significant portion of your code, PR description, review comments or messages has been AI-generated, this must be disclosed, stating which tool was used and for what. Reviewing AI-produced code can require a different approach from human-written code. You should have an acknowledgement anyway even if another human contributor did some of the work.
ICFP 2025 [icfp-2025]
- October 24, 2025
- Patrick Ferris
Two weeks ago I was fortunate enough to attend the International Conference on Functional Programming in Singapore. My first time in Asia and my second time at the conference, what follows are some thoughts and presentations I enjoyed whilst I was there.
I must thank my office mate (and friend!) Ryan Gibb for his camaraderie and sage advice: "the best track is hallway track". Not to mention all of his photos too. Thanks Ryan!
From right to left, top to bottom: Anil Madhavapeddy, Sadiq Jaffer, Patrick Ferris, Ryan Gibb and Roy Ang.
Random Hacking
- October 24, 2025
- Patrick Ferris
Below are just some of the pieces of random hacking I got up to whilst in Singapore.
OxCaml and Uring [oxcaml-and-uring]
- Patrick Ferris
Jane Street were a big presence at ICFP 2025, carting along with them a shiny new OCaml compiler: OxCaml. If have been playing around with OxCaml recently but nothing outside toplevels in Javascript. Until now!
After talking to David, I spent some time converting a small corner of the ocaml-uring library to use a part of OxCaml. In particular making the following change:
  module Heap = struct
    type ptr = int32#
    (* ... *)
  end

  type cqe = {
    user_data_id : Heap.ptr;
    res : int32#;
  }
The idea being that a completion queue entry (a notification that some operation has completed) could be fully represented using 64 bits (two 32-bit, unboxed values). You can see how this impacted the library! I'm not certain about this change (and I'm sure I did it wrong) but it was nice to realise OxCaml gives you this kind of control. However, I am worried about the ergonomics of manipulating values like int32# and the temptation to case it into an int (presumably losing a good portion of the value of having an unboxed value in the first place).
Bibtex Parser
- October 24, 2025
- Patrick Ferris
On the flight over to Singapore, I started to write a post for this website. Some readers may remember that I use forester after a preprocessing step via graft to build this site. Part of that preprocessing consumes bibtex files and outputs forester trees. For the initial graft release I used the excellent Talaria Bibtex library. Unfortunately, it presented a pretty confusing API that, whilst nicely typed, felt a little cumbersome to use. Additionally, it was too specific in what it would accept as valid Bibtex. I wanted something that was a little more straight-forward to use (if a little fast-and-loose when it comes to types...). And so I built bib.
This was my first real attempt at using the Bytesrw library. I was happy with the results, although I did have to copy a substantial amount of code from other bytesrw-compatible libraries. I'd be happy to shift to this bytes-first world if it wasn't for the ever-present-in-my-mind issue of relocatable values in the OCaml heap!
Geocaml Libraries
- October 24, 2025
- Patrick Ferris
There has been some excellent outreachy work happening on the geocaml/ocaml-tiff library which is a potential Outreachy internship project for December 2025. More on this in a future post.
On the way back (and a little during the conference), I spent some time building an OCaml counterpart to geotessera, a library for working with Tessera. The library is not ready for people to use directly, but I was working on various constituent parts including:
Modern OCaml bindings to PROJ (a coordinate reference system projection library)
Coming soon... ocaml-geotessera
Talks
- October 24, 2025
- Patrick Ferris
Hazel of OCaml at TyDe
- October 24, 2025
- Patrick Ferris
The type-driven development (TyDe) workshop was held on the first day of ICFP at the NUS School of Computing. I find the workshop name to be a little misleading, but perhaps this comes from my engineering background. The talks focused a lot on type theory, presenting the formal mathematics of interesting type systems with less focus on why it might be useful to have such an exotic type system... but then again, that was the nature of the entire conference.
I presented a talk on hazel_of_ocaml. The slides are here, along with the extended abstract. My talk ended up focusing a lot on the pedagogical benefits of having a type system that helped explain the most important thing a type system does... catch type errors! This work represents a small piece of work inside Max Carroll's excellent part II project, which he presented at the HATRA workshop: Decomposable Type Highlighting for Bidirectional Type and Cast Systems.
Scientific Programming at PROPL
- October 24, 2025
- Patrick Ferris
I think it is important to be honest whenever you get a talk accepted that you otherwise feel should not have been. My talk "what we talk about when we talk about scientific programming" is one such talk. The slides are here. The talk itself was nothing to write home about, but I think there were a few nice ideas that came out of it and the conversations I had with fellow PROPL attenders.
TMF Data Discrepancies Redux
- October 24, 2025
- Patrick Ferris
On the eve of my talk, I decided to re-run some analysis I did a few years ago on the tropical moist forest dataset, knowing that since then a few more years had become available. After fighting with some bit-rot in the Google Earth Engine script I had used, the new results were not very uplifting.
| Land Use Class | Percent Change |
| Undisturbed | -2.9 |
| Degraded | -5.5 |
| Deforested | 8.6 |
| Regrowth | 0.5 |
| Water | 0.0 |
| Other | -0.6 |
The data in the table corresponds to the land use class values in Indonesia in the year 2008. The analysis computed the difference across each of the classes between the dataset released in 2021 and the dataset released in 2024. Most notably, the amount of deforested land has gone up by 8.6 percent!
As a somewhat tangential, though related, aside, I had the pleasure of talking to Sam Westrick, Seong-Heon Jung and Sundara Vishnu Satish of the ParCour research group. They were telling me about MaPLe, a programming language from the MLs built for parallelism. We discussed some ideas of using real-world, geospatial algorithms as benchmarks for MaPLe. Michael, if you got this far remind me to chat to you about this!
Shelter Reactions
- October 24, 2025
- Patrick Ferris
At the end of my talk, I briefly mentioned shelter. By far, this was the topic I got the most engagement on post-talk. During the conference, this was also true when people asked what I was working on. The tag line "a shell with undo" seemed to capture the attention of most people.
I'm feeling a renewed sense of interest in my own work thanks to that, even if the "research" contributions are not very apparent. However, I also had a good discussion with KC about the underlying MRDT in Shelter and how we might think about collaborating in the future on MRDT-related work.
Related to that, I managed to spend the evening in Chinatown with Roly Perera. Roly's work has focused on Fluid, a transparency-based programming language that allows authors to reveal their computation to their user. Excitingly, Roly presented a new text-based part of the language at PROPL. Our work is in the same universe, loosely orbiting some notion of reproducibility and explainability, but quite different in engineering work and how users might actually interact with our systems. I thoroughly enjoyed talking about solutions or research ideas that preserve existing workflows. Roly was great at pulling that out of the current work I have been doing.
Other Talks and Highlights
- October 24, 2025
- Patrick Ferris
I was a part of, often in a very small way, some other talks that were presented at ICFP including
Functional Networking for Docker, I encourage you to read Anil's notes on the topic. It is also worth mentioning Anil's post-posix talk (not unrelated to my Uring musings above).
Michael gave an excellent, very live, talk about Yirgacheffe at PROPL which I thoroughly enjoyed. I'm also excited about his recent developments which I'm sure you can clue into over on his blog.
Below is a non-exhaustive list of talks I enjoyed whilst at the conference. Some relevant, most of them not!
By far, one of the best talks was Polynomial-time Program Equivalence for Machine Knitting. I think the talk really nailed the "here's the idea, the details are in the paper"-presenting style as they described an "...algorithm that canonicalizes the algebraic representations of the topological semantics of machine knitting programs".
I attended most of the OxCaml tutorial presented by the incredibly friendly Gavin Gray.
Ryan's talk Spatial Programming for Environmental Monitoring at PROPL was excellent.
There's plenty more to talk about, and I'm sure my future posts will reference other parts of my experience at ICFP 2025. Thanks for reading, and if anybody is interested in any aspects of this do reach out!
Irmin Retrospective [irmin-retro]
- August 7, 2025
- Patrick Ferris
Irmin is an OCaml library for building branchable and mergeable data stores. The data is mergeable in the sense of mergeable replicated data types.
I have been using Irmin for over five years to build different kinds of interesting data stores including:
Mentoring an intern who worked on Irmin in the browser.
Most recently, an Irmin-backed shell session manager.
I was asked to provide some feedback recently on Irmin, so I thought writing a little retrospective here would be a good way to do that. The remit for the retrospective was about improving Irmin, so the content is focussed on pain points and areas of improvement.
(* An in-memory Irmin store *)
module Store = Irmin_mem.KV.Make(Irmin.Contents.String)
What is Irmin?
- August 7, 2025
- Patrick Ferris
Irmin, at its simplest, is a key-value database. Users associate keys with values and can query and update these bindings.
Additionally, this database supports versioning. This means independent snapshots of the database can coexist and users can switch between them and update them without fear of interfering with other versions.
Different versions of the database can be combined by merging. When you set up your instance of an Irmin database, you also provide it with a merge function.
# #show_type Irmin.Merge.f;;
type nonrec 'a f =
    old:'a Irmin.Merge.promise ->
    'a -> 'a -> ('a, Irmin.Merge.conflict) result Lwt.t
Design and API
- August 7, 2025
- Patrick Ferris
Irmin's API is very git-inspired. There is a large overlap of shared vocabulary and concepts: repositories, branches, commits, heads etc.
Probably the most confusing aspect of this is the notion of a Store. When I was describing Irmin above, I used the term database to help distinguish between some of these concepts. In Irmin's documentation, it is used for multiple related (but different) concepts. In "Creating a Store" stores refer to the entire database, whereas in the Irmin API docs we have that:
There are two kinds of store in Irmin: the ones based on persistent named branches and the ones based temporary detached heads.
For Irmin library users, a Store.t can be thought of as a checkout of the database at a particular revision. This may be from a branch or a specific commit.
# Store.of_branch;;
- : Store.repo -> string -> Store.t Lwt.t = <fun>
# Store.of_commit;;
- : Store.commit -> Store.t Lwt.t = <fun>
The overloading of the term is confusing. I think it leaves users unsure about what other people might mean when they say "store". Being careful with these terms, and the contexts in which they are used, would help avoid this confusion.
Module and Functor Soup
- August 7, 2025
- Patrick Ferris
Undoubtedly for a majority of use-cases and users, Irmin is over-functorised. Nearly every module requires that you must apply some functor to access any useful code. In general, a user will have to interact with the Schema module when describing the types they want to instantiate their store with.
To counteract this, Irmin has plenty of KV modules that provide a Make functor that only requires a user to provide a suitable content module for their store (i.e. something that provides a type, a runtime representation of that type and a merge function).
# #show_module Irmin_mem.KV;;
module KV :
  sig
    type endpoint = unit
    type metadata = unit
    type hash
    type info = Store.info
    type ('h, _)contents_key = 'h
    type 'h node_key = 'h
    type 'h commit_key = 'h
    module Make : (C : Irmin__.Contents.S) ->sig ... end
  end
I think it is fair to say the documentation is hard to follow as it is a module and functor soup. For example, looking at irmin.3.11.0, starting at the toplevel documentation page our path to finding this paricular module and functor is as follows:
We jump into
Irmin_memfrom the nicely written landing page.We scroll down to find the KV module.
We now make sense of the module's signature by following the KV_maker link.
We see a
Make (C : Contents.S) : sig ... endat the end of the module, and we navigate through that.Finally we have come to our journey's end, and find the schema module with type constraints like
type Branch.t = string.
There is a big assumption there that you know what the Schema module is telling you and how it relates to your "store".
There is a counter-argument here, in that Irmin is incredibly flexible in terms of what you can use as types for your keys, branches, hashes etc. I was quite easily able to produce Irmin stores that use CIDs (self-describing content identifiers) for example.
I think there is a middle ground. For Irmin to be usable it needs to reduce the complexity of the API. The complexity is due to, in large part, over-functorisation. If the functors cannot be removed then perhaps better documentation or more introductory libraries like irmin-containers would be helpful. Perhaps a standalone library that acts as an interface to Irmin stores would be helpful. I find myself time and again implementing something like that.
Backends Galore
- August 7, 2025
- Patrick Ferris
Irmin has plenty of backends including a git-compatible one, a MirageOS backend, an in-browser IndexedDB backend and even a FoundationDB backend.
Irmin needs to have fewer, better tested backends. Of course, some of these are likely driven by funding and use-case specific details. However, I think by focusing on a few key backends and striving for solid performance but also strong consitency guarantees, Irmin would become a more viable candidate for potential users. I also believe the browser backend plays a key part to making this work in order to facilate local-first applications.
Syncing Remote Stores
- August 7, 2025
- Patrick Ferris
The synchronisation mechanisms in Irmin are powerful, but often the API is very confusing. For example, with the git-compatible Unix backend, nested deep in the documentation is the function required to create a remote endpoint. Once they have found this function, using it is not easy as it requires them to learn about the Mimic.ctx, which is an abstraction of the networking stack!
Do Fewer Things and Do Them Well
- August 7, 2025
- Patrick Ferris
Irmin is simultaneously a database that supports: content-addressing, merging, key-value lookup, branches, transactions, complete OS portability etc. I think, in short, it tries to do too many things and comes up short on some of them in ways that really matter.
When building the content-addressed database I needed strong guarantees about some atomic actions to perform on the underlying store. For example, setting the value and accessing the commit associated with it which was not possible with the API at that time in an atomic way. This kind of missing functionality is probably only understood after users stumble across it, but it also makes the library feel less focused and ready for production use-cases.
Documentation
- August 7, 2025
- Patrick Ferris
It will probably come as no surprise that one of the main limitations of using Irmin is the lack of documentation and tutorials. This is a particular pain point as the API is not very straightforward.
A while back, I started an Irmin book intending to help document the kinds of things real-world users would need in order to use Irmin in earnest. For example: ways to deal with type migrations or primers on runtime types. I still believe this sort of work would be invaluable, but there is a large cost to completing it, and it is not clear if there is enough interest in the project to warrant such an effort.
The tutorials on the irmin website are still good starting points for most new users. But they quickly lack the depth for real-world scenarios.
Feature Wishlist
- August 7, 2025
- Patrick Ferris
What follows are additional ideas for improving Irmin.
Heterogeneous Stores
- August 7, 2025
- Patrick Ferris
For all of [Irmin]'s abstraction and functorisation, there is a very clear missing feature for lots of first-time users of the library: you can only store values of a single type.
This leads to a few common workarounds:
Storing a serealised version of your values, essentially escaping the type-system and implementing a form of dynamic typing.
Growing your value to hold lots of different types via some large variant type.
Both of these options are feasible and have been used in practice. However, they are workarounds. A long time ago CraigFe created an RFC for heterogeneous stores, which I think about a lot. The main idea is to augment Irmin paths (keys) to be GADTs that carry type information about the kinds of values they access (similar to heterogeneuous variants of other data structures). Something like this alongside a simplified API would make Irmin more appealing as a library for persistent data storage.
Real-world Retrospectives
- August 7, 2025
- Patrick Ferris
This echos some thoughts from the Documentation section. There are some very real-world Irmin use-cases out there. For example, for a long time (I'm not sure if this is still the case) parts of the Tezos blockchain were using Irmin which uses the irmin-pack backend. Does this make irmin-pack the best tested backend and perhaps should be the default backend for new users? Or is it hyper-specific to the Tezos use case? There are blogs on tarides.com about the irmin-pack backend, but they might be outdated and should not be the first place to find advice on which Irmin backend to use.
Active Development and Engagement
- August 7, 2025
- Patrick Ferris
As far as I know, Irmin was at the forefront of technologies that have come to be described as local-first. There is a growing interest in this area (particularly as it acts as a counter-argument to an increasingly online, centralised model). I highly recommend reading Ink & Switch's essay on the matter. And it would be great to see more research via Irmin at things like the lofi unconference and the PLF workshop at SPLASH 2023!
Thank you for reading! And thank you to all the Irmin contributors. I hope this might be useful in the future for building the next-generation Irmin!
Slipshow x x-ocaml [slipshow-x-xocaml]
- July 23, 2025
A short, explanatory post about combining two very fun pieces of work in OCaml.
Paul-Elliot has been building Slipshow for some time now where slides are slips and your presentations run vertically. More recently, Arthur has built x-ocaml, a web component library for executable OCaml cells embedded into OCaml.
Using xocmd, a small tool I built for translating markdown codeblocks to x-ocaml components, your Slipshow's can now be executable!
xocmd learn-effects.md | slipshow compile - > learn-effects.html
Take a look at an example! (or the source markdown).
I really like this light-weight approach to building interactive presentations for explaining things in OCaml (e.g. over running a jupyter notebook server).
Quarterly OCaml Q2 [ocaml-quarterly-q2]
- July 18, 2025
- Patrick Ferris
Thanks to Tarides sponsorship, I get to work on open-source OCaml. This quarterly is a companion to my weeklies, summarising the last three months of development, peppered with ideas and thoughts about OCaml, its community and its future.
What I wanted to work on?
- July 18, 2025
- Patrick Ferris
There were two main things I hoped to continue working on: ppxlib and outreachy. These are projects that I was previously working on, and in the case of Outreachy I have now been involved for many years.
In addition to this, all of my Part II projects this year used OCaml in some regard. In general, I want to see more adoption of OCaml. Over the years this has taken many forms including my initial work on developing workflows for OCaml that just turned five years old. This directly fed into the rebranding and rethinking of ocaml.org itself.
What I worked on?
- July 18, 2025
- Patrick Ferris
Ppxlib
- July 18, 2025
- Patrick Ferris
Ppxlib is the de facto standard library for building OCaml preprocessors. At the time of writing, opam list --depends-on=ppxlib informs me that there are 267 reverse dependencies. Janestreet is a heavy user of ppxes and has authored many.
One of the main accomplishments this quarter was bumping the internal AST to 5.2. This allows ppx authors to use new OCaml language features in their ppxes. In bumping the AST, we knowingly broke compatability for pretty much every single reverse dependency. As best we can, we have been sending patches to ppx libraries and helping users migrate to the latest ppxlib.
There is an interesting dicussion to had about the nature of open-source, and its interaction with industrial monorepos and community tended package repositories. Package ecosystems thrive whenever there is a dedicated community creating, maintaining and publishing packages. The idea is that the published world should be healthy. The publishing medium can act as natural limiting factor in the churn of breaking changes (in the case of OCaml this is via PRs to the opam-repository). This, I have come to notice, reacts poorly to changes coming from internally consistent monorepos where introducing breaking changes is easily fixed by applying patches there and then. Whatsmore, OCaml is often stated as an incredibly safe language to perform large refactorings thanks to its type system.
Ppxlib sits awkwardly in the space of possible breaking changes. Tied to OCaml's parsetree, impacts of changes there ripple down to ppxlib. The compiler itself can remain internally consistent, and is protected as it need only parse source code. Ppxlib, on the other hand, exposes the parsetree to users and thus any changes to the parsetree will likely be felt by ppx authors. Since I started working on ppxlib, it feels as though the number of syntax changes has gone up (primarily from Janestreet work). Unless we make changes to how we provide support for these, maintainers of ppxlib will forever be stuck doing busy work! Thankfully, Nathan has thoughts on how to improve this.
There are a slew of other features I have added to ppxlib including:
Support for deriving from classes.
Support for deriving from module bindings and signatures.
Fixing compiler and ppxlib dummy locations.
Bumping to 5.3.
Migrations for 5.4.
Outreachy
- July 18, 2025
- Patrick Ferris
Our two projects this year, one on claudius and one on dune, are going extremely well. At the time of writing, we just had a mid-internship call to catch up, and I was blown away by the progress each intern has made. Unfortunately, Outreachy is struggling with funding and the next round is perhaps not going to happen. This is a real shame and I am hoping that it will not be the case.
Outreachy has been a wonderful source of new, committed OCaml developers. If you haven't already, do peruse the webpage on OCaml.org to see past internships or watch the demo day presentations. For the mentors involved, I believe it has also been a rewarding experience (though at times a challenging one). We are always looking for new mentors and project ideas, please do reach out to me if you are interested.
Hazel
- July 18, 2025
- Patrick Ferris
OCaml's feature set allows it to shine at writing programming languages (and things of that ilk: compilers, interpretters, static analysis tools). Hazel is a research programming language with typed holes written completely in OCaml (via the reason dialect).
Relating this back to the original intent of my work, to improve OCaml adoption, I believe this also means keeping existing users happy. In the last quarter I developed a compiler from OCaml to Hazel. Whilst new features are still being added to Hazel, I hope this could serve as a tool to help develop test-suites and standard library functions using existing OCaml solutions. In a student's work (Typed Debugging for Hazel), we used this tool to build a corpus of ill-typed Hazel programs to great effect.
OCaml should continue to be a world-class programming language for building other programming languages. I hope to upstream some of this work to Hazel and provide some low effort maintenance to help keep their compiler in good shape.
Systems Programming in OCaml
- July 18, 2025
- Patrick Ferris
In a cross-over with my own research, I have been developing many tools related to systems programming in OCaml including:
An eBPF-based
opensyscall tracing tool.A library in OCaml for spawning void processes.
A shell session manager that uses Irmin to manage sessions. It is nice to see a new push to finally land the direct-style Irmin PR!
This work is means to develop the underlying libraries that support it. For example, I have opened a few PRs to Eio to add new "fork actions" to the spawn API. I also investigated the feasibility of changing the underlying mechanisms in Eio to use Picos. In the future, I think this could be important avoid further splitting the OCaml ecosystem.
OxCaml
- July 18, 2025
- Patrick Ferris
I dabbled a little with OxCaml and build try-oxcaml to let people take it for a spin without having to perform opam repository gymnastics. It turned into a lot of work to track down some pretty inane bugs (type definitions differeing between js_of_ocaml and the OxCaml compiler, resulting in different Javascript runtime representations...).
This unblocked a few of my colleagues to get OxCaml working on tools like odoc_notebooks and x-ocaml.
Forester
- July 18, 2025
- Patrick Ferris
A good proportion of my work this quarter has been focused on how to present the very work that I am doing. Jon Sterling has been developing a tool for scientific thought called Forester which seemed like a possible candidate for writing and sharing my work.
Porting my existing blog posts and website content from markdown to Forester's LaTeX-inspired syntax didn't seem like an option. In particular, many of my posts made use of additional markdown-based tools (like ocaml-mdx).
This lead to the development of Graft: a preprocessor for Forester forests, converting markdown and bibtex to trees.
What's next?
- July 18, 2025
- Patrick Ferris
So, I worked on most of what I wanted to work on and then some! Going forward I hope to keep maintaining ppxlib in some capacity and coordinating the OCaml community's Outreachy efforts.
I hope to continue my small experiments (e.g. converting Eio to Picos). My own research makes heavy use of Irmin, and I would be interested to help with that too. More recently, a new library has been released for working with numerical data in OCaml called Raven: I am interested to use this library in Geocaml, a suite of geospatial tools written in OCaml that I maintain.
I feel conflicted about the OxCaml efforts. I admit, I am not fully aware of the full benefits of the features, but I worry about some proliferation of modes that make the type system in OCaml unbearable to use. On top of this, with my ppxlib hat on, I worry about the impact of changing the compiler so frequently, placing strain on an already small community. That being said, by releasing OxCaml separately I do believe running it as an experimental set of packages will help understand the tool better. But I would not be building anything I intend to maintain or research with right now as that ecosystem is far too volatile.
Finally, over the past two years I have done a lot of teaching. From Part II projects to supervisions. Going into next (academic) year, I intend to reduce my in-person teaching to focus on my research. However, I am interested in producing more materials for learning, maybe some of this in OCaml, perhaps something similar to Beautiful Racket. I have tried in the past to do these sorts of things, for example The Irmin Book.
Thank you
- July 18, 2025
- Patrick Ferris
Thank you for reading this wrap up! And thank you again to Tarides for letting me work so freely on things that I think are good for the OCaml community.
Opentrace [open-trace]
- May 19, 2025
- Patrick Ferris
- https://tangled.sh/@patrick.sirref.org/opentrace
Thanks to Koonwen's excellent libbpf bindings in OCaml, I have been building a little tool called opentrace to make it easier to track an executable's inputs and outputs.
This work was inspired my Michael's self-proclaimed "gross hack": pyshark. Whilst pyshark achieves its goals by injecting code into commonly used python objects and methods, opentrace uses eBPF. By using a lower-level API (hooks in the kernel), opentrace can remain programming language agnostic. However, less information is none about the user's intent compared to something like pyshark.
Monitoring the System
- May 19, 2025
- Patrick Ferris
opentrace has an all command that will trace the entire system.
$ sudo opentrace all --flags=O_WRONLY
pid,cgid,comm,kind,flags,mode,filename,return
16324,4417,".nheko-wrapped",openat,577,438,"/home/patrick/.cache/nheko/nheko/curl_alt_svc_cache.txt",47
16324,4417,".nheko-wrapped",openat,193,33188,"/home/patrick/.cache/nheko/nheko/cr3ZUHqBErIOe3PlwJ1SuU8zFKKxL12VzrRoHYMH.tmp",47
16324,4417,".nheko-wrapped",openat,577,438,"/home/patrick/.cache/nheko/nheko/curl_alt_svc_cache.txt",47
16324,4417,".nheko-wrapped",openat,193,33188,"/home/patrick/.cache/nheko/nheko/QfZTdZSuC56NdcDQ3aMxJc3BhMhAj8PmtYW1zFDP.tmp",47
2530,4235,"systemd",openat,524865,438,"/sys/fs/cgroup/user.slice/user-1000.slice/user@1000.service/app.slice/gammastep.service/cgroup.subtree_control",41
2530,4235,"systemd",openat,524545,0,"/sys/fs/cgroup/user.slice/user-1000.slice/user@1000.service/app.slice/gammastep.service/memory.min",41
2530,4235,"systemd",openat,524545,0,"/sys/fs/cgroup/user.slice/user-1000.slice/user@1000.service/app.slice/gammastep.service/memory.low",41
2530,4235,"systemd",openat,524545,0,"/sys/fs/cgroup/user.slice/user-1000.slice/user@1000.service/app.slice/gammastep.service/memory.high",41
2530,4235,"systemd",openat,524545,0,"/sys/fs/cgroup/user.slice/user-1000.slice/user@1000.service/app.slice/gammastep.service/memory.max",41
The --flags=O_WRONLY argument filters the events where the O_WRONLY flag was set in the call to open.
We also get the name of the current executable linked to the task (comm). The -wrapped is an artefact of using Nix.
Tracing an Executable
- May 19, 2025
- Patrick Ferris
The primary use case for this tool is to inspect what files your program might be reading and writing.
$ sudo opentrace exec --format=json --flags=O_CREAT -- opam list
$ cat trace.json | jq ".[] | .fname"
"/home/patrick/.opam/cshell/.opam-switch/packages/cache"
"/home/patrick/.opam/log/log-118747-29da3d.out"
"/home/patrick/.opam/log/log-118747-29da3d.err"
"/home/patrick/.opam/log/log-118747-29da3d.env"
"/home/patrick/.opam/log/log-118747-29da3d.info"
The "flags" argument can specify a small boolean formula for checking the open flags of a particular event with | (or), & (and), and ~ (not). Parentheses can be used for precedence.
$ sudo opentrace exec --flags="O_WRONLY|O_RDONLY" -- ocaml --version
Spawning Subprocesses
- May 19, 2025
- Patrick Ferris
One feature opentrace needs (in this proof-of-concept phase) is the ability to also trace subprocesses.
opentrace is primarily an eBPF program that is loaded into the kernel and communicates with an OCaml program. Events are communicated via a ring buffer and most of the post-processing happens in OCaml. To capture subprocesses, opentrace creates a new control group (cgroup) and places the new process into that group. This gives opentrace a new identifier to track, namely the cgroup.
So consider the following program.
let () =
  Eio_posix.run @@ fun env ->
  Eio.Path.(save ~create:(`Or_truncate 0o664) (env#fs / "hello.txt") "hello");
  Eio.Process.run env#process_mgr
    [ "/bin/bash"; "-c"; "echo 'heya' > heya.txt" ]
It first creates a file using direct calls to functions like openat. Then it spawns a process which creates a new file called heya.txt. This happens in a separate process. However, with the --cgroups flag we can capture both interactions with the operating system.
$ sudo opentrace exec --cgroups --flags="O_CREAT|O_TRUNC" ./main.exe
pid,cgid,comm,kind,flags,mode,filename,return
153187,530807,"main.exe",openat,526914,436,"hello.txt",5
153192,530807,"bash",openat,577,438,"heya.txt",3
Eio's Process API
- May 19, 2025
- Patrick Ferris
I have used the Eio_unix fork action process API to be able to extend what happens in the child process. Loading most eBPF programs into the kernel requires special privileges hence the need for sudo. When a user requests for a particular program to be executed and traced, opentrace spawns a process via the Eio Process API. Opentrace defines a few new so-called "fork actions", little fragments of C code that are run after the call to fork (clone). Most likely this ends with a call to execve, but other calls are possible for example setuid allowing opentrace to change the user of the child process so it does not run as root. Similarly, this is where (if used) we create the cgroup and place the process into that group.
Limitations: Io_uring
- May 19, 2025
- Patrick Ferris
Whilst testing opentrace against some of the tools I use nearly daily, I noticed some events were being missed. I tried tracing forester, and only the initial read of forest.toml was logged. It dawned on me that the reason for this was that forester (via eio) was using io_uring to perform most of the IO. Most attempts to open files were bypassing the open system calls, and instead they were being performed by the kernel after reading a submission request for an openat2-style call!
This is not news to seasoned, Linux systems programmers. Io_uring bypasses SECCOMP filters for exactly the same reasons.
$ sudo opentrace exec -- forester build
$ cat trace.csv
pid,cgid,comm,kind,flags,mode,filename,return
155007,535570,"forester",openat,524288,0,"forest.toml",5
155007,535570,"forester",Uring,2621440,0,"",0
155021,535570,"cp",openat,131072,0,"/home/patrick/documents/forest/theme/favicon-32x32.png",4
155007,535570,"forester",Uring,2686976,0,"",0
155007,535570,"iou-wrk-155007",Uring,557634,420,"",0
155007,535570,"iou-wrk-155007",Uring,557634,420,"",0
155007,535570,"iou-wrk-155007",Uring,557634,420,"",0
It is interesting to note two things here:
We can tell that forester reads the configuration file probably using something like
In_channelin OCaml (it does).It appears that Uring is performing IO in both worker threads and directly.
The file paths are empty at the moment as I cannot find a clean way to trace openat submission requests into Uring without it sometimes going very wrong. I have tried quite a few methods (e.g. tracing do_filp_open) and at the moment I am tracing io_openat2, but this seems quite brittle, and often the filename is completely garbled, so I do not set it. If anyone has any ideas to trace Io_uring more reliably, I am all ears!
Try OxCaml [try-oxcaml]
- May 9, 2025
- Patrick Ferris
- https://patrick.sirref.org/oxcaml
This week, I have been trying out Janestreet's Oxidised OCaml (see their ICFP paper). This adds a system of modes to OCaml for expressing things like locality.
...we’re introducing a system of modes, which track properties like the locality and uniqueness of OCaml values. Modes allow the compiler to emit better, lower-allocation code, empower users to write safer APIs, and with the advent of multicore, statically guarantee data race freedom—all in a lightweight way that only affects those in need.
For example, you might say:
let is_empty (s : string @@ local) =
  String.length s = 0
To get a feel for how this changes the language, you can follow their instructions on their custom opam-repository. Alternatively, you can give it a go in your browser! This is a full toplevel running with Base installed (which has plenty of OxCaml annotations on Stdlib-like functions).
Happy OxCamling!
A Transpiler from OCaml to Hazel [hazel-of-ocaml]
- May 2, 2025
- Patrick Ferris
Over the past few months, I have been piecing together a transpiler from Hazel to OCaml. This is, in part, to help one of my third-year undergraduate students who is working on type error debugging in Hazel.
Typed Holes
- May 2, 2025
- Patrick Ferris
Hazel is a functional programming language with typed holes. Holes are pieces of your program that have not yet been filled in. Holes can appear anywhere in your program both as expression or types. Hazel can still evaluate your program in the presence of holes.
To get a flavour of Hazel, take a regular map function for lists.
let map = fun f -> fun xs -> case xs
  | [] => []
  | x :: xs => f (x) :: map(f)(xs)
end in
map(fun x -> ?)([1, 2, 3])
The question mark (?) is a hole. The program evaluates to the following expression of type [?] (for people more familiar with OCaml types ? list).
[ ?, ?, ? ]
Hazel supports local type inference but nothing involving unification variables. For example, a simple add_one function in Hazel (fun x -> x + 1) has type ? -> Int.
From OCaml to Hazel
- May 2, 2025
- Patrick Ferris
The ability to transpile OCaml programs to Hazel programs is motivated by one simple thought: there are more OCaml programs than there are Hazel programs. This could help bootstrap projects by alleviating the need to rewrite boilerplate code (e.g. URI parsing or standard library functions for strings).
A Transformation of Syntax
- May 2, 2025
- Patrick Ferris
Hazel markets itself as an "Elm/ML-like functional programming language". From the previous example of map, it should be apparent just how close to OCaml the language is.
It turns out that a majority of the transpiler is a transformation of syntax. Take a simple ADT for an arithmetic programming language.
type expr =
  | Float of float
  | Add of expr * expr
  | Sub of expr * expr
  | Mul of expr * expr
  | Div of expr * expr
And when we run hazel_of_ocaml over this OCaml type declaration.
type expr =
  + Float(Float)
  + Add((expr, expr))
  + Sub((expr, expr))
  + Mul((expr, expr))
  + Div((expr, expr))
 in ?
Not much has changed expect some syntax. Hazel does not have a notion of top-level expression so hazel_of_ocaml wraps the program into one set of value bindings. For the most part, Hazel acts as a subset of the pure, functional part of OCaml. At the time of writing, this subset is fairly limited with no support for modules or labelled records out of the box (there are plenty of development branches with these features).
If we try out the same map function but written in OCaml and transpiled to Hazel we get.
let rec map f = function
  | [] -> []
  | x :: xs -> f x :: map f xs
Which becomes the following hazel program.
let map = fun f -> fun x1 -> case x1
  | [] => []
  | x :: xs => f(x) :: map(f)(xs)
end in ?
We could have a field day discussing the syntax of OCaml and Hazel (parentheses for function arguments, well-scoped cases for pattern-matching, a different arrow for pattern-matching etc.). What would be more interesting is taking a look at how to handle polymorphism in Hazel.
Explicit Polymorphism
- May 2, 2025
- Patrick Ferris
Hazel has explicit polymorphism. So far, we have not seen it as we have let the types have holes in them. The map function in OCaml has the following type.
val map :
  ('a -> 'b) -> 'a list -> 'b list
We must remind ourselves (by reading Craig's excellent blogpost on the matter) that in OCaml
... type variables in signatures are implicitly universally-quantified
So in reality, we have that map has the following type.
val map : ∀ a b. (a -> b) -> a list -> b list
In Hazel, we have to explicitly type our map function to be polymorphic. Not only does this mean the type annotation requires universally quantified type variables, but we must also perform type application wherever we choose to apply the map function (whether that be recursively or somewhere later in our program).
let map : forall a -> forall b -> (a -> b) -> [a] -> [b] =
  typfun a -> typfun b -> fun f -> fun xs -> case xs
    | [] => []
    | x :: xs => f (x) :: map@<a>@<b>(f)(xs)
end in
map@<Int>@<Int>(fun x -> ?)([1, 2, 3])
forall introduces a universally quantified type variable into our type annotation, and typfun introduces it into the function itself (à la System F). Type application requires @<T> where T is some type. This allows hazel to quite easily support higher rank polymorphism, but we will not worry too much about that.
Propagating OCaml Types into Hazel
- May 2, 2025
- Patrick Ferris
Most often, OCaml users interact with prenex polymorphism (rank-1) where the universal quantifiers are at the front of the type. OCaml does support quantifiers inside certain types like records.
What this means for the transpiler is that we can reuse OCaml's type inference to safely instantiate the correct type annotations and type applications in Hazel! To do this, hazel_of_ocaml uses Merlin to inspect the type of the function in either a value binding or at the point of a function application.
Take a simple, polymorphic length function.
let rec length = function
 | [] -> 0
 | _ :: xs -> 1 + length xs

let int_len = length [ 1; 2; 3 ]
let str_len = length [ "only"; "two" ]
When we run this through hazel_of_ocaml with the -type flag we get.
let length : forall a -> [a] -> Int = typfun a -> fun x1 -> case x1
  | [] => 0
  | _ :: xs => 1 + length@<a>(xs)
end in
let int_len : Int = length@<Int>(1 :: 2 :: [3]) in
let str_len : Int = length@<String>("only" :: ["two"])
in ?
hazel_of_ocaml has correctly instantiated the type for length inside the recursive function and then in each case with the integer list and the string list.
A Corpus of Hazel Programs
- May 2, 2025
- Patrick Ferris
The impetus for this work was to derive a corpus of ill-typed Hazel programs. Luckily, such a corpus exists for OCaml! Seidel et al. created a corpus of OCaml programs from their undergraduate students at UC San Diego. Some of these programs have been transpiled to Hazel.
Future Work
- May 2, 2025
- Patrick Ferris
Hazel is a fun, research programming language. Potential third-year students may find it interesting to take this work further. For example, how would this look in terms of a module system? From a purely engineering perspective, plenty of work would be needed to convert a multi-library OCaml project to Hazel (e.g. handling the cmi files).
Another line of research would be to have Hazel target one of the intermediate representations in OCaml which would give Hazel a fully functioning compiler to "native" code?
Bumping Ppxlib's AST to 5.2 [ppxlib-5-2]
- February 18, 2025
Ppxlib is a libary for building OCaml preprocessors. Users can generate OCaml code from OCaml code (derivers) or replace parts of OCaml code with other OCaml code (rewriters).
At the core of ppxlib is the OCaml parsetree; a data structure in the compiler that represents OCaml source code. Ppxlib makes a distinction between the source parsetree (based on the version of the OCaml compiler you are using) and ppxlib's parsetree (a copy of some parsetree from the compiler).
In ppxlib.0.36.0, the internal AST was bumped from the AST of OCaml 4.14.0, to the AST of OCaml 5.2.0. This post discusses some of the internal mechanisms that allows ppxlib to support multiple compilers and how this bump broke a lot of backwards compatibility.
Manual Migrations in Ppxlib
- February 18, 2025
It is possible to perform migrations between parsetrees manually using the ppxlib.ast package.
open Ppxlib
open Ast_builder.Make(struct let loc = Location.none end)
let pp_expr = Format.printf "%a%!" Pp_ast.(expression ?config:None)

let loc = Location.none
let str txt = { txt; loc }

module To_408 =
  Ppxlib_ast.Convert (Ppxlib_ast.Js) (Ppxlib_ast__.Versions.OCaml_408)
The Ppxlib_ast.Js module is ppxlib's AST (since ppxlib.0.36.0 OCaml 5.2.0). We can use functions provided by the Convert functor to copy parts of the AST from one version to another. Usually there is very little difference between the versioned parsetrees.
let func arg body =
  pexp_fun Nolabel None (ppat_var (str arg)) body

let add_expr = func "x" (func "y" (eapply (evar "Int.add") [ evar "x"; evar "y" ]))
The above excerpt of OCaml code produces an expression in the language. More accurately, a function that has two arguments. If we print the simplified AST we can see that the arguments are stored together in a list.
# pp_expr add_expr;;
Pexp_function
  ( [ { pparam_loc = __loc
      ; pparam_desc = Pparam_val ( Nolabel, None, Ppat_var "x")
      }
    ; { pparam_loc = __loc
      ; pparam_desc = Pparam_val ( Nolabel, None, Ppat_var "y")
      }
    ]
  , None
  , Pfunction_body
      (Pexp_apply
         ( Pexp_ident (Ldot ( Lident "Int", "add"))
         , [ ( Nolabel, Pexp_ident (Lident "x"))
           ; ( Nolabel, Pexp_ident (Lident "y"))
           ]
         ))
  )
- : unit = ()
This is a relatively new feature of the parsetree, if we migrate the expression down to 4.08 we see it is represented differently. The output is a little too verbose to be readable, and there's no good way to show the AST, so you will just have to take my word.
let expr_408 = To_408.copy_expression add_expr
Function Arity in the OCaml Parsetree
- February 18, 2025
OCaml 5.2 introduced a new way to represent functions. Before 5.2, all functions were represented with single arity. Functions with multiple arguments would return functions as their body. For example:
let add x y = x + y
A two-argument add function would be represented in the parsetree as fun x -> fun y -> x + y. Using the nodes from the parsetree (with some details removed) it would be Pexp_fun (x, Pexp_fun (y, Pexp_apply ...)).
Now, since OCaml 5.2, functions can be expressed with their syntactic arity intact. The function add would look something like Pexp_function ([ x; y ], Pfunction_body (Pexp_apply ...)). Both arguments are stored as a list.
The constructor Pexp_function was not a new addition to the parsetree. It used to represent pattern-matching expressions like function A -> 1. This can now be expressed as a function body of Pfunction_cases.
Whilst these additions and modifications to the parsetree are arguably a better design, it has caused chaos in terms of ppxlib's reverse dependencies!
Coalescing Function Arguments
- February 18, 2025
In ppxlib 0.36.0, functions from Ast_builder will help ppx authors produce maximum arity functions. However, functions from Ast_helper will not do this.
let ast_helper_func arg body =
  Ast_helper.Exp.fun_ Nolabel None (ppat_var (str arg)) body

let ast_helper_expr = ast_helper_func "x" (ast_helper_func "y" (eapply (evar "Int.equal") [ evar "x"; evar "y" ]))
Here we recreate our helper function to create function expressions using Ast_helper.Exp.fun_ instead. We can now show the difference between the expr expression and the ast_helper_expr expression.
# pp_expr add_expr;;
Pexp_function
  ( [ { pparam_loc = __loc
      ; pparam_desc = Pparam_val ( Nolabel, None, Ppat_var "x")
      }
    ; { pparam_loc = __loc
      ; pparam_desc = Pparam_val ( Nolabel, None, Ppat_var "y")
      }
    ]
  , None
  , Pfunction_body
      (Pexp_apply
         ( Pexp_ident (Ldot ( Lident "Int", "add"))
         , [ ( Nolabel, Pexp_ident (Lident "x"))
           ; ( Nolabel, Pexp_ident (Lident "y"))
           ]
         ))
  )
- : unit = ()
Above, we see a function expression with arity two. Below, we see nested function expressions each with arity one.
# pp_expr ast_helper_expr;;
Pexp_function
  ( [ { pparam_loc = __loc
      ; pparam_desc = Pparam_val ( Nolabel, None, Ppat_var "x")
      }
    ]
  , None
  , Pfunction_body
      (Pexp_function
         ( [ { pparam_loc = __loc
             ; pparam_desc = Pparam_val ( Nolabel, None, Ppat_var "y")
             }
           ]
         , None
         , Pfunction_body
             (Pexp_apply
                ( Pexp_ident (Ldot ( Lident "Int", "equal"))
                , [ ( Nolabel, Pexp_ident (Lident "x"))
                  ; ( Nolabel, Pexp_ident (Lident "y"))
                  ]
                ))
         ))
  )
- : unit = ()
Ramifications for Ppxlib Users
- February 18, 2025
Many, many, many ppxes broke after migrating the ppxlib AST to 5.2. Mostly, this is due to pattern-matching. Downstream users of ppxlib frequently pattern-match directly against the parsetree. However, nodes such as Pexp_fun no longer exist and Pexp_function has completely different constructor arguments!
Patching all the ppxes has been quite difficult. Most ppxes only deal with single arguments at a time (e.g. Pexp_fun x) but now they must handle zero or more arguments at a time. (In the zero case, this will always correspond to a pattern-matching function).
Here is a non-exhaustive list of some of the ppxes that have been patched. It may useful for other ppx authors who wish to upgrade to ppxlib.0.36.0:
https://gitlab.com/o-labs/ppx_deriving_jsoo/-/merge_requests/1
https://gitlab.com/gopiandcode/ppx-inline-alcotest/-/merge_requests/3
https://gitlab.com/o-labs/ppx_deriving_encoding/-/merge_requests/4
This release has emphasised the tension between using pattern-matching on algebraic datatypes and wanting to reduce downstream breakages (e.g. using abstract datatypes). This tension is not new.
The Future of Ppxlib
- February 18, 2025
Ppxlib is not going anywhere anytime soon. We have committed to trying to keep the internal AST up to date with the latest OCaml release. In fact, there is already a PR for the 5.3 bump!
There have been many discussions about simplifying this process, but so far the time and effort to build a ppxlib that will result in fewer breakages is too high (see an attempt using views).
Thank you to Tarides and Jane Street for funding my time to work on this release and all the chaos it has caused.
Happy preprocessing!
Defunctorising VPNKit [vpnkit-upgrade]
- February 28, 2025
VPNKit is a core part of the Docker for Mac/Windows stack. It is tasked with translating network activity from the host to the Linux container.
This short post discusses some of the recent changes to MirageOS and how they impact VPNKit.
Dune Virtual Libraries [dune-virt-libs]
Dune, for quite some time, has supported virtual libraries. This allows library authors to define a signature without an implementation (similar to OCaml's module type S = struct ... end). The package is something other dune libraries can build against, still without choosing a particular implementation of the interface. An application author can make the decision about which implementation they would like to build into their program.
This feature has been quite widely used in OCaml. For example, the excellent digestif library of hashing algorithms provides both C and OCaml implementations individually packaged into digestif.c and digestif.ocaml respectively. Consider developing a browser application that needs some hashing algorithm (e.g. Irmin in the browser). We can explicitly use the OCaml backend for digestif which js_of_ocaml will happily compile for us.
There are two distinct limitations to this approach.
Applications can only link exactly one implementation.
Implementations cannot expose additional functionality easily (see dune#5597).
Functors in MirageOS
- February 28, 2025
MirageOS is a framework for building unikernels in OCaml. It relies heavily on OCaml's functors to abstract implementation from interface. The mirage tool will then select appropriate instantiations of these functors depending on the backend that is targeted (e.g. unix, hvt etc.)
Recently, there has been a push to use dune virtual libraries instead.
VPNKit's Fake Clock & Time
- February 28, 2025
We need to be able to overcome the limitation that implementations cannot expose additional functionality very easily using dune virtual libraries. As it stands, we need to make Mirage's virtual libraries unwrapped (i.e. set (wrapped false)). This allows implementers to expose additional modules alongside the implementation of the virtual library.
For VPNkit, we need this to port some of the DNS forwarding tests which use a fake clock and sleep module. Previously, they could be provided directly as functor arguments to the various DNS modules e.g.
let module R =
  Dns_forward.Resolver.Make(Proto_client)(Fake.Time)(Fake.Clock)
In this new world of dune virtual libraries, our Resolver is significantly more simple.
let module R = Dns_forward.Resolver.Make(Proto_client)
The flexibility of time and clock implementation has been pushed to a build-time decision in a dune file. This means that in order to provide the same fake clock and time we will need to create a private dune library that (a) implements the respective signatures of the virtual libraries and (b) provides the extended interface to allow the test suite to modify the internals of the implementations.
The first thing I had to do was make the mirage-mtime and mirage-sleep virtual libraries unwrapped. This allowed me to make a new private dune library called fake_time with two public modules: the normal interface required by mirage-mtime and another module called Fake_time_state containing:
let timeofday = ref 0L
let c = Lwt_condition.create ()

let advance nsecs =
  timeofday := Int64.add !timeofday nsecs;
  Lwt_condition.broadcast c ()

let reset () =
  timeofday := 0L;
  Lwt_condition.broadcast c ()
I did the same for fake_sleep which depended on the state from the fake_time library (something a normal library wouldn't).
Once I had the implementations for the virtual libraries in place, all that remained was to tell the executable (in this case the test suite) to select these new implementations instead of the defaults. Whereas before, all the tests could live in the same test suite, now they had to be split into those that needed the fake implementation and those that did not. This is another slight limitation of this virtual library approach. You can only link one implementation at a time to an executable (or test). Thus, the dune rules for running the dns_forward test suite became:
; Uses the default  implementations provided by virtual libraries
(executable
 (name test)
 (libraries dns_forward alcotest))

; Override the defaults and select the private fake libraries
(executable
  (name test_fake)
  (libraries dns_forward alcotest fake_sleep fake_time))
With all of this machinery in place, I could now update test_fake to use the new modules that would provide the custom functionality for the clock and time implementations.
(* The bad server should be marked offline and no-one will wait for it *)
Fake_time_state.reset ();
(* avoid the timeouts winning the race with the actual result *)
Fake_time_state.advance Duration.(of_ms 500);
Conclusion
- February 28, 2025
The switch to dune virtual libraries seems to be a good one. A majority of applications only require a single clock or time implementation. However, it has become harder to inject custom implementations of various resources into your MirageOS-based applications.
Reviving OCaml R-Tree [ocaml-rtree]
- August 9, 2023
- Patrick Ferris
Antonin Guttman first proposed R-Trees in 1984.
In order to handle spatial data efficiently, as required in computer aided design and geo-data applications, a database system needs an index mechanism that will help it retrieve data items quickly according to their spatial locations...
There are lots of excellent resources for understanding more about R-Trees and all of the wonderful variations there of (e.g. R*-trees). This blog post seems to be the most popular introduction.
An OCaml Rtree Implementation [ocaml-rtree-001]
- Patrick Ferris
In the Energy and Environment Group we are working on various geospatial tools, one of which is written in OCaml and needed a geospatial index to speedup spatial queries over a dataset. Searching Github revealed an implementation in pure OCaml. After reaching out to the author, they were more than happy for their work to be maintained in the Geocaml organisation, updated to the latest OCaml tools and hopefully released on opam.
The dunification went smoothly whilst fast-forwarding 15 OCaml compiler versions with no changes or problems (just dune unused variable warnings).
OCaml Rtree Examples [ocaml-rtree-002]
- Patrick Ferris
An R-Tree in OCaml is created from an envelope (the kind of bounding box) and a value (for storing in the tree). The value depends on the envelope as you have to provide a function to calculate an envelope from a value. Here is one way we might define a line using the provided two-dimensional Rectangle envelope.
module Line = struct
  type t =
    { p0 : float * float; p1 : float * float }

  let t =
    let open Repr in
    record "line" (fun p0 p1 -> { p0; p1 })
    |+ field "p0" (pair float float) (fun t -> t.p0)
    |+ field "p1" (pair float float) (fun t -> t.p1)
    |> sealr

  type envelope = Rtree.Rectangle.t

  let envelope { p0 = (x1, y1); p1 = (x2, y2) } =
    let x0 = Float.min x1 x2 in
    let x1 = Float.max x1 x2 in
    let y0 = Float.min y1 y2 in
    let y1 = Float.max y1 y2 in
    Rtree.Rectangle.v ~x0 ~y0 ~x1 ~y1
end
In addition to the envelope function, we also need to provide a runtime representation using Repr. In the example, we've constructed it by hand but I recommend using ppx_repr to derive it for you. From here we can create our index.
module R = Rtree.Make (Rtree.Rectangle) (Line)
Inserting Values [ocaml-rtree-003]
- Patrick Ferris
There are two ways to insert values into the index -- either by inserting them one-by-one or by bulk loading them. The latter is the recommended approach where possible as the resulting layout of the R-Tree is much better.
# let r =
    let i = R.empty 4 in
    R.insert i Line.{ p0 = (1., 1.); p1 = (2., 2.) };;
val r : R.t = <abstr>
As you might expect, bulk loading takes a list of values instead.
# let r =
    let lines =
        Line.[
        { p0 = (0., 0.); p1 = (1., 1.) };
        { p0 = (1., 1.); p1 = (2., 2.) };
        { p0 = (2., 2.); p1 = (3., 3.) };
        { p0 = (3., 3.); p1 = (4., 4.) };
        ]
    in
    R.load ~max_node_load:4 lines;;
val r : R.t = <abstr>
Spatial Queries [ocaml-rtree-004]
- Patrick Ferris
The lines we loaded into the last index are really just four segments of the line y = x. Let's spatially query for the first two segments.
# R.find r (Rtree.Rectangle.v ~x0:0. ~y0:0. ~x1:2. ~y1:2.);;
- : Line.t list =
[{Line.p0 = (0., 0.); p1 = (1., 1.)}; {Line.p0 = (1., 1.); p1 = (2., 2.)};
 {Line.p0 = (2., 2.); p1 = (3., 3.)}]
You can see the query actually returned the first three, that's because all bound checks are inclusive.
The source repository includes a fairly simple example of rendering an R-Tree using Vg. This can be done outside of the repository using the tree representation.
# #show R.tree;;
val tree : R.t -> R.tree
type nonrec tree =
  R.tree =
    Node of (Line.envelope * R.tree) list
  | Leaf of (Line.envelope * Line.t) list
  | Empty
Here is an example rendering from the repository showing some random lines and the envelopes of the R-tree.

Patrick's OCaml Blog [ocaml-blog]
- Patrick Ferris
Welcome to the OCaml corner of my website. Here you will find long-form posts and shorter, more sporadic updates about my work in the OCaml community. This might include things about:
Outreachy where I am the current OCaml community co-ordinator.
Ppxlib where I help Nathan maintain the core library to build OCaml preprocessors.
Posts
These posts are longer form and consolidate weeklies (see below).
Modular Explicits in OCaml [modular-explicits]
- Patrick Ferris
Abstraction, in OCaml, often refers to hiding a particular type's implementation using a signature. For example:
module S : sig
  type t
  val add : t -> t -> t
end = struct
  type t = int
  let add = Int.add
end
In this post, however, I use abstraction to refer to the notion of code-reuse. Using features of the OCaml language to allow one piece of code to be used across different implementations or instantiations of a particular kind of value.
The goal of this post is to eventually discuss OCaml 5.5's modular explicits which is yet another feature that can allow a single piece of code to be used in various situations.
Polymorphism [abs-polymorphism]
- Patrick Ferris
The most prevalent kind of abstraction is polymorphism. For example, List.length will work for all lists regardless of what kind of elements the list contains. However, polymorphism requires you to keep the polymorphic part of the type at arm's length. This can lead to suboptimal performance and/or limited usefulness.
List.mem is a good example; in order to be polymorphic List.mem relies on Stdlib.(=), the polymorphic equality operator. In turn, this operator achieves its polymorphism by performing a structural comparison of the runtime representation of its arguments.
A common way to overcome this is to use higher-order functions (functions that take functions as arguments).
# let rec mem ?(eq=Stdlib.(=)) v = function
  | [] -> false
  | x :: xs -> eq v x || mem ~eq v xs
val mem : ?eq:('a -> 'a -> bool) -> 'a -> 'a list -> bool = <fun>
# let mem_int_list = mem ~eq:Int.equal
val mem_int_list : int -> int list -> bool = <fun>
This works well in plenty of cases (List.map, Hashtbl.iter, etc.), however, it doesn't scale well from a user's perspective if the body of the function requires lots of specific functions (e.g. compare, length, pp). At the same time, we want to avoid the precarious duck-typing of something like Python too.
Functors [abs-functors]
- Patrick Ferris
Functors are perhaps the second most prevalent feature of OCaml when it comes to code reuse. In the OCaml sense, a functor is a module that is parameterised by other modules. Set.Make is a functor that requires a module adhereing to the Set.OrderedType interface.
module IntSet = Set.Make (Int)
module StringSet = Set.Make (String)
Functors make it a lot easier to write implementations that depend on a large variety of functionality. Set.OrderedType is relatively tame in this sense, only needing a type t and a compare : t -> t -> int function.
Irmin, on the other hand, has functors that require users to provide Schemas. I have more thoughts about this API design in my Irmin retrospective.
It is important to consider the runtime costs of functors too. Whilst most of the time functors are instantiated at the toplevel, it does not come for free. You can have a play around with js_of_ocamlopt and see the generated output for how functors are applied.
First-class Modules and Existentials [abs-fcm-exist]
- Patrick Ferris
Sitting somewhere inbetween polymorphism and functors are first-class modules with existentials. This is a rather advanced use of OCaml's type system to be able to pack together a value of a particular type alongside a module that works with those kinds of values.
type set = Set : ((module Set.S with type t = 'a) * 'a) -> set
let size (Set ((module S), s)) = S.cardinal s
Packaging up integer sets is fairly straight-forward.
# let int_empty_set = Set ((module IntSet), IntSet.empty)
val int_empty_set : set = Set (<module>, <poly>)
From a user's perspective we are now closer to the realm of dynamic typing. Indeed, existentials are the way to do that in OCaml.
# type any = Any : 'a -> any
type any = Any : 'a -> any
# let any v = Any v
val any : 'a -> any = <fun>
Getting back into a typed world often involves some type witness gymnastics or runtime exceptions. Used sparingly, however, it can be very effective particularly when a user is none the wiser about the use of FCMs and existentials. I have made use of this trick to package together Irmin stores with implementations.
You could not, however, simply return the value that was packed away inside the existential.
# let woops (Set (_, s)) = s
Line 1, characters 26-27:
Error: The value s has type $a but an expression was expected of type 'a
       The type constructor $a would escape its scope
       Hint: $a is an existential type bound by the constructor Set.
There is also a runtime cost to the packing (and unpacking) of the module, not to mention the need for the extra allocation to create the existential in the first place. This will likely not be too significant, but is worth considering.
Modular Explicits [abs-modular-explicits]
- Patrick Ferris
OCaml 5.5 has module-dependent function types also known as modular explicits. The type of a function can now depend on types that come from a module that is also part of the function definition.
# let set_length : (module S : Set.S) -> S.t -> int =
  fun (module S) v -> S.cardinal v;;
val set_length : (module S : Set.S) -> S.t -> int = <fun>
# set_length (module IntSet) IntSet.empty;;
- : int = 0
# set_length (module StringSet) StringSet.empty;;
- : int = 0
In fact, we can now return values of a particular type that depends on a particular module!
# let empty_set : (module S : Set.S) -> S.t =
  fun (module S) -> S.empty;;
val empty_set : (module S : Set.S) -> S.t = <fun>
# empty_set (module IntSet);;
- : IntSet.t = <abstr>
# empty_set (module StringSet);;
- : StringSet.t = <abstr>
Or, we can dynamically select implementations and values.
# let with_impl :
    config:string -> ((module S : Set.S) -> S.t -> 'a) -> 'a =
  fun ~config fn ->
  match String.lowercase_ascii config with
  | "string" -> fn (module StringSet) StringSet.empty
  | "int" -> fn (module IntSet) IntSet.empty
  | c -> invalid_arg c
val with_impl : config:string -> ((module S : Set.S) -> S.t -> 'a) -> 'a =
  <fun>
This is like a more usable version of the FCM-existential trick, though does require more manual type annotations on functions. For instance, I tried switching out OBuilder's use of existentials with modular explicits:
-type builder = Builder : (module Obuilder.BUILDER with type t = 'a) * 'a -> builder
-
 let log tag msg =
   match tag with
   | `Heading -> Fmt.pr "%a@." Fmt.(styled (`Fg (`Hi `Blue)) string) msg
   | `Note -> Fmt.pr "%a@." Fmt.(styled (`Fg `Yellow) string) msg
   | `Output -> output_string stdout msg; flush stdout

-let create_builder store_spec conf =
+let create_builder :
+  Store_spec.store Lwt.t -> Native_sandbox.config ->
+    ((module B : Obuilder.BUILDER) -> B.t -> 'a) -> 'a Lwt.t =
+  fun store_spec conf fn ->
   store_spec >>= fun (Store_spec.Store ((module Store), store)) ->
   let module Builder = Obuilder.Builder (Store) (Native_sandbox) (Docker_extract) in
   Native_sandbox.create ~state_dir:(Store.state_dir store / "sandbox") conf >|= fun sandbox ->
   let builder = Builder.v ~store ~sandbox in
-  Builder ((module Builder), builder)
+  fn (module Builder) builder
I think the code is more pragmatic; there is no longer an indirection via a type called builder. The extra type annotations do add a little noise. Roll on modular implicits.
Irmin Retrospective [irmin-retro]
- August 7, 2025
- Patrick Ferris
Irmin is an OCaml library for building branchable and mergeable data stores. The data is mergeable in the sense of mergeable replicated data types.
I have been using Irmin for over five years to build different kinds of interesting data stores including:
Mentoring an intern who worked on Irmin in the browser.
Most recently, an Irmin-backed shell session manager.
I was asked to provide some feedback recently on Irmin, so I thought writing a little retrospective here would be a good way to do that. The remit for the retrospective was about improving Irmin, so the content is focussed on pain points and areas of improvement.
(* An in-memory Irmin store *)
module Store = Irmin_mem.KV.Make(Irmin.Contents.String)
What is Irmin?
- August 7, 2025
- Patrick Ferris
Irmin, at its simplest, is a key-value database. Users associate keys with values and can query and update these bindings.
Additionally, this database supports versioning. This means independent snapshots of the database can coexist and users can switch between them and update them without fear of interfering with other versions.
Different versions of the database can be combined by merging. When you set up your instance of an Irmin database, you also provide it with a merge function.
# #show_type Irmin.Merge.f;;
type nonrec 'a f =
    old:'a Irmin.Merge.promise ->
    'a -> 'a -> ('a, Irmin.Merge.conflict) result Lwt.t
Design and API
- August 7, 2025
- Patrick Ferris
Irmin's API is very git-inspired. There is a large overlap of shared vocabulary and concepts: repositories, branches, commits, heads etc.
Probably the most confusing aspect of this is the notion of a Store. When I was describing Irmin above, I used the term database to help distinguish between some of these concepts. In Irmin's documentation, it is used for multiple related (but different) concepts. In "Creating a Store" stores refer to the entire database, whereas in the Irmin API docs we have that:
There are two kinds of store in Irmin: the ones based on persistent named branches and the ones based temporary detached heads.
For Irmin library users, a Store.t can be thought of as a checkout of the database at a particular revision. This may be from a branch or a specific commit.
# Store.of_branch;;
- : Store.repo -> string -> Store.t Lwt.t = <fun>
# Store.of_commit;;
- : Store.commit -> Store.t Lwt.t = <fun>
The overloading of the term is confusing. I think it leaves users unsure about what other people might mean when they say "store". Being careful with these terms, and the contexts in which they are used, would help avoid this confusion.
Module and Functor Soup
- August 7, 2025
- Patrick Ferris
Undoubtedly for a majority of use-cases and users, Irmin is over-functorised. Nearly every module requires that you must apply some functor to access any useful code. In general, a user will have to interact with the Schema module when describing the types they want to instantiate their store with.
To counteract this, Irmin has plenty of KV modules that provide a Make functor that only requires a user to provide a suitable content module for their store (i.e. something that provides a type, a runtime representation of that type and a merge function).
# #show_module Irmin_mem.KV;;
module KV :
  sig
    type endpoint = unit
    type metadata = unit
    type hash
    type info = Store.info
    type ('h, _)contents_key = 'h
    type 'h node_key = 'h
    type 'h commit_key = 'h
    module Make : (C : Irmin__.Contents.S) ->sig ... end
  end
I think it is fair to say the documentation is hard to follow as it is a module and functor soup. For example, looking at irmin.3.11.0, starting at the toplevel documentation page our path to finding this paricular module and functor is as follows:
We jump into
Irmin_memfrom the nicely written landing page.We scroll down to find the KV module.
We now make sense of the module's signature by following the KV_maker link.
We see a
Make (C : Contents.S) : sig ... endat the end of the module, and we navigate through that.Finally we have come to our journey's end, and find the schema module with type constraints like
type Branch.t = string.
There is a big assumption there that you know what the Schema module is telling you and how it relates to your "store".
There is a counter-argument here, in that Irmin is incredibly flexible in terms of what you can use as types for your keys, branches, hashes etc. I was quite easily able to produce Irmin stores that use CIDs (self-describing content identifiers) for example.
I think there is a middle ground. For Irmin to be usable it needs to reduce the complexity of the API. The complexity is due to, in large part, over-functorisation. If the functors cannot be removed then perhaps better documentation or more introductory libraries like irmin-containers would be helpful. Perhaps a standalone library that acts as an interface to Irmin stores would be helpful. I find myself time and again implementing something like that.
Backends Galore
- August 7, 2025
- Patrick Ferris
Irmin has plenty of backends including a git-compatible one, a MirageOS backend, an in-browser IndexedDB backend and even a FoundationDB backend.
Irmin needs to have fewer, better tested backends. Of course, some of these are likely driven by funding and use-case specific details. However, I think by focusing on a few key backends and striving for solid performance but also strong consitency guarantees, Irmin would become a more viable candidate for potential users. I also believe the browser backend plays a key part to making this work in order to facilate local-first applications.
Syncing Remote Stores
- August 7, 2025
- Patrick Ferris
The synchronisation mechanisms in Irmin are powerful, but often the API is very confusing. For example, with the git-compatible Unix backend, nested deep in the documentation is the function required to create a remote endpoint. Once they have found this function, using it is not easy as it requires them to learn about the Mimic.ctx, which is an abstraction of the networking stack!
Do Fewer Things and Do Them Well
- August 7, 2025
- Patrick Ferris
Irmin is simultaneously a database that supports: content-addressing, merging, key-value lookup, branches, transactions, complete OS portability etc. I think, in short, it tries to do too many things and comes up short on some of them in ways that really matter.
When building the content-addressed database I needed strong guarantees about some atomic actions to perform on the underlying store. For example, setting the value and accessing the commit associated with it which was not possible with the API at that time in an atomic way. This kind of missing functionality is probably only understood after users stumble across it, but it also makes the library feel less focused and ready for production use-cases.
Documentation
- August 7, 2025
- Patrick Ferris
It will probably come as no surprise that one of the main limitations of using Irmin is the lack of documentation and tutorials. This is a particular pain point as the API is not very straightforward.
A while back, I started an Irmin book intending to help document the kinds of things real-world users would need in order to use Irmin in earnest. For example: ways to deal with type migrations or primers on runtime types. I still believe this sort of work would be invaluable, but there is a large cost to completing it, and it is not clear if there is enough interest in the project to warrant such an effort.
The tutorials on the irmin website are still good starting points for most new users. But they quickly lack the depth for real-world scenarios.
Feature Wishlist
- August 7, 2025
- Patrick Ferris
What follows are additional ideas for improving Irmin.
Heterogeneous Stores
- August 7, 2025
- Patrick Ferris
For all of [Irmin]'s abstraction and functorisation, there is a very clear missing feature for lots of first-time users of the library: you can only store values of a single type.
This leads to a few common workarounds:
Storing a serealised version of your values, essentially escaping the type-system and implementing a form of dynamic typing.
Growing your value to hold lots of different types via some large variant type.
Both of these options are feasible and have been used in practice. However, they are workarounds. A long time ago CraigFe created an RFC for heterogeneous stores, which I think about a lot. The main idea is to augment Irmin paths (keys) to be GADTs that carry type information about the kinds of values they access (similar to heterogeneuous variants of other data structures). Something like this alongside a simplified API would make Irmin more appealing as a library for persistent data storage.
Real-world Retrospectives
- August 7, 2025
- Patrick Ferris
This echos some thoughts from the Documentation section. There are some very real-world Irmin use-cases out there. For example, for a long time (I'm not sure if this is still the case) parts of the Tezos blockchain were using Irmin which uses the irmin-pack backend. Does this make irmin-pack the best tested backend and perhaps should be the default backend for new users? Or is it hyper-specific to the Tezos use case? There are blogs on tarides.com about the irmin-pack backend, but they might be outdated and should not be the first place to find advice on which Irmin backend to use.
Active Development and Engagement
- August 7, 2025
- Patrick Ferris
As far as I know, Irmin was at the forefront of technologies that have come to be described as local-first. There is a growing interest in this area (particularly as it acts as a counter-argument to an increasingly online, centralised model). I highly recommend reading Ink & Switch's essay on the matter. And it would be great to see more research via Irmin at things like the lofi unconference and the PLF workshop at SPLASH 2023!
Thank you for reading! And thank you to all the Irmin contributors. I hope this might be useful in the future for building the next-generation Irmin!
Slipshow x x-ocaml [slipshow-x-xocaml]
- July 23, 2025
A short, explanatory post about combining two very fun pieces of work in OCaml.
Paul-Elliot has been building Slipshow for some time now where slides are slips and your presentations run vertically. More recently, Arthur has built x-ocaml, a web component library for executable OCaml cells embedded into OCaml.
Using xocmd, a small tool I built for translating markdown codeblocks to x-ocaml components, your Slipshow's can now be executable!
xocmd learn-effects.md | slipshow compile - > learn-effects.html
Take a look at an example! (or the source markdown).
I really like this light-weight approach to building interactive presentations for explaining things in OCaml (e.g. over running a jupyter notebook server).
Quarterly OCaml Q2 [ocaml-quarterly-q2]
- July 18, 2025
- Patrick Ferris
Thanks to Tarides sponsorship, I get to work on open-source OCaml. This quarterly is a companion to my weeklies, summarising the last three months of development, peppered with ideas and thoughts about OCaml, its community and its future.
What I wanted to work on?
- July 18, 2025
- Patrick Ferris
There were two main things I hoped to continue working on: ppxlib and outreachy. These are projects that I was previously working on, and in the case of Outreachy I have now been involved for many years.
In addition to this, all of my Part II projects this year used OCaml in some regard. In general, I want to see more adoption of OCaml. Over the years this has taken many forms including my initial work on developing workflows for OCaml that just turned five years old. This directly fed into the rebranding and rethinking of ocaml.org itself.
What I worked on?
- July 18, 2025
- Patrick Ferris
Ppxlib
- July 18, 2025
- Patrick Ferris
Ppxlib is the de facto standard library for building OCaml preprocessors. At the time of writing, opam list --depends-on=ppxlib informs me that there are 267 reverse dependencies. Janestreet is a heavy user of ppxes and has authored many.
One of the main accomplishments this quarter was bumping the internal AST to 5.2. This allows ppx authors to use new OCaml language features in their ppxes. In bumping the AST, we knowingly broke compatability for pretty much every single reverse dependency. As best we can, we have been sending patches to ppx libraries and helping users migrate to the latest ppxlib.
There is an interesting dicussion to had about the nature of open-source, and its interaction with industrial monorepos and community tended package repositories. Package ecosystems thrive whenever there is a dedicated community creating, maintaining and publishing packages. The idea is that the published world should be healthy. The publishing medium can act as natural limiting factor in the churn of breaking changes (in the case of OCaml this is via PRs to the opam-repository). This, I have come to notice, reacts poorly to changes coming from internally consistent monorepos where introducing breaking changes is easily fixed by applying patches there and then. Whatsmore, OCaml is often stated as an incredibly safe language to perform large refactorings thanks to its type system.
Ppxlib sits awkwardly in the space of possible breaking changes. Tied to OCaml's parsetree, impacts of changes there ripple down to ppxlib. The compiler itself can remain internally consistent, and is protected as it need only parse source code. Ppxlib, on the other hand, exposes the parsetree to users and thus any changes to the parsetree will likely be felt by ppx authors. Since I started working on ppxlib, it feels as though the number of syntax changes has gone up (primarily from Janestreet work). Unless we make changes to how we provide support for these, maintainers of ppxlib will forever be stuck doing busy work! Thankfully, Nathan has thoughts on how to improve this.
There are a slew of other features I have added to ppxlib including:
Support for deriving from classes.
Support for deriving from module bindings and signatures.
Fixing compiler and ppxlib dummy locations.
Bumping to 5.3.
Migrations for 5.4.
Outreachy
- July 18, 2025
- Patrick Ferris
Our two projects this year, one on claudius and one on dune, are going extremely well. At the time of writing, we just had a mid-internship call to catch up, and I was blown away by the progress each intern has made. Unfortunately, Outreachy is struggling with funding and the next round is perhaps not going to happen. This is a real shame and I am hoping that it will not be the case.
Outreachy has been a wonderful source of new, committed OCaml developers. If you haven't already, do peruse the webpage on OCaml.org to see past internships or watch the demo day presentations. For the mentors involved, I believe it has also been a rewarding experience (though at times a challenging one). We are always looking for new mentors and project ideas, please do reach out to me if you are interested.
Hazel
- July 18, 2025
- Patrick Ferris
OCaml's feature set allows it to shine at writing programming languages (and things of that ilk: compilers, interpretters, static analysis tools). Hazel is a research programming language with typed holes written completely in OCaml (via the reason dialect).
Relating this back to the original intent of my work, to improve OCaml adoption, I believe this also means keeping existing users happy. In the last quarter I developed a compiler from OCaml to Hazel. Whilst new features are still being added to Hazel, I hope this could serve as a tool to help develop test-suites and standard library functions using existing OCaml solutions. In a student's work (Typed Debugging for Hazel), we used this tool to build a corpus of ill-typed Hazel programs to great effect.
OCaml should continue to be a world-class programming language for building other programming languages. I hope to upstream some of this work to Hazel and provide some low effort maintenance to help keep their compiler in good shape.
Systems Programming in OCaml
- July 18, 2025
- Patrick Ferris
In a cross-over with my own research, I have been developing many tools related to systems programming in OCaml including:
An eBPF-based
opensyscall tracing tool.A library in OCaml for spawning void processes.
A shell session manager that uses Irmin to manage sessions. It is nice to see a new push to finally land the direct-style Irmin PR!
This work is means to develop the underlying libraries that support it. For example, I have opened a few PRs to Eio to add new "fork actions" to the spawn API. I also investigated the feasibility of changing the underlying mechanisms in Eio to use Picos. In the future, I think this could be important avoid further splitting the OCaml ecosystem.
OxCaml
- July 18, 2025
- Patrick Ferris
I dabbled a little with OxCaml and build try-oxcaml to let people take it for a spin without having to perform opam repository gymnastics. It turned into a lot of work to track down some pretty inane bugs (type definitions differeing between js_of_ocaml and the OxCaml compiler, resulting in different Javascript runtime representations...).
This unblocked a few of my colleagues to get OxCaml working on tools like odoc_notebooks and x-ocaml.
Forester
- July 18, 2025
- Patrick Ferris
A good proportion of my work this quarter has been focused on how to present the very work that I am doing. Jon Sterling has been developing a tool for scientific thought called Forester which seemed like a possible candidate for writing and sharing my work.
Porting my existing blog posts and website content from markdown to Forester's LaTeX-inspired syntax didn't seem like an option. In particular, many of my posts made use of additional markdown-based tools (like ocaml-mdx).
This lead to the development of Graft: a preprocessor for Forester forests, converting markdown and bibtex to trees.
What's next?
- July 18, 2025
- Patrick Ferris
So, I worked on most of what I wanted to work on and then some! Going forward I hope to keep maintaining ppxlib in some capacity and coordinating the OCaml community's Outreachy efforts.
I hope to continue my small experiments (e.g. converting Eio to Picos). My own research makes heavy use of Irmin, and I would be interested to help with that too. More recently, a new library has been released for working with numerical data in OCaml called Raven: I am interested to use this library in Geocaml, a suite of geospatial tools written in OCaml that I maintain.
I feel conflicted about the OxCaml efforts. I admit, I am not fully aware of the full benefits of the features, but I worry about some proliferation of modes that make the type system in OCaml unbearable to use. On top of this, with my ppxlib hat on, I worry about the impact of changing the compiler so frequently, placing strain on an already small community. That being said, by releasing OxCaml separately I do believe running it as an experimental set of packages will help understand the tool better. But I would not be building anything I intend to maintain or research with right now as that ecosystem is far too volatile.
Finally, over the past two years I have done a lot of teaching. From Part II projects to supervisions. Going into next (academic) year, I intend to reduce my in-person teaching to focus on my research. However, I am interested in producing more materials for learning, maybe some of this in OCaml, perhaps something similar to Beautiful Racket. I have tried in the past to do these sorts of things, for example The Irmin Book.
Thank you
- July 18, 2025
- Patrick Ferris
Thank you for reading this wrap up! And thank you again to Tarides for letting me work so freely on things that I think are good for the OCaml community.
Opentrace [open-trace]
- May 19, 2025
- Patrick Ferris
- https://tangled.sh/@patrick.sirref.org/opentrace
Thanks to Koonwen's excellent libbpf bindings in OCaml, I have been building a little tool called opentrace to make it easier to track an executable's inputs and outputs.
This work was inspired my Michael's self-proclaimed "gross hack": pyshark. Whilst pyshark achieves its goals by injecting code into commonly used python objects and methods, opentrace uses eBPF. By using a lower-level API (hooks in the kernel), opentrace can remain programming language agnostic. However, less information is none about the user's intent compared to something like pyshark.
Monitoring the System
- May 19, 2025
- Patrick Ferris
opentrace has an all command that will trace the entire system.
$ sudo opentrace all --flags=O_WRONLY
pid,cgid,comm,kind,flags,mode,filename,return
16324,4417,".nheko-wrapped",openat,577,438,"/home/patrick/.cache/nheko/nheko/curl_alt_svc_cache.txt",47
16324,4417,".nheko-wrapped",openat,193,33188,"/home/patrick/.cache/nheko/nheko/cr3ZUHqBErIOe3PlwJ1SuU8zFKKxL12VzrRoHYMH.tmp",47
16324,4417,".nheko-wrapped",openat,577,438,"/home/patrick/.cache/nheko/nheko/curl_alt_svc_cache.txt",47
16324,4417,".nheko-wrapped",openat,193,33188,"/home/patrick/.cache/nheko/nheko/QfZTdZSuC56NdcDQ3aMxJc3BhMhAj8PmtYW1zFDP.tmp",47
2530,4235,"systemd",openat,524865,438,"/sys/fs/cgroup/user.slice/user-1000.slice/user@1000.service/app.slice/gammastep.service/cgroup.subtree_control",41
2530,4235,"systemd",openat,524545,0,"/sys/fs/cgroup/user.slice/user-1000.slice/user@1000.service/app.slice/gammastep.service/memory.min",41
2530,4235,"systemd",openat,524545,0,"/sys/fs/cgroup/user.slice/user-1000.slice/user@1000.service/app.slice/gammastep.service/memory.low",41
2530,4235,"systemd",openat,524545,0,"/sys/fs/cgroup/user.slice/user-1000.slice/user@1000.service/app.slice/gammastep.service/memory.high",41
2530,4235,"systemd",openat,524545,0,"/sys/fs/cgroup/user.slice/user-1000.slice/user@1000.service/app.slice/gammastep.service/memory.max",41
The --flags=O_WRONLY argument filters the events where the O_WRONLY flag was set in the call to open.
We also get the name of the current executable linked to the task (comm). The -wrapped is an artefact of using Nix.
Tracing an Executable
- May 19, 2025
- Patrick Ferris
The primary use case for this tool is to inspect what files your program might be reading and writing.
$ sudo opentrace exec --format=json --flags=O_CREAT -- opam list
$ cat trace.json | jq ".[] | .fname"
"/home/patrick/.opam/cshell/.opam-switch/packages/cache"
"/home/patrick/.opam/log/log-118747-29da3d.out"
"/home/patrick/.opam/log/log-118747-29da3d.err"
"/home/patrick/.opam/log/log-118747-29da3d.env"
"/home/patrick/.opam/log/log-118747-29da3d.info"
The "flags" argument can specify a small boolean formula for checking the open flags of a particular event with | (or), & (and), and ~ (not). Parentheses can be used for precedence.
$ sudo opentrace exec --flags="O_WRONLY|O_RDONLY" -- ocaml --version
Spawning Subprocesses
- May 19, 2025
- Patrick Ferris
One feature opentrace needs (in this proof-of-concept phase) is the ability to also trace subprocesses.
opentrace is primarily an eBPF program that is loaded into the kernel and communicates with an OCaml program. Events are communicated via a ring buffer and most of the post-processing happens in OCaml. To capture subprocesses, opentrace creates a new control group (cgroup) and places the new process into that group. This gives opentrace a new identifier to track, namely the cgroup.
So consider the following program.
let () =
  Eio_posix.run @@ fun env ->
  Eio.Path.(save ~create:(`Or_truncate 0o664) (env#fs / "hello.txt") "hello");
  Eio.Process.run env#process_mgr
    [ "/bin/bash"; "-c"; "echo 'heya' > heya.txt" ]
It first creates a file using direct calls to functions like openat. Then it spawns a process which creates a new file called heya.txt. This happens in a separate process. However, with the --cgroups flag we can capture both interactions with the operating system.
$ sudo opentrace exec --cgroups --flags="O_CREAT|O_TRUNC" ./main.exe
pid,cgid,comm,kind,flags,mode,filename,return
153187,530807,"main.exe",openat,526914,436,"hello.txt",5
153192,530807,"bash",openat,577,438,"heya.txt",3
Eio's Process API
- May 19, 2025
- Patrick Ferris
I have used the Eio_unix fork action process API to be able to extend what happens in the child process. Loading most eBPF programs into the kernel requires special privileges hence the need for sudo. When a user requests for a particular program to be executed and traced, opentrace spawns a process via the Eio Process API. Opentrace defines a few new so-called "fork actions", little fragments of C code that are run after the call to fork (clone). Most likely this ends with a call to execve, but other calls are possible for example setuid allowing opentrace to change the user of the child process so it does not run as root. Similarly, this is where (if used) we create the cgroup and place the process into that group.
Limitations: Io_uring
- May 19, 2025
- Patrick Ferris
Whilst testing opentrace against some of the tools I use nearly daily, I noticed some events were being missed. I tried tracing forester, and only the initial read of forest.toml was logged. It dawned on me that the reason for this was that forester (via eio) was using io_uring to perform most of the IO. Most attempts to open files were bypassing the open system calls, and instead they were being performed by the kernel after reading a submission request for an openat2-style call!
This is not news to seasoned, Linux systems programmers. Io_uring bypasses SECCOMP filters for exactly the same reasons.
$ sudo opentrace exec -- forester build
$ cat trace.csv
pid,cgid,comm,kind,flags,mode,filename,return
155007,535570,"forester",openat,524288,0,"forest.toml",5
155007,535570,"forester",Uring,2621440,0,"",0
155021,535570,"cp",openat,131072,0,"/home/patrick/documents/forest/theme/favicon-32x32.png",4
155007,535570,"forester",Uring,2686976,0,"",0
155007,535570,"iou-wrk-155007",Uring,557634,420,"",0
155007,535570,"iou-wrk-155007",Uring,557634,420,"",0
155007,535570,"iou-wrk-155007",Uring,557634,420,"",0
It is interesting to note two things here:
We can tell that forester reads the configuration file probably using something like
In_channelin OCaml (it does).It appears that Uring is performing IO in both worker threads and directly.
The file paths are empty at the moment as I cannot find a clean way to trace openat submission requests into Uring without it sometimes going very wrong. I have tried quite a few methods (e.g. tracing do_filp_open) and at the moment I am tracing io_openat2, but this seems quite brittle, and often the filename is completely garbled, so I do not set it. If anyone has any ideas to trace Io_uring more reliably, I am all ears!
Try OxCaml [try-oxcaml]
- May 9, 2025
- Patrick Ferris
- https://patrick.sirref.org/oxcaml
This week, I have been trying out Janestreet's Oxidised OCaml (see their ICFP paper). This adds a system of modes to OCaml for expressing things like locality.
...we’re introducing a system of modes, which track properties like the locality and uniqueness of OCaml values. Modes allow the compiler to emit better, lower-allocation code, empower users to write safer APIs, and with the advent of multicore, statically guarantee data race freedom—all in a lightweight way that only affects those in need.
For example, you might say:
let is_empty (s : string @@ local) =
  String.length s = 0
To get a feel for how this changes the language, you can follow their instructions on their custom opam-repository. Alternatively, you can give it a go in your browser! This is a full toplevel running with Base installed (which has plenty of OxCaml annotations on Stdlib-like functions).
Happy OxCamling!
A Transpiler from OCaml to Hazel [hazel-of-ocaml]
- May 2, 2025
- Patrick Ferris
Over the past few months, I have been piecing together a transpiler from Hazel to OCaml. This is, in part, to help one of my third-year undergraduate students who is working on type error debugging in Hazel.
Typed Holes
- May 2, 2025
- Patrick Ferris
Hazel is a functional programming language with typed holes. Holes are pieces of your program that have not yet been filled in. Holes can appear anywhere in your program both as expression or types. Hazel can still evaluate your program in the presence of holes.
To get a flavour of Hazel, take a regular map function for lists.
let map = fun f -> fun xs -> case xs
  | [] => []
  | x :: xs => f (x) :: map(f)(xs)
end in
map(fun x -> ?)([1, 2, 3])
The question mark (?) is a hole. The program evaluates to the following expression of type [?] (for people more familiar with OCaml types ? list).
[ ?, ?, ? ]
Hazel supports local type inference but nothing involving unification variables. For example, a simple add_one function in Hazel (fun x -> x + 1) has type ? -> Int.
From OCaml to Hazel
- May 2, 2025
- Patrick Ferris
The ability to transpile OCaml programs to Hazel programs is motivated by one simple thought: there are more OCaml programs than there are Hazel programs. This could help bootstrap projects by alleviating the need to rewrite boilerplate code (e.g. URI parsing or standard library functions for strings).
A Transformation of Syntax
- May 2, 2025
- Patrick Ferris
Hazel markets itself as an "Elm/ML-like functional programming language". From the previous example of map, it should be apparent just how close to OCaml the language is.
It turns out that a majority of the transpiler is a transformation of syntax. Take a simple ADT for an arithmetic programming language.
type expr =
  | Float of float
  | Add of expr * expr
  | Sub of expr * expr
  | Mul of expr * expr
  | Div of expr * expr
And when we run hazel_of_ocaml over this OCaml type declaration.
type expr =
  + Float(Float)
  + Add((expr, expr))
  + Sub((expr, expr))
  + Mul((expr, expr))
  + Div((expr, expr))
 in ?
Not much has changed expect some syntax. Hazel does not have a notion of top-level expression so hazel_of_ocaml wraps the program into one set of value bindings. For the most part, Hazel acts as a subset of the pure, functional part of OCaml. At the time of writing, this subset is fairly limited with no support for modules or labelled records out of the box (there are plenty of development branches with these features).
If we try out the same map function but written in OCaml and transpiled to Hazel we get.
let rec map f = function
  | [] -> []
  | x :: xs -> f x :: map f xs
Which becomes the following hazel program.
let map = fun f -> fun x1 -> case x1
  | [] => []
  | x :: xs => f(x) :: map(f)(xs)
end in ?
We could have a field day discussing the syntax of OCaml and Hazel (parentheses for function arguments, well-scoped cases for pattern-matching, a different arrow for pattern-matching etc.). What would be more interesting is taking a look at how to handle polymorphism in Hazel.
Explicit Polymorphism
- May 2, 2025
- Patrick Ferris
Hazel has explicit polymorphism. So far, we have not seen it as we have let the types have holes in them. The map function in OCaml has the following type.
val map :
  ('a -> 'b) -> 'a list -> 'b list
We must remind ourselves (by reading Craig's excellent blogpost on the matter) that in OCaml
... type variables in signatures are implicitly universally-quantified
So in reality, we have that map has the following type.
val map : ∀ a b. (a -> b) -> a list -> b list
In Hazel, we have to explicitly type our map function to be polymorphic. Not only does this mean the type annotation requires universally quantified type variables, but we must also perform type application wherever we choose to apply the map function (whether that be recursively or somewhere later in our program).
let map : forall a -> forall b -> (a -> b) -> [a] -> [b] =
  typfun a -> typfun b -> fun f -> fun xs -> case xs
    | [] => []
    | x :: xs => f (x) :: map@<a>@<b>(f)(xs)
end in
map@<Int>@<Int>(fun x -> ?)([1, 2, 3])
forall introduces a universally quantified type variable into our type annotation, and typfun introduces it into the function itself (à la System F). Type application requires @<T> where T is some type. This allows hazel to quite easily support higher rank polymorphism, but we will not worry too much about that.
Propagating OCaml Types into Hazel
- May 2, 2025
- Patrick Ferris
Most often, OCaml users interact with prenex polymorphism (rank-1) where the universal quantifiers are at the front of the type. OCaml does support quantifiers inside certain types like records.
What this means for the transpiler is that we can reuse OCaml's type inference to safely instantiate the correct type annotations and type applications in Hazel! To do this, hazel_of_ocaml uses Merlin to inspect the type of the function in either a value binding or at the point of a function application.
Take a simple, polymorphic length function.
let rec length = function
 | [] -> 0
 | _ :: xs -> 1 + length xs

let int_len = length [ 1; 2; 3 ]
let str_len = length [ "only"; "two" ]
When we run this through hazel_of_ocaml with the -type flag we get.
let length : forall a -> [a] -> Int = typfun a -> fun x1 -> case x1
  | [] => 0
  | _ :: xs => 1 + length@<a>(xs)
end in
let int_len : Int = length@<Int>(1 :: 2 :: [3]) in
let str_len : Int = length@<String>("only" :: ["two"])
in ?
hazel_of_ocaml has correctly instantiated the type for length inside the recursive function and then in each case with the integer list and the string list.
A Corpus of Hazel Programs
- May 2, 2025
- Patrick Ferris
The impetus for this work was to derive a corpus of ill-typed Hazel programs. Luckily, such a corpus exists for OCaml! Seidel et al. created a corpus of OCaml programs from their undergraduate students at UC San Diego. Some of these programs have been transpiled to Hazel.
Future Work
- May 2, 2025
- Patrick Ferris
Hazel is a fun, research programming language. Potential third-year students may find it interesting to take this work further. For example, how would this look in terms of a module system? From a purely engineering perspective, plenty of work would be needed to convert a multi-library OCaml project to Hazel (e.g. handling the cmi files).
Another line of research would be to have Hazel target one of the intermediate representations in OCaml which would give Hazel a fully functioning compiler to "native" code?
Bumping Ppxlib's AST to 5.2 [ppxlib-5-2]
- February 18, 2025
Ppxlib is a libary for building OCaml preprocessors. Users can generate OCaml code from OCaml code (derivers) or replace parts of OCaml code with other OCaml code (rewriters).
At the core of ppxlib is the OCaml parsetree; a data structure in the compiler that represents OCaml source code. Ppxlib makes a distinction between the source parsetree (based on the version of the OCaml compiler you are using) and ppxlib's parsetree (a copy of some parsetree from the compiler).
In ppxlib.0.36.0, the internal AST was bumped from the AST of OCaml 4.14.0, to the AST of OCaml 5.2.0. This post discusses some of the internal mechanisms that allows ppxlib to support multiple compilers and how this bump broke a lot of backwards compatibility.
Manual Migrations in Ppxlib
- February 18, 2025
It is possible to perform migrations between parsetrees manually using the ppxlib.ast package.
open Ppxlib
open Ast_builder.Make(struct let loc = Location.none end)
let pp_expr = Format.printf "%a%!" Pp_ast.(expression ?config:None)

let loc = Location.none
let str txt = { txt; loc }

module To_408 =
  Ppxlib_ast.Convert (Ppxlib_ast.Js) (Ppxlib_ast__.Versions.OCaml_408)
The Ppxlib_ast.Js module is ppxlib's AST (since ppxlib.0.36.0 OCaml 5.2.0). We can use functions provided by the Convert functor to copy parts of the AST from one version to another. Usually there is very little difference between the versioned parsetrees.
let func arg body =
  pexp_fun Nolabel None (ppat_var (str arg)) body

let add_expr = func "x" (func "y" (eapply (evar "Int.add") [ evar "x"; evar "y" ]))
The above excerpt of OCaml code produces an expression in the language. More accurately, a function that has two arguments. If we print the simplified AST we can see that the arguments are stored together in a list.
# pp_expr add_expr;;
Pexp_function
  ( [ { pparam_loc = __loc
      ; pparam_desc = Pparam_val ( Nolabel, None, Ppat_var "x")
      }
    ; { pparam_loc = __loc
      ; pparam_desc = Pparam_val ( Nolabel, None, Ppat_var "y")
      }
    ]
  , None
  , Pfunction_body
      (Pexp_apply
         ( Pexp_ident (Ldot ( Lident "Int", "add"))
         , [ ( Nolabel, Pexp_ident (Lident "x"))
           ; ( Nolabel, Pexp_ident (Lident "y"))
           ]
         ))
  )
- : unit = ()
This is a relatively new feature of the parsetree, if we migrate the expression down to 4.08 we see it is represented differently. The output is a little too verbose to be readable, and there's no good way to show the AST, so you will just have to take my word.
let expr_408 = To_408.copy_expression add_expr
Function Arity in the OCaml Parsetree
- February 18, 2025
OCaml 5.2 introduced a new way to represent functions. Before 5.2, all functions were represented with single arity. Functions with multiple arguments would return functions as their body. For example:
let add x y = x + y
A two-argument add function would be represented in the parsetree as fun x -> fun y -> x + y. Using the nodes from the parsetree (with some details removed) it would be Pexp_fun (x, Pexp_fun (y, Pexp_apply ...)).
Now, since OCaml 5.2, functions can be expressed with their syntactic arity intact. The function add would look something like Pexp_function ([ x; y ], Pfunction_body (Pexp_apply ...)). Both arguments are stored as a list.
The constructor Pexp_function was not a new addition to the parsetree. It used to represent pattern-matching expressions like function A -> 1. This can now be expressed as a function body of Pfunction_cases.
Whilst these additions and modifications to the parsetree are arguably a better design, it has caused chaos in terms of ppxlib's reverse dependencies!
Coalescing Function Arguments
- February 18, 2025
In ppxlib 0.36.0, functions from Ast_builder will help ppx authors produce maximum arity functions. However, functions from Ast_helper will not do this.
let ast_helper_func arg body =
  Ast_helper.Exp.fun_ Nolabel None (ppat_var (str arg)) body

let ast_helper_expr = ast_helper_func "x" (ast_helper_func "y" (eapply (evar "Int.equal") [ evar "x"; evar "y" ]))
Here we recreate our helper function to create function expressions using Ast_helper.Exp.fun_ instead. We can now show the difference between the expr expression and the ast_helper_expr expression.
# pp_expr add_expr;;
Pexp_function
  ( [ { pparam_loc = __loc
      ; pparam_desc = Pparam_val ( Nolabel, None, Ppat_var "x")
      }
    ; { pparam_loc = __loc
      ; pparam_desc = Pparam_val ( Nolabel, None, Ppat_var "y")
      }
    ]
  , None
  , Pfunction_body
      (Pexp_apply
         ( Pexp_ident (Ldot ( Lident "Int", "add"))
         , [ ( Nolabel, Pexp_ident (Lident "x"))
           ; ( Nolabel, Pexp_ident (Lident "y"))
           ]
         ))
  )
- : unit = ()
Above, we see a function expression with arity two. Below, we see nested function expressions each with arity one.
# pp_expr ast_helper_expr;;
Pexp_function
  ( [ { pparam_loc = __loc
      ; pparam_desc = Pparam_val ( Nolabel, None, Ppat_var "x")
      }
    ]
  , None
  , Pfunction_body
      (Pexp_function
         ( [ { pparam_loc = __loc
             ; pparam_desc = Pparam_val ( Nolabel, None, Ppat_var "y")
             }
           ]
         , None
         , Pfunction_body
             (Pexp_apply
                ( Pexp_ident (Ldot ( Lident "Int", "equal"))
                , [ ( Nolabel, Pexp_ident (Lident "x"))
                  ; ( Nolabel, Pexp_ident (Lident "y"))
                  ]
                ))
         ))
  )
- : unit = ()
Ramifications for Ppxlib Users
- February 18, 2025
Many, many, many ppxes broke after migrating the ppxlib AST to 5.2. Mostly, this is due to pattern-matching. Downstream users of ppxlib frequently pattern-match directly against the parsetree. However, nodes such as Pexp_fun no longer exist and Pexp_function has completely different constructor arguments!
Patching all the ppxes has been quite difficult. Most ppxes only deal with single arguments at a time (e.g. Pexp_fun x) but now they must handle zero or more arguments at a time. (In the zero case, this will always correspond to a pattern-matching function).
Here is a non-exhaustive list of some of the ppxes that have been patched. It may useful for other ppx authors who wish to upgrade to ppxlib.0.36.0:
https://gitlab.com/o-labs/ppx_deriving_jsoo/-/merge_requests/1
https://gitlab.com/gopiandcode/ppx-inline-alcotest/-/merge_requests/3
https://gitlab.com/o-labs/ppx_deriving_encoding/-/merge_requests/4
This release has emphasised the tension between using pattern-matching on algebraic datatypes and wanting to reduce downstream breakages (e.g. using abstract datatypes). This tension is not new.
The Future of Ppxlib
- February 18, 2025
Ppxlib is not going anywhere anytime soon. We have committed to trying to keep the internal AST up to date with the latest OCaml release. In fact, there is already a PR for the 5.3 bump!
There have been many discussions about simplifying this process, but so far the time and effort to build a ppxlib that will result in fewer breakages is too high (see an attempt using views).
Thank you to Tarides and Jane Street for funding my time to work on this release and all the chaos it has caused.
Happy preprocessing!
Defunctorising VPNKit [vpnkit-upgrade]
- February 28, 2025
VPNKit is a core part of the Docker for Mac/Windows stack. It is tasked with translating network activity from the host to the Linux container.
This short post discusses some of the recent changes to MirageOS and how they impact VPNKit.
Dune Virtual Libraries [dune-virt-libs]
Dune, for quite some time, has supported virtual libraries. This allows library authors to define a signature without an implementation (similar to OCaml's module type S = struct ... end). The package is something other dune libraries can build against, still without choosing a particular implementation of the interface. An application author can make the decision about which implementation they would like to build into their program.
This feature has been quite widely used in OCaml. For example, the excellent digestif library of hashing algorithms provides both C and OCaml implementations individually packaged into digestif.c and digestif.ocaml respectively. Consider developing a browser application that needs some hashing algorithm (e.g. Irmin in the browser). We can explicitly use the OCaml backend for digestif which js_of_ocaml will happily compile for us.
There are two distinct limitations to this approach.
Applications can only link exactly one implementation.
Implementations cannot expose additional functionality easily (see dune#5597).
Functors in MirageOS
- February 28, 2025
MirageOS is a framework for building unikernels in OCaml. It relies heavily on OCaml's functors to abstract implementation from interface. The mirage tool will then select appropriate instantiations of these functors depending on the backend that is targeted (e.g. unix, hvt etc.)
Recently, there has been a push to use dune virtual libraries instead.
VPNKit's Fake Clock & Time
- February 28, 2025
We need to be able to overcome the limitation that implementations cannot expose additional functionality very easily using dune virtual libraries. As it stands, we need to make Mirage's virtual libraries unwrapped (i.e. set (wrapped false)). This allows implementers to expose additional modules alongside the implementation of the virtual library.
For VPNkit, we need this to port some of the DNS forwarding tests which use a fake clock and sleep module. Previously, they could be provided directly as functor arguments to the various DNS modules e.g.
let module R =
  Dns_forward.Resolver.Make(Proto_client)(Fake.Time)(Fake.Clock)
In this new world of dune virtual libraries, our Resolver is significantly more simple.
let module R = Dns_forward.Resolver.Make(Proto_client)
The flexibility of time and clock implementation has been pushed to a build-time decision in a dune file. This means that in order to provide the same fake clock and time we will need to create a private dune library that (a) implements the respective signatures of the virtual libraries and (b) provides the extended interface to allow the test suite to modify the internals of the implementations.
The first thing I had to do was make the mirage-mtime and mirage-sleep virtual libraries unwrapped. This allowed me to make a new private dune library called fake_time with two public modules: the normal interface required by mirage-mtime and another module called Fake_time_state containing:
let timeofday = ref 0L
let c = Lwt_condition.create ()

let advance nsecs =
  timeofday := Int64.add !timeofday nsecs;
  Lwt_condition.broadcast c ()

let reset () =
  timeofday := 0L;
  Lwt_condition.broadcast c ()
I did the same for fake_sleep which depended on the state from the fake_time library (something a normal library wouldn't).
Once I had the implementations for the virtual libraries in place, all that remained was to tell the executable (in this case the test suite) to select these new implementations instead of the defaults. Whereas before, all the tests could live in the same test suite, now they had to be split into those that needed the fake implementation and those that did not. This is another slight limitation of this virtual library approach. You can only link one implementation at a time to an executable (or test). Thus, the dune rules for running the dns_forward test suite became:
; Uses the default  implementations provided by virtual libraries
(executable
 (name test)
 (libraries dns_forward alcotest))

; Override the defaults and select the private fake libraries
(executable
  (name test_fake)
  (libraries dns_forward alcotest fake_sleep fake_time))
With all of this machinery in place, I could now update test_fake to use the new modules that would provide the custom functionality for the clock and time implementations.
(* The bad server should be marked offline and no-one will wait for it *)
Fake_time_state.reset ();
(* avoid the timeouts winning the race with the actual result *)
Fake_time_state.advance Duration.(of_ms 500);
Conclusion
- February 28, 2025
The switch to dune virtual libraries seems to be a good one. A majority of applications only require a single clock or time implementation. However, it has become harder to inject custom implementations of various resources into your MirageOS-based applications.
Reviving OCaml R-Tree [ocaml-rtree]
- August 9, 2023
- Patrick Ferris
Antonin Guttman first proposed R-Trees in 1984.
In order to handle spatial data efficiently, as required in computer aided design and geo-data applications, a database system needs an index mechanism that will help it retrieve data items quickly according to their spatial locations...
There are lots of excellent resources for understanding more about R-Trees and all of the wonderful variations there of (e.g. R*-trees). This blog post seems to be the most popular introduction.
An OCaml Rtree Implementation [ocaml-rtree-001]
- Patrick Ferris
In the Energy and Environment Group we are working on various geospatial tools, one of which is written in OCaml and needed a geospatial index to speedup spatial queries over a dataset. Searching Github revealed an implementation in pure OCaml. After reaching out to the author, they were more than happy for their work to be maintained in the Geocaml organisation, updated to the latest OCaml tools and hopefully released on opam.
The dunification went smoothly whilst fast-forwarding 15 OCaml compiler versions with no changes or problems (just dune unused variable warnings).
OCaml Rtree Examples [ocaml-rtree-002]
- Patrick Ferris
An R-Tree in OCaml is created from an envelope (the kind of bounding box) and a value (for storing in the tree). The value depends on the envelope as you have to provide a function to calculate an envelope from a value. Here is one way we might define a line using the provided two-dimensional Rectangle envelope.
module Line = struct
  type t =
    { p0 : float * float; p1 : float * float }

  let t =
    let open Repr in
    record "line" (fun p0 p1 -> { p0; p1 })
    |+ field "p0" (pair float float) (fun t -> t.p0)
    |+ field "p1" (pair float float) (fun t -> t.p1)
    |> sealr

  type envelope = Rtree.Rectangle.t

  let envelope { p0 = (x1, y1); p1 = (x2, y2) } =
    let x0 = Float.min x1 x2 in
    let x1 = Float.max x1 x2 in
    let y0 = Float.min y1 y2 in
    let y1 = Float.max y1 y2 in
    Rtree.Rectangle.v ~x0 ~y0 ~x1 ~y1
end
In addition to the envelope function, we also need to provide a runtime representation using Repr. In the example, we've constructed it by hand but I recommend using ppx_repr to derive it for you. From here we can create our index.
module R = Rtree.Make (Rtree.Rectangle) (Line)
Inserting Values [ocaml-rtree-003]
- Patrick Ferris
There are two ways to insert values into the index -- either by inserting them one-by-one or by bulk loading them. The latter is the recommended approach where possible as the resulting layout of the R-Tree is much better.
# let r =
    let i = R.empty 4 in
    R.insert i Line.{ p0 = (1., 1.); p1 = (2., 2.) };;
val r : R.t = <abstr>
As you might expect, bulk loading takes a list of values instead.
# let r =
    let lines =
        Line.[
        { p0 = (0., 0.); p1 = (1., 1.) };
        { p0 = (1., 1.); p1 = (2., 2.) };
        { p0 = (2., 2.); p1 = (3., 3.) };
        { p0 = (3., 3.); p1 = (4., 4.) };
        ]
    in
    R.load ~max_node_load:4 lines;;
val r : R.t = <abstr>
Spatial Queries [ocaml-rtree-004]
- Patrick Ferris
The lines we loaded into the last index are really just four segments of the line y = x. Let's spatially query for the first two segments.
# R.find r (Rtree.Rectangle.v ~x0:0. ~y0:0. ~x1:2. ~y1:2.);;
- : Line.t list =
[{Line.p0 = (0., 0.); p1 = (1., 1.)}; {Line.p0 = (1., 1.); p1 = (2., 2.)};
 {Line.p0 = (2., 2.); p1 = (3., 3.)}]
You can see the query actually returned the first three, that's because all bound checks are inclusive.
The source repository includes a fairly simple example of rendering an R-Tree using Vg. This can be done outside of the repository using the tree representation.
# #show R.tree;;
val tree : R.t -> R.tree
type nonrec tree =
  R.tree =
    Node of (Line.envelope * R.tree) list
  | Leaf of (Line.envelope * Line.t) list
  | Empty
Here is an example rendering from the repository showing some random lines and the envelopes of the R-tree.
Weeklies
A collection of less thoughtfully crafted reports, focused on OCaml-related activities.
OCaml Roundup: September 2026 [ocaml-roundup-september-2026]
- October 7, 2026
- Patrick Ferris
Plenty of OCaml work in September, including a few releases of libraries I maintain:
rtreegot a new release.ppx_deriving_yamlxsaw its first release.I managed to upstream some Forester work that was living inside Graft.
Some work on ppxlib that is on its way into the world.
Weeklies
- October 7, 2026
- Patrick Ferris
Weeknotes 2026-w38 [weekly-2026-w38]
- September 18, 2026
- Patrick Ferris
Msh log 2026-38 [msh-log-2026-w38]
- September 18, 2026
- Patrick Ferris
After running some Dockerfile analysis last week, I have focused on formalising some operational semantics for the core POSIX-shell inspired language for a "mergeable shell".
This work borrows from Smoosh, but extends the semantics to include reasoning about namespaces, filesystems and effects.
For instance, here are two inference rules for field splitting and parameter substitution. Here, \sigma tracks the shell state, \phi is the filesystem and \tau tracks the side effects.
There are lots of interesting examples of this, like assignment during parameter substitution (e.g. ${FOO:=BAR}) or the side effects that take place during program name resolution.
OCaml Maintenance [ocaml-maintenance-2026-w38]
- September 18, 2026
- Patrick Ferris
A mixture of work in ppxlib and geocaml.
Ppxlib migration woes
- September 18, 2026
- Patrick Ferris
Ppxlib continues to prove itself as a tricky library to maintain. This week, a report came in from David about package_type attributes being dropped. These are new attributes that are attached to package expressions which simply did not have them before.
The solution here was to store these attributes on parent nodes (e.g. the core_type a Ptyp_pack might be a part of) when migrating from 5.4 to 5.3 alongside a ppxlib.migration attribute to distinguish them from the core_type's attributes. When migrating back up we then re-split the attributes.
David also landed a new syntax feature arriving in OCaml 5.6 that adds upstream support for expression "holes", something Merlin supports. It is now possible to replace any OCaml expression with _, for example, let x = 1 + _.
This needed explicit ppxlib support which, thankfully, was relatively straightforward as hole expressions do not have a lot of associated metadata or arguments.
Our benchmarking infrastructure is also back on its feet.
Thanks to Nathan for all the reviewing.
rtree.0.3.0 release [rtree-0-3-0]
- September 18, 2026
- Patrick Ferris
I cut a release of ocaml-rtree that removes the repr dependency. See the relevant discuss post.
This was a feature that Michael had asked for when building laserver. I took the time to open a PR to laserver to use rtree.0.3.0 which does simplify the code.
I wanted to ensure the library was still working, so I grabbed some of the LAS data for Lough Neagh, provided by OpenDataNI for 2017. After converting it to cloud-optimised point cloud (COPC) data via pdal (yes, two different "cloud" meanings) I managed to view the south-east portion of Lough Neagh.
This is overlooking the Lough Neagh Discovery Centre and Croaghan Island.
Outreachy
- September 18, 2026
- Patrick Ferris
After securing funding for this Outreachy round, I submitted an ocaml-tiff project. A year ago, we had an intern successfully add write support to the library.
This time, I hope to continue building out the library with an intern who is interested in learning OCaml, functional programming and geospatial data formats! One subgoal of the internship will be to create a tiffinfo-like command line tool that is distributed as part of the library. I also hope to add more compression algorithm support and iron out some API kinks.
Weekly 2026 w39 [weekly-2026-w39]
- September 30, 2026
- Patrick Ferris
Shells
- September 30, 2026
- Patrick Ferris
Work on the msh paper continued this week. One interesting result (for an appendix) was seeing what were the most commonly used commands in the Dockerfile dataset:
Which again, leads to some notion of overkill in terms of using a shell as the means to create container images when all we do is move some files around and install packages! I'm wondering if we're missing a real opportunity to streamline this process via something like the package calculus -- a package manager-agnostic means for declaring your dependencies.
Embed that as a programmable notion in your container image language alongside a container image-aware HTTP GET tool (to replace a vast majority of curl calls) and a handful of busybox commands, and you are left with (nearly) the raw shell only being used for the long tail of domain-specific things (e.g. invoking a build system).
Joy in old documents
- September 30, 2026
- Patrick Ferris
I'll talk about the joy I found in reading some historical bits and bobs tracking down information about shells, containers and operating systems more generally.
Part of this archaeological effort was trying to find when CHROOT was introduced into UNIX. Various online tools, including AI summaries, point to UNIX v7 but the system call is not obviously defined there. A bit more digging reveals it is listed under CHDIR(2) and not on its own.
Anyway, flicking through the manual was somewhat of a joy. The preface reads:
This new form of the Seventh Edition manual attests to the gratifying popularity of the UNIX Operating System. Delivered with no support and with an amateurishly published manual, this elegant and productive system has nevertheless earned worldwide respect, sometimes bordering on adulation...
Thousands of users today work from faint reproductions of reproductions of the original manual, whose ragged pages dangle and slide out of beat-up ring binders...
This bordering-on-poetic prose reminds me of some passages written for the MULTICS manual too (which I have talked about before).
All to say, I'm often thinking about the importance of writing these days and injecting some personality into it.
Part II Discussions
- September 30, 2026
- Patrick Ferris
I am hopefully going to supervise a part II project this year either on a fun ergonomic frontend to eBPF programs or a new spin on the geospatial DSL. More to follow once things are finalised.
Upstreaming Forester Pretty-printer
- September 30, 2026
- Patrick Ferris
I finally got around to upstreaming the Forester pretty-printing API I have been using in Graft. This allows you to print, hopefully, syntactically correct Forester code directly from the AST (a Code.t in forester parlance).
Happily, this all took place on tangled. It will be nice to keep this updated alongside Forester and point Graft to it. It feels like many people are moving away from a community-oriented model of software development, instead building a hybrid bazaarian cathedral monorepo powered by AI. I'm not here to really say what is right and what is wrong, but it seems to me that the sense of community is fragmenting and undue stress is being placed on many maintainers who no longer enjoy their job.
New release of ppx_deriving_ [ppx_deriving_yamlx-release]
- September 30, 2026
- Patrick Ferris
Raphael has proposed a new yamlx backend for ppx_deriving_yaml. It seems Ahrefs have been using his patch. I rejigged that PR to parameterise ppx_deriving_yaml over a small set of constructors and patterns so that the core codec logic could be reused.
I am fairly pleased with this abstraction. It allows any data format that supports objects and list to reuse the codec. For example, it would be trivial now to add a ppx_deriving_cbor.
OCaml Roundup: August 2026 [ocaml-roundup-august-2026]
- July 12, 2026
- Patrick Ferris
Much of August was spent thinking about POSIX shell semantics, and in particular extending notions from smoosh to include side effects (and maybe concurrency). This is still nascent work, but some ideas and flavours are described below.
Merging Shells
- July 12, 2026
- Patrick Ferris
The work came from wanting to merge two shell sessions into one. Setting aside the practicalities of an implementation, it makes sense to start first theoretically. When can I merge two shell executions, and when can I not?
It would be nice to think of unset DOWNLOAD_DIR as a function. This function takes the shell state and the operating state as arguments and returns a modified shell state and an "unmodified" operating system state (at least for our purposes). Meanwhile, branch-b may have a lot more side effects, but when focusing on the environment only we can see in a sense the two branches are conflict free. Well, sorta. We also need to ensure we do not also read DOWNLOAD_DIR in branch-b if we intend to remove it in their merge.
This work, in part, is borrowing ideas from MRDTs and can reuse void processes to help reason about when side effects can occur, as well as open-trace (which is now becoming os-trace).
I hope to continue this work, see my latest weekly for more on this.
Eio in the browser
- July 12, 2026
- Patrick Ferris
I spent some time carving out Eio_browser into a standalone library, something I depend on for Merry to work in the browser.
Eio_browser [eio_browser]
- September 12, 2026
- Patrick Ferris
- https://git.sirref.org/eio_browser
Eio_browser is a backend for Eio that works in the browser. It reuses work I started at Tarides that picked up some momentum but has since been a little dormant.
Crucially, it provides a functional standard environment like Eio_main or any of the OS-specific backends.
module Stdenv : sig
  type base =
    < stdout : Eio_unix.sink_ty r
    ; stderr : Eio_unix.sink_ty r
    ; clock : float Eio.Time.clock_ty r
    ; mono_clock : Eio.Time.Mono.ty r
    ; secure_random : Eio.Flow.source_ty r
    ; debug : Eio.Debug.t
    ; backend_id : string >
end

val run : (Stdenv.base -> unit) -> unit
(** [run fn] runs [fn] passing it the {! Stdenv.base} environment.
    See {! Backend.run} for more information about how effects are handled.*)
OCaml Roundup: July 2026 [ocaml-roundup-july-2026]
- July 12, 2026
- Patrick Ferris
Summary
- July 12, 2026
- Patrick Ferris
July was a slower month as I was on holiday for parts of it which broke a lot of work up.
By far the most exciting update was that we finally have a browser in the shell: Browsher. This is the culmination of lots of abstraction work in the core of Merry. In particular, dealing with file descriptors. I have added this to Eio_mem which now supports read-write pipes and FD duping! Read more about that in my weekly.
This work also had me writing a standard environment for Eio using the browser. You can see this in the browsher's setup module. This includes:
A capability for monotonic and normal time.
A source of secure random bytes using
WebCrypto.The fake in-memory filesystem coming from Eio_mem.
Other work had me fixing a long-standing bug where Eio.Path.load did not work on /proc files.
Weekly logs
- July 12, 2026
- Patrick Ferris
The full details are in the weeklies transcluded below:
Shell Benchmarks, Back to Writing [weekly-2026-w26]
- July 4, 2026
- Patrick Ferris
A little late due to travel, but I did a little benchmarking of Merry.
Signal Handling in Merry
- July 4, 2026
- Patrick Ferris
In order to even run shellbench, I first had to fix some bugs in the shell implementation. Shellbench aims to warm up the shell before starting any benchmarks; it includes this prelude before getting started:
__ready=
trap __ready=1 HUP
kill -HUP "$MAIN_PID"
until ["$__ready" ]; do __dummy=; done
Whilst writing Merry, I hadn't really considered that the return context from a trap needed to be taken into consideration! I had assumed they would be silently ignored, how else would we know where to thread that context back into the shell's execution.
Even after reading through the specification for trap I am still none the wiser. I've opted to place some sensible signal polling points during the execution of the commands to run any signals that have come in. The single handlers in Merry simply push thunks onto a run queue. Looking at the Dash source code, it seems to be something that happens just before evaluation.
Benchmarking Merry [merry-benchmarks]
- July 4, 2026
- Patrick Ferris
Medium-to-small potatoes
- July 4, 2026
- Patrick Ferris
I used shellbench to understand where some of the performance pitfalls were coming from.
$ ./shellbench -s bash,zsh,msh sample/func.sh
-----------------------------------------------------------------------------------
name                                                     bash        zsh        msh
-----------------------------------------------------------------------------------
func.sh: no func                                      775,539  1,124,485      5,229
func.sh: func                                         398,861    197,169     93,424
-----------------------------------------------------------------------------------
* count: number of executions per second
This particular benchmark first runs nothing (i.e. :) and then a function lookup and execution. Surprisingly msh is slower at doing nothing! I perf-ed a run of msh test.sh with just a single : in the file:
Test built-in
- July 4, 2026
- Patrick Ferris
After making various improvements to Merry that almost halved the memory usage (e.g., removing extraneous string manipulations, adding a fast-path to the PATH variable for resolving programs). I was still pretty far off the performance of these other shells. I decided to have a look at dash which has a simple implementation.
This flame graph is for the following shell script:
f () { :; }
while __count=$(($__count+1)) && ["$__count" -le 10000 ]; do
	f
done
echo "count is $__count"
And here are some rudimentary benchmarks:
$ time -p dash test.sh
count is 10001
real 0.01
user 0.01
sys 0.00
$ time -p msh test.sh
count is 10001
real 15.53
user 4.28
sys 12.28
It turns out the massive slowdown is very simple to explain. In the dash flamegraph there is a oexpr stack; which comes from the bltin/test.c file. dash, along with the other shells, does not spawn a process for the [-test command! Forcing dash to do use the binary [ gives:
$ time -p dash test.sh
count is 10001
real 7.55
user 3.95
sys 3.44
Which is much more respectable in terms of performance compared to msh. Plenty of work to do though!
Parsing arithmetic expressions
- July 4, 2026
- Patrick Ferris
There was some obvious low-hanging fruit to help improve some of the performance differences. The first was pre-parsing arithmetic expressions. Morbig, the static parser, does not implement arithmetic expression parsing; so Merry does it for us. Before, it was on-demand, as we encountered an expression of the form $((<e>)). Now, it happens up front. This should improve tight-loops.
Writing
- July 4, 2026
- Patrick Ferris
More on this soon, but I have started writing two separate papers bringing all of this work together.
Browsher and Namespaces [weekly-2026-w33]
- August 17, 2026
- Patrick Ferris
The work presented constitutes a good bit more than a weeks worth of work. That being said, let's dive in.
Browsher [browsher]
- August 17, 2026
- Patrick Ferris
After a week or two of abstracting the internals of Merry, I finally got a shell running in the browser. You can have a play with it here:
https://patrick.sirref.org/msh
The final hurdle was providing an abstract interface to file handles. Eio, the library that so far has enabled much of the OS abstraction, doesn't have a particularly good cross-platform file descriptor API. Eio_unix does extend sources and sinks with the Unix_fd tag, but there is no Eio.Fd.dup2 that provides a platform-agnostic API for file handle manipulation. Even if it did, a POSIX shell does a fair amount of assuming that your file handles are integers which might prove tricky on Windows.
The shell in the browser completely reuses the logic of Merry. It also links in a browser-aware subpackage of bruit (the OCaml port of linenoise I wrote) and a few, half-baked POSIX utilities I wrote (like ls and cat). But you can at least run something like:
$ echo "hello" > hello.txt
$ ls -la .
$ cat < hello.txt
Being able to, in some sense, run a shell anywhere is actually quite an attractive proposition. Shells, with all of their wonderful footguns, are still a reliable and familiar tool for interacting with a running system. I'm interested in the idea of running shells in more exotic deployments (e.g., unikernels) where it becomes an interface for dynamical reconfiguration or a tool for debugging.
Updates on Eio_mem
- August 17, 2026
- Patrick Ferris
At the heart of browsher is Eio_mem (an in-memory filesystem for Eio). The Eio_mem API now comes with (and exposes) a number of file descriptor operations:
val pipe : Eio.Switch.t -> Fd.t * Fd.t
val dup : sw:Eio.Switch.t -> Fd.t -> Fd.t
val dup2 : sw:Eio.Switch.t -> src:Fd.t -> tgt:Fd.t -> unit
I was happy to see Eio_mem getting some use in Thomas G.'s fork eio-fs where he was able to use it for chaos engineering.
Namespaces [namespace-musings]
- August 17, 2026
- Patrick Ferris
I spent a few days recently trying to come up with some formalism for the notion of names, namespaces and name resolution.
On the surface, it seems bigraphs might be a fruitful approach. The orthogonal treatment of locality and connectivity maps fairly well onto name structure (e.g, Module.X.foo, /foo/bar/hello.txt or foo.example.org) and redirection (e.g., symlinks or CNAMEs). Bigraph reaction rules could then model name resolution. A resolution process can move through the hierarchical name structure and across links at which point you might have some interesting properties to prove or check about a particular namespace system. Additionally, namespaces and resolution mechanism might compose in different ways and this might be worth formalising and comparing.
I didn't get much further than modelling some bits of a filesystem in BigraphER.
# filesystem
ctrl Dir = 0;
atomic ctrl File = 1;
atomic ctrl SymLink = 2;

# Query -- the thing that gets resolved.
atomic ctrl Q = 1;

# Reaction Rules
react resolve_symlink =
  Q{x} | SymLink{x, y} --> Q{y} | SymLink{x, y};

# Initial State
big s0 =
  Dir.
    (SymLink{sym_a, file_a}
     |
     Q{sym_a}
     |
     File{file_a}
    );

# Bigraphical Reactive System
begin brs
  init s0;
  rules = [ {resolve_symlink} ];
end
Resulting in these two transition states.
Bear in mind this was just a quick experiment. The first bigraph shows our query at sym_a and the second bigraph (using the resolve_symlink reduction rule) shows the query at file_a. All of this takes places within Dir. It seems that BigraphER represents the tree structure graphically with black arrows (rather than spatial containment).
Papers
- August 17, 2026
- Patrick Ferris
TODOs
- August 17, 2026
- Patrick Ferris
Over the next week, I hope to finish up a first draft of the aforementioned paper. I also want to publish a backlog of packages I have for OCaml: bruit, ocaml-bibtex, a fresh cut of Graft etc.
Ramblings
- August 17, 2026
- Patrick Ferris
I had some half-formed thoughts lying around in my forest, so I thought I might include those here:
Boilerplate [on-boilerplate]
- August 11, 2026
- Patrick Ferris
The word boilerplate gained popularity as a colloquialism used by newspaper and magazine editors for pre-prepared editorials and stories that were syndicated across the US. In effect, boilerplates were news stamps that could produce identical content.
I have been thinking about the nature of boilerplate code. How is it similar or different to boilerplate in its original meaning.
Distinguishing true boilerplate code from code that feels repetitive or boring to write is, I think, important. Argument parsing falls into this category quite well. Consider the following flag I added to Merry's set built-in.
let all_export =
  let doc = "Export all variables, like -o allexport." in
  Arg.(value & flag & info [ "a" ] ~docv:"ALLEXPORT" ~doc)
It uses cmdliner to define a new -a flag that will, in effect, make all variable definitions act like the export built-in. LLMs have been praised for their ability to do this specific task in OCaml.
What exactly is boilerplate about this code snippet? It seems to me that there is some sort of ceremony to defining a flag. There is boilerplate in the structure with more meaningful content threaded through. Below, is the example reduced to just the boilerplate replacing the for more meaningful parts with Merlin's typed holes: _.
let all_export =
  let doc = _ in
  Arg.(value & flag & info [ _ ] ~docv:_ ~doc)
Arguably the use of flag is quite important too as that is where the magic happens if you want an optional argument, or a positional one etc. As a thought experiment, having agents deliver fill-in-the-blanks style code might be quite useful. In a type system that can support holes (e.g. like in OCaml or Hazel) it becomes a more pleasant exercise, but helps keep you in the loop. I, myself, do not use any AI in the code I write; so I admit that I am pretty far from the problem.
The problem I have with this approach is that it is fairly easy to automate in a predictable and easy way! I just added a snippet subcommand to octx, but you could easily wrap this up in whatever your editor of choice is.
$ octx snippet cmdliner-flag
let cmdliner_flag =
  let doc = _ in
  Arg.(value & flag & info [ _ ] ~docv:_ ~doc)
The more I think on this problem the harder I find good uses for LLMs besides churning out vasts amount of end-to-end code; something I am personally not that interested in doing. It seems to me, to reap the benefits of LLMs, one must relinquish a certain amount of agency; anything less, and you could easily replace its usage with a cheaper, more predictable tool.
OCaml Roundup: June 2026 [ocaml-roundup-june-2026]
- July 12, 2026
- Patrick Ferris
Summary
- July 12, 2026
- Patrick Ferris
June saw a lot of progress on Merry. At the start of the month, I worked on meio, a tracing tool for Eio programs. This was to help debug a particular shell script fragment that was causing Merry to hang. It uncovered a few UX opportunities to make meio more useful, and this might be fruitful direction to take some of my work.
Merry is now able to run (and pass!) the entire unixfun benchmarks in Koala. Whilst benchmarking Merry, it became apparent that it is paramount to provide a test built-in (rather than spawning [).
Part of this work also looked into building an in-memory filesystem for Eio. It is still a work-in-progress, but does pass many of the filesystem tests in Eio. To be a drop-in replacement in Merry requires some more work to handle an abstraction for Unix file descriptors (e.g. a fake stdout). It would be nice if Eio provided a Unix filesystem interface similar to the OS-agnostic interfaces of Eio itself (not to be confused with the Unix utilities in Eio_unix).
I have been very grateful to Thomas's diligent and steadfast progress on merging and fixing bugs in Eio over the last few months. You can keep up to date with his work in his notes.
Weekly logs
- July 12, 2026
- Patrick Ferris
The full details are in the weeklies transcluded below:
Using meio to debug Merry [weekly-2026-w23]
- June 4, 2026
- Patrick Ferris
During a large rewrite of Merry, I introduced a regression causing certain shell programs to hang indefinitely. I thought it might be a good opportunity to try out Meio.
First, let's look at a trace of Meio from some real-world programs. For example: meio -- msh -c "sleep 100".
One problem that comes up immediately from this example is that the tree hierarchy of tasks and cancellation contexts makes it tricky to reason about the logging. Here, we can see the pipeline's cancellation context clearly labelled pipeline-id1. This is an Eio.Switch.t for the pipeline sleep 100. The actual execution log for sleep 100 bubbles back up to the main fiber (that has no name, so it is called <task>). The daemon fiber, for ensuring the spawned process is reaped, is attached to the switch and is displayed below it.
Meio has a long way to go. Most programs are too fast to be monitored in this way. Using something like tokio-console's model might be a better idea here focusing less on the tree strucuture of the program, and more on the performance and monitoring of individual tasks. Without this, it turns out Meio was not all that useful for debugging this specific issue (which ended up being some bad pipe management on my part).
Three weeks in the Shell [weekly-2026-w25]
- June 16, 2026
- Patrick Ferris
The last three weeks have been focused work on building Merry. In practice, I wanted to run the following two commands through Merry's shell: msh:
apt-get install debootstrap -y
debootstrap stable /stable-chroot http://deb.debian.org/debian/
Seemingly innocuous. But both commands run thousands of lines of shell script. Whether that's Debian package maintainer scripts or state-machines for processing package release files.
What follows is a handful of the bugs and the shell scripts that caused them.
Field Splitting
- June 16, 2026
- Patrick Ferris
Edge-cases abound in the POSIX shell specification; and field splitting is one of the most serious perpetrators. Field splitting happens after word expansion. It is a known footgun amongst shell script authors.
$ count () { echo "Count: $#"; }; FOO="hello world"; count $FOO
Count: 2
Quoting variables that need expanding will prevent field splitting from taking place, but it is an easy thing to forget.
Field splitting uses the IFS (internal field separator) environment variable to determine how to do the splitting, and it comes with some extra rules beyond "split on these characters".
$ IFS=" "; FOO=" hello    world"; echo $FOO
hello world
$ IFS=" "; FOO=" hello    world"; echo "$FOO"
 hello    world
$ IFS=":"; FOO="a:b:c:"; echo $FOO
a b c
$ IFS=":"; FOO="a:b::c:d"; echo $FOO
a b  c d
$ IFS=":"; FOO=":a:b:c"; echo $FOO
 a b c
$ IFS=; FOO="unset   IFS"; echo $FOO
unset   IFS
Variable assignment
- June 16, 2026
- Patrick Ferris
How a shell stores variables also impacts field splitting. Naively, Merry stored variables as strings, but really they should be stored as their expanded form.
Consider this example of saving a function output in a variable called base.
iter () {
 echo "a"
 echo "b"
 echo "c"
}

base=$(iter)

for n in $base; do
  echo "Got $n"
done

for n in "$base"; do
  echo "Got $n"
done
Later, when we come to iterate across the fields of $base we wouldn't be able to reconstruct the intial fields that $(iter) produced if we simply saved the result as a string. Too much information would have been lost.
Redirections
- June 16, 2026
- Patrick Ferris
Redirections control what file descriptors point to. Each redirection has a lifetime associated with it. For example: cat < README.md really says "open README.md and execute the cat program mapping the process's FD 0 to the FD of README.md". When cat returns that redirection is no longer valid.
Other redirections are not so simple. Consider:
$ echo "!dlrow olleh" > input.txt
$ (read line; echo $line) < input.txt | rev
hello world!
There are lots of redirections here too. Firstly the standard input for everything inside the braced command (read line2; echo $line) should be the open file descriptor for input.txt. The standard output of the braced command should be the writing end of a pipe whose reading end is passed to rev as that process's standard input. The final standard output for rev should be unchanged from what it was originally (the shell's standard output).
Getting redirections right is hard, consider this snippet from the debootstrap scripts (all in the context of stdout and stderr pointing to a debootstrap.log file and file descriptor 4 pointing at the true stdout).
for m in $MIRRORS; do
    pkgdest="$TARGET/$($DLDEST pkg "$s" "$c" "$a" "$m" "$path")"
    if [! -e "$pkgdest" ]; then continue; fi
    pkgs_to_get="$(download_debs "$m" "$pkgdest" $pkgs_to_get 5>&1 1>&6)"
    if [ -z"$pkgs_to_get" ]; then break; fi
done 6>&1
More niche built-ins
- June 16, 2026
- Patrick Ferris
As the dust begins to settle on the nuts and bolts of implementing a POSIX-ish shell, new challenges are allowed to emerge from deep within scripts.
One such challenge is the seemingly endless (I know, they're finite) shell built-ins! Whilst trying to run debootstrap using its fakechroot variant, I bumped into getopts... a whole command-line parsing shell built-in.
An In-memory Filesystem for Eio [eio_mem]
- June 16, 2026
- Patrick Ferris
Towards the end of last week and the beginning of this week, I threw together a prototype for an in-memory filesystem for Eio: Eio_mem. Concretely, this provides a means for constructing an Eio.Fs.dir_ty Eio.Path.t value that is completely in-memory.
Thanks to Eio's capability-first approach, any existing code implemented against the _ Eio.Path.t API should just work with the in-memory filesystem.
There's a convenient Eio_mem.Fs.load function that can take a path from one filesystem (most likely a normal one from Eio_linux or Eio_posix) and replicate it into the in-memory filesystem. For example, you might have a static web-server pointing to a directory like "/var/www". The following might be the only change you need to make it completely in-memory (example from ocaml-cohttp):
 let () =   let port = ref 8080 in
   Arg.parse
     [ ("-p", Arg.Set_int port, " Listening port number(8080 by default)") ]     ignore "An HTTP/1.1 server";
   Eio_main.run @@ fun env ->
+  Eio_mem.run @@ fun menv ->
   Eio.Switch.run @@ fun sw ->
-  (* Restrict to current directory: *)
-  let htdocs = Eio.Stdenv.cwd env in
+  (* Restrict to in-memory current directory: *)
+  Eio_mem.Fs.load ~filter (Eio.Stdenv.cwd env);
+  let htdocs = Eio.Stdenv.cwd menv in
   let socket =
     Eio.Net.listen env#net ~sw ~backlog:128 ~reuse_addr:true
       (`Tcp (Eio.Net.Ipaddr.V4.loopback, !port))
The keen-eyed reader might have noticed the filter parameter. This can be used to ignore certain paths (here I ignored .git and _build which were adding substantial time to loading the filesystem).
OCaml Roundup: April 2026 [ocaml-roundup-april-2026]
- April 7, 2026
- Patrick Ferris
In April, I worked on lots of different projects. Thankfully, things have been quiet on the ppxlib front (in part due to Nathan taking on some more work and being between releases of the OCaml compiler). I managed to improve some of our migration error logic and do a little spring-cleaning.
More Landlock Thoughts
- April 7, 2026
- Patrick Ferris
Elsewhere, I spent some time exploring Landlock and how it might be used with Eio. I think it is useful to down tools once in a while and try out some newfangled API or OS feature. Landlock is quite different to Capsicum (I had assumed they would be more similar). Whilst I enjoy the fine-grained control over access and capabilities, the manual process of constructing rules is a little cumbersome (and perhaps easy to make mistakes with). Combining that with [Eio]'s capability API might make that more tenable. The idea being you could have some Eio code like:
let () =
Eio_linux.run @@ fun env ->
let data = Eio.Path.(env#fs / "/data") in
Eio.Path.with_open_dir sw data @@ fun data_dir ->
match Eio_linux.Landlock.enter () with
| Error (`Msg m) -> failwith msg
| Ok () ->
(* At this point, only certain default operations can happen to [data_dir].*)
analysis data_dir
Opening the directory (in the openat-sense) adds a Landlock rule to the current context (some kind of process-local state). This rule would be removed whenever the data directory is closed (by hand or when the function returns, i.e., when the internal Eio.Switch releases its resources). Doing the bookkeeping internally means mistakes are less likely to be made whilst also improving, in my opinion, the API.
This breaks down for networking, unfortunately. Whilst the filesystem hierarchy provides a clean way to produce capabilities (a handle on a directory + openat + RESOLVE_BENEATH), networking does not. The Landlock API, at the time of writing, only allows rules based on port numbers. The system API is completely ambient (socket + connect). Eio's API provides access to the network through a single network `capability. All of these mechanisms are somewhat at odds. What does a network look like if it adheres to the ideas we have for combining Landlock and Eio (like in the filesystem example)?
The API becomes port-oriented. We're already at odds with Unix domain sockets, but we will carry on regardless. A capability on a port means you can listen on that port and accept connections, or you could connect to it and send data. At the time of writing, Landlock is restricted to TCP ports. In Eio, there is no API to with_open_port, i.e., to register your intent to do something with that port -- you either listen or connect.
All of this starts feeling a lot like Plan 9; something which I hope to explore further soon.
Weekly logs
- April 7, 2026
- Patrick Ferris
The full details are in the weeklies transcluded below:
Moving away from Github [weekly-2026-w15]
- April 13, 2026
- Patrick Ferris
A short week for me as I was hiking with family in and around Porthmadog, Wales.
Reliance on Github
- April 13, 2026
- Patrick Ferris
I joined Github in 2016, but only began using it in earnest (according to my Github activity) in July 2018: right after Microsoft announced its intent to acquire Github; and just before they closed the $7.5bn deal. I originally joined to boost my résumé and I hoped to receive the odd open-source contribution to projects I was working on (like ppx_deriving_yaml). Since then, I have used Github extensively both at work (Tarides) and for more personal projects.
There have been many reasons to jump ship from Github ever since the Microsoft acquisition (e.g. their planned (and quickly unplanned) announcement to charge self-hosted Github runners). Ultimately, I was convinced when I noticed the new AI tool on the homepage with options to select your "versatile and highly intelligent" model. There is no need for me to stay on the platform for my personal projects. AI integration into Github has nullified those earlier motivations for hosting my projects on the site. The number of contributions has increased, but many of them fix superficial elements of an underlying bug. In my (maybe too uncharitable) imagination, it is all too easy for contributors to prompt their built-in LLM to "fix this broken unit test" and for the fix to layer a single-use workaround on top, instead of identifying and correcting the relevant code. This is, at least, what it looks like to me when I receive a new review request on my open-source projects.
At the end of last week I set up my own Git infrastructure following Ryan's nixos setup. In the future, the source of truth for my projects will be git.sirref.org (I will likely continue to mirror to tangled.org or Github).
Reduce, Reuse, Recycle
- April 13, 2026
- Patrick Ferris
Part of self-hosting your own source code is managing some form of automatic testing. I hesitate to describe it as "continuous integration" as the term is confusing and overloaded. Luckily, parts of the OCaml community have been building test infrastructure for a while.
I have a proclivity for rebuilding things from scratch be it to learn or to build something the way I want. It is a proclivity I am trying to reign in as I find less and less time to hack on projects. I think this is a good thing. Reusing and recycling existing technologies, in earnest, feels like a pushback on the not-invented-here syndrome that seems to be snowballing thanks to LLMs and code generation tools.
To that end, I dusted off my OCurrent knowledge, and repurposed the "local" mode of OCaml-CI to work with my git repositories. After battling through nested layers of git submodules, I managed to Nix-ify this and get it running at tests.sirref.org. I needed to add multi-repository support as well as Current.Monitors for the local git refs. By no means perfect, but it is nice to own the testing infrastructure (and the cost of downloading OCaml images and the compute to run the tests).
Landlocked Eio [weekly-2026-w16]
- April 18, 2026
- Patrick Ferris
I spent the start of last week wrapping up the "local" CI I mentioned the previous week. Unfortunately it was mostly a packaging nightmare, followed by missing features in ocaml-ci-local. It would be great to have a richer CLI tool for running tests on a directory of git repositories, but unfortunately most of the existing tooling has prioritised the Github/Gitlab etc. APIs.
After coming across minimal during the week, I took it as an opportunity to learn a little more about Linux's Landlock mechanism.
Landlocked Eio [landlocked-eio]
- April 18, 2026
- Patrick Ferris
Landlock is a sandboxing mechanism that has existed in the Linux kernel since 5.13. It allows unprivileged processes a means to restrict their ambient rights (e.g. creating a file or opening a network connection). These rights are ambient in the ambient authority sense, i.e., any process can attempt to perform an action without needing access to any particular capability to do so.
Ambient systems are often contrasted with capability-based ones. In terms of operating systems, this is most commonly illustrated with access-control-lists-as-columns and capabilities-as-rows in an access matrix.
Eio is a capability-based library in OCaml -- resources are provided at the start of the application and can be passed around wherever they are needed. The design is covered in Thomas Leonard's lambda capabilities blog post. Unfortunately, any application (willingly or via a third-party library) may ambiently access OS resources. In OCaml, this may be by using the standard library functions (e.g. Sys.readdir), things from the Unix module, a C FFI function or by spawning a subprocess.
I had a go at "landlocking" Eio applications last week after stumbling across minimal's hakoniwa library for process isolation (which is very reminiscent of void processes).
module Landlock = Eio_linux.Landlock
let ( / ) = Eio.Path.( / )
let run_eio file =
Eio.traceln "Writing to file";
Eio.Path.save ~create:(`Exclusive 0o644) file "hello, world!";
Eio.traceln "Reading file: %s" (Eio.Path.load file);
Eio.Path.unlink file
let bad_program () =
In_channel.with_open_bin "/etc/passwd" In_channel.input_all
|> Eio.traceln "/etc/passwd: %s"
let () =
Eio_linux.run @@ fun env ->
Eio.Path.with_open_dir (Eio.Stdenv.cwd env / ".") @@ fun dir ->
let parent_fd =
Eio_unix.Resource.fd_opt (fst dir) |> Option.get
in
let file = dir / "hello.txt" in
let rules =
Landlock.Rule.
[
path_beneath ~parent_fd
~flags:Flags.Fs.(
write_file + read_file + make_reg + remove_file
);
]
in
match Landlock.enter rules with
| Ok () ->
run_eio file;
bad_program ()
| Error `Not_supported -> Eio.traceln "Landlock not supported!"
Running this program (with the necessary privileges) prints the following.
+Writing to file
+Reading file: hello, world!
Fatal error: exception Sys_error("/etc/passwd: Permission denied")Eio already has a similar function for the BSDs using capsicum. In capsicum, processes enter a capability mode:
cap_enter()places the current process into capability mode, a mode of execution in which processes may only issue system calls operating on file descriptors or reading limited global system state.
This plays nicely with Eio's capabilities. Within the scope of Eio.Path.with_open_dir, the directory will remain usable after entering "cap" mode. This is not the case with landlock unless you add a specific path_beneath rule to the ruleset (like in the example above). However, you could imagine plumbing the necessary information throughout the Eio_linux backend for it to build a set of rules that can be applied at any given moment in order to mimic the capsicum semantics.
Self-hosting Music [self-host-music]
- April 18, 2026
- Patrick Ferris
After my friend, Greta, sent me some articles about music streaming services and their exploitation of artists, I decided enough was enough and setup navidrome. It is compatible with Subsonic and so far I'm very pleased to be streaming my own music to my devices. I am using substreamer on iOS. On my laptop, I tried out Andreas Rossberg's Camp
What you got here is an old-school music player heavily inspired by good old Winamp [1], with a focus on decent music library and playlist handling.
I took Anil's OCaml Installer tool for a spin with great success... after a few mishaps mostly related to system dependencies.
$ nix-shell -p pkg-config gcc pulseaudio miniaudio libxi libxrandr libxinerama libffi mesa libxcursor libGL $ oi-linux-x86_64 run --with=https://github.com/patricoferris/camp#nix -- camp
The fixes in my fork of Camp are just to install the assets using dune and also statically provide the -lpulse flag (which should probably be dynamically picked up). Otherwise, raylib or miniaudio selects the Null playback device. Roll-on cross-ecosystem package management.
Shell forks revisited [weekly-2026-w17]
- April 28, 2026
- Patrick Ferris
Whilst I did get up to some other work last week, I decided to dedicate this weekly to fork-ing in the shell.
Must we fork?
- April 28, 2026
- Patrick Ferris
I have spent some time trying to figure out: can you implement a shell that never has to fork and run its own code (as opposed to fork+exec-ing, which is necessary)? There are, at least, two bits of POSIX shell semantics that make this hard: concurrency and redirects, particularly in the presence of shell built-ins.
Individual commands in a pipeline, according to the POSIX specification, will have their standard input and output connected up before other redirections.
The standard input, standard output, or both of a command shall be considered to be assigned by the pipeline before any redirection specified by redirection operators that are part of the command.
Additionally:
...each command of a multi-command pipeline is in a subshell environment; as an extension, however, any or all commands in a pipeline may be executed in the current environment.
Where a subshell is defined as:
Subshell: A shell execution environment, distinguished from the main or current shell execution environment.
We will note that subshell \neq child process. In practice, however, the two are used fairly interchangeably given the semantics of spawning a child process. Perhaps the two most crucial aspects of a given command in a subshell are that:
It is run in parallel with the other commands.
It should be reentrant.
In what follows we will assume that we are discussing a multi-command pipeline p.
\texttt {p} = \texttt {cmd}_1 | ... | \texttt {cmd}_n \text { where } n \geq 2
Pipeline parallelism
- April 28, 2026
- Patrick Ferris
The POSIX specification does not mandate parallelism explicitly for commands in a pipeline. However, in practice the semantics of a pipeline necessitate concurrency at the very least.
Suppose we have \texttt {cmd}_1 | \texttt {cmd}_2 where \texttt {cmd}_1 produces an infinite amount of output (e.g., cat /dev/urandom) and \texttt {cmd}_2 consumes a finite amount of input (e.g., hxd-xxd -l100). What is the result of running this pipeline with the default POSIX shell options?
$ dash -c "cat /dev/urandom | hxd.xxd -l100"
00000000: 5033 7981 ae44 d475 074c 5361 0a9e 3828 P3y..D.u.LSa..8(
00000010: f88c 1f9e 3b0e bcde 528a f78c b1e4 7195 ....;...R.....q.
00000020: 16f2 8325 c90b 9310 539c af04 8289 c3a0 ...%....S.......
00000030: 57c5 680a 2c81 a999 71b6 708e 95df e720 W.h.,...q.p....
00000040: 004c 407a 8365 9448 65c6 b435 bed2 4084 .L@z.e.He..5..@.
00000050: 62ea 96ab 2b23 0385 f9d2 fc30 d090 1719 b...+#.....0....
00000060: 68d1 c514 h...
cat: write error: Broken pipe
There are three factors that influence the pipeline's execution behaviour (i.e. what is done about the commands that are run and the exit status we return).
pipefail: Withpipefailset tofalse(the default), the exit status of the pipeline is entirely decided upon by the exit status of the rightmost command (above \texttt {cmd}_2). Withpipefail, the pipe will exit with 0 if all commands exit with 0; otherwise the non-zero exit status of the rightmost command is taken.!: If the pipeline begins with!then this inverts the exit code in the way you might expect.All commands must terminate.
Whilst in theory \texttt {cmd}_1 does not terminate, the termination of \texttt {cmd}_2 closes the reading end of the pipe resulting in the Broken pipe system error.
Let's replace \texttt {cmd}_1 with the following compound command that also produces, left to its own devices, infinite output on stdout.
while echo "some bytes"; do
:
done | hxd.xxd -l100
In this example, we no longer have the luxury of being able to fork and exec. The compound command (the while loop) forces our hand -- we must rely on the internal execution logic of the shell to keep it going. How then do we prevent \texttt {cmd}_1 from blocking our shell from spawning \texttt {cmd}_2?
For most shells, this is where they might fork themselves and allow the while loop to execute in the child. The parent continuing on. Alternatively, the work could continue on in a separate thread (in OCaml parlance, domain). Fibers (green threads, coroutines etc.) are only possible if there are a sufficient number of co-operative yields (which can be hard to track: any control flow or shell built-in would need to ensure they periodically yield to the other commands in the pipeline).
With that being said, it would seem we have workarounds to ensure the parallel aspects of pipelines are possible to build without forking the shell state itself.
Command Reentrancy
- April 28, 2026
- Patrick Ferris
Command reentrancy deals with the fact that commands in a pipeline run in subshells. In practice, this means any \texttt {cmd}_i should not impact the execution environment of any other \texttt {cmd}_j. Commands may certainly interfere with one another: a rogue rm might remove a file that some other command was about to read or was in the middle of reading!
\S 2.13 of the POSIX shell specification describes the execution environment. In Merry we lift this into the ctx type making it completely immutable; the only way to update the context is to destructively declare new fields, e.g., { ctx with cwd = "/home/bactrian" }. All shell built-ins work directly from the context as opposed to any state that might also be kept by the process itself (e.g., we do not call getcwd(3) to expand PWD, but instead read it from the context).
Most state is handled nicely by this functional implementation of the shell; except open (or not) file descriptors. The exec built-in is particularly thorny in this regard:
If exec is specified with no operands, any redirections associated with the exec command shall be made in the current shell execution environment.
So, exec 3>&1 says "in the current execution environment map file descriptor 3 to stdout" and exec > /dev/null says "in the current execution environment map stdout to /dev/null. This is often used to silence anything writing to stdout.
info () {
echo "INFO: $1" >&3
}
exec 3>&1 > /dev/null
info "Starting up server..."
echo "Some noisy program spamming STDOUT"
info "All is quiet..."
If we are not running shell built-ins inside new child processes, then we must lift the file descriptor table into the context as well and disallow any two built-ins to run in parallel. Consider this example:
exec < ./hello.txt
while read line; do
echo "Got $line" >&2
done | (exec < ./world.txt; cat)
If we allow exec to change the set of open file descriptors of the shell process directly, then individual commands in the pipeline are no longer re-entrant. The pipeline here is not being used to pipe bytes from one command to another, but instead to expose concurrency and the subshell behaviour.
The second exec < ./world.txt has no impact on the currently opened file on stdin, the while loop continues to read ./hello.txt. This is straightforward to implement with fork as you can dup2 any files you need. The bookkeeping and isolation is all provided by the POSIX process semantics. Without fork, the file descriptors would have to be saved and restored on every suspension and resumption to provide an illusion of isolation.
We could relax our rule to "disallow any two built-ins to run in parallel" by taking a lock on the file descriptor table, but considering the lock is held from the point of resumption until the next suspension it might not achieve very much in practice.
Some of the intricacies of scheduling are also covered in Michael Greenberg's An executable and formal semantics of the POSIX shell.
To motivate the question, consider the following two pipelines:
(1)
while true; do echo 5; done | true(2)
while true; do echo 5; done | { read x; echo $((x+42)); }Both pipelines spawn two processes, both of which use shell builtins exclusively: neither of these pipelines needs to make an
execvesystem call (though some systems may implement true or echo as executables, Smoosh and most shells build them in).
Scheduling is an opaque part of the POSIX specification. Indeed, as we have argued here, there is no semantics for scheduling. Here is a similar pipeline run through a script that straces for clone and fork calls on various shells:
% ./test/check_fork.sh "while echo 5; do : ; done | true" bash 3 dash 3 yash 1 zsh 1 ksh 1 ash 3
It might make an interesting use case for effects in OCaml -- whilst we can certainly piggyback on Eio's existing suspension mechanisms, this is slightly different in that we need to ensure some preconditions are true before resuming certain computations. Fiber-local state is insufficient as programs implicitly depend on global state of the process (in particular the FD table). In this sense, we need some form of suspension-resumption hooks.
OCaml Roundup: March 2026 [ocaml-roundup-march-2026]
- March 10, 2026
- Patrick Ferris
A POSIX Shell in OCaml [weekly-2026-w12]
- March 19, 2026
- Patrick Ferris
Long time, no weekly. Since the start of this year I have been building a POSIX shell in OCaml called msh (with the underlying library called Merry). Merry is available online now.
A POSIX(ish) shell in OCaml
- March 19, 2026
- Patrick Ferris
Merry is a POSIX(ish) in OCaml. It uses Eio alongside Morbig (a static parser for POSIX shell).
Why another (POSIX) shell?
- March 19, 2026
- Patrick Ferris
Shells have been around for a long time. In my research on the notion of metashell I wrote about Louis Pouzin originally coining the term:
Metashells › Louis Pouzin's "SHELL" [pouzin-shell]
- May 19, 2025
- Patrick Ferris
I spent some time reading part of the multics design documentation this week. Louis Pouzin coined the term "SHELL" in this document, and I was reminded yet again just how important it is to be a good writer even as a "computer science researcher". For example, this excerpt from the requirements section of the document
The previous definitions imply that a command MUST be designed while keeping in mind the user, sitting at his console, wondering about what might be going on, mistyping or forgetting arguments, even if fully aware of the conventions, and possibly interfering with the command by hasty quits, carriage returns, and other temperamental reactions.
And then later, when defining the "SHELL".
We may envision a common procedure called automatically by the supervisor whenever a user types in some message at his console, at a time when he has no other process in active execution under console control (presently called command level). This procedure acts as an interface between console messages and subroutine. The purpose of such a procedure is to create a medium of exchange into which one could activate any procedure, if it were called inside of another program. Hereafter, for simplification, we shall refer to that procedure as the "SHELL".
It still surprises how little the undergraduate degree in computer science at Cambridge focuses on writing skills.
I built Shelter exploring the idea of a shell-like interface that allowed users to undo their shell actions (amongst other cool tricks). Unfortunately shell-like is not enough. Shelter cut many corners to masquerade as a shell (e.g. appending env to understand how a command may have altered the execution environment). I felt it was necessary to make Shelter a "SHELL"! To do that, I needed a solid foundation to build on.
msh, the POSIX shell that comes with Merry, is by no means POSIX-complete in terms of features. But it is my daily driver at this point. It includes a pure OCaml rewrite of linenoise (a small, self-contained alternative to the venerable readline) called bruit.
If you have docker installed on your machine, you can take it for a spin today:
docker run -it --rm patrickferris/msh
The patrickferris/msh docker image is just for trying it out. It is based on the OCaml 5.3 alpine image.
Alternatively, you can build msh from source and have it available in your opam switch.
opam pin git+https://tangled.org/patrick.sirref.org/merry
There are many small paper cuts left to patch over, but most of it is porcelain (e.g. ctrl+left-arrow for moving in bruit). Unfortunately, these are the kinds of things that you will immediately stumble upon.
What makes Merry different?
- March 19, 2026
- Patrick Ferris
Nothing.
Merry is supposed to be a solid, POSIX-ish base to build on. Unfortunaltely, as it turns out, the subset of features from the POSIX specification that people actually use... is pretty much all of it. Every possible redirection, variable expansion, shell built-in and compound command make some appearance. Not to mention the non-POSIX bits of shell we all take for granted (e.g. &>-redirection).
Merry and msh are useable. You will most likely find bugs if you use them. If, when using msh, you find something obscure happening you can enable debug mode either my setting the variable MSH_DEBUG or by invoking msh with -v -v.
What's next?
- March 19, 2026
- Patrick Ferris
It is soon time to combine Shelter and Merry into the time-travelling, POSIX-ish shell that I have been trying to build since I first started working on Shelter.
For this to be successful, I need Merry to be able to pass plenty of tests and right now that involves trying to install plenty of packages using tools like apk and apt.
Shell MRDT
- March 19, 2026
- Patrick Ferris
What I am particularly interested in reasoning about, is the execution context in Merry. This value, alongside the file-system, constitutes a fairly deep understanding of the state that changes in each step of a shell's evaluation loop.
This was, in terms of Shelter, the missing piece for truly building some kind of MRDT across shell sessions.
TIFF in OCaml
- March 19, 2026
- Patrick Ferris
I picked up from the excellent Outreachy work of Tambe Salome in getting write-support in ocaml-tiff. We are getting closer to the kind of API I envisaged in this latest round of refinement and review.
let ( / ) = Eio.Path.( / )
let checkerboard ~size =
let v = Nx.zeros Nx.uint8 [| size; size |] in
for row = 0 to size - 1 do
for col = 0 to size - 1 do
if (row + col) mod 2 = 0 then Nx.set_item [ row; col ] 254 v
done
done;
Nx.to_bigarray v
let () =
Eio_posix.run @@ fun env ->
Tiff_eio.with_open_out (env#cwd / "example.tiff") @@ fun w ->
let tif = Tiff.make (checkerboard ~size:256) in
Tiff.to_file tif w
I have also been extremely pleased to see further external collaborators appearing:
Ppxlib release and Merry updates [weekly-2026-w13]
- March 30, 2026
- Patrick Ferris
Ppxlib Releases › 0.38.0 [ppxlib-release-0-38-0]
- March 30, 2026
- Patrick Ferris
Nathan and I released ppxlib.0.38.0 last week. Its main feature is full migration support for the upcoming OCaml 5.5 compiler (currently in its alpha3 release). This means supporting the handful of new features landing in OCaml 5.5: modular explicits, external type declarations and arbitrary "local" structure items.
As Nathan and I continue to find a plausible maintenance story for ppxlib, Nathan has opened an issue on the OCaml compiler to discuss the idea of adding additional extension points to the language.
This comes from the desire to be able to store encoded versions of new OCaml features inside older abstract syntax trees.
There are also some nice bug fixes in there too:
A potential OOM loop has now been removed.
Merry updates
- March 30, 2026
- Patrick Ferris
It turns out writing a POSIX(ish) shell is hard; at least, there is a vast number of slightly obscure features that one needs to support. I think this is surprising because most people writing shell scripts write simple shell scripts; scripts that use a much smaller subset of features. In the same breath, those same developers are likely to use something like apt-get install bash which runs a plethora of more advanced (and non-POSIX) shell scripts!
Exec redirects
- March 30, 2026
- Patrick Ferris
In a shell script, you can use the built-in command exec to replace the current process with a new one (e.g. exec vim). However, there is a different mode of operation for exec:
If exec is specified with no operands, any redirections associated with the exec command shall be made in the current shell execution environment.
One of my litmus tests for Merry is the Debian debootstrap scripts (h/t Anil). One thing that it does is the following:
err () {
printf "err $1" >&4
}
exec 4>&1
A lot of detail has been elided for clarity. exec 4>&1 sets up a redirection for the shell's execution environment in which file descriptor 4 is now an alias for standard output. So, writing to 4 (by redirecting a command's standard output to 4 i.e. >&4) will output to where standard output is going (most likely the terminal).
For this to work, shell's must dup2 the relevant file descriptors which have the following condition:
If the file descriptor newfd was previously open, it is closed before being reused; the close is performed silently (i.e., any errors during the close are not reported by dup2()).
This is all very well, unless your program has an important file already open that happens to have file descriptor 4. The Eio Linux and POSIX backends suffer from this problem. Both make use of a file-based synchronisation mechanism for waking up the eventloop should another domain push a completion to the scheduler's run queue. On Linux this is via an eventfd and in POSIX, a pipe.
This dup2 will close the eventfd and will likely grind Eio to a halt (or an assert false). For now, I have resorted to vendoring Eio and moving the eventfd file descriptors to higher values, though I have opened a PR to make this more configurable. This bug is quite easy to write up... it was not so easy to find!
As a random example, consider the debconf/confmodule script which offers very little room for a buggy implementation!
Outreachy
- March 30, 2026
- Patrick Ferris
The presentations from the demonstrations for this round of Outreachy are now online!
Write support in OCaml TIFF library [outreachy-ocaml-tiff]
- February 9, 2026
- Patrick Ferris
I am mentoring Tambe Salome during the December 2025 Outreachy round to add support for writing TIFF files in the ocaml-tiff library.
You can now see the video of the demonstration day presentation:
Forking in Shells & Library Maintenance [weekly-2026-w14]
- April 3, 2026
- Patrick Ferris
This week, Merry got close to executing apt-get install ca-certificates and running Debian's debootstrap scripts correctly. Nathan and I released Ppxlib 0.38.0, I added support to ocaml-proj for compiling to the browser and I fixed a long-standing bug in hilite.
Forking in Merry
- April 3, 2026
- Patrick Ferris
So far, Merry has managed to support many features of the POSIX shell specification without needing to do a fork(2) without an exec. Or, to put it another way, all the forking that Merry does, will only be followed by running C code. This is actually a feature of Eio's Process API. It is required to make process execution safe in the context of multiple domains in OCaml (mostly due to ensuring consistency within the garbage collector). However, it is perfectly okay to fork and run OCaml code provided there is only a single domain.
In a shell, many features of the shell language require that commands (or built-ins, function applications etc.) execute within a subshell. The specification does not go into detail about how shells should implement this, but many choose to fork in order to preserve some state in the parent (for example, the file descriptor table). Some shells try to minimise the number of forks as an optimisation. The korn shell (ksh) is one such shell.
Using the notation
$(command)will causecommandto execute in a subshell of the current ksh. In many instances, ksh will not actually fork/exec a subshell when command is a built-in or a shell function.
By trying to adhere to Multicore OCaml's "thou shalt not fork" commandment, Merry is much more similar to ksh in this regard. However, whenever there is an interaction with a shell built-in and semantics that need a child process, things get tricky very quickly. Consider the following:
while echo "hello"; do
:
done | head -n 3
We have a mix of shell built-ins, normal commands, a compound command (the while loop) and a pipeline. Each individual command in the pipeline requires you to run them in a subshell and set them up before executing them. Without a fork for that first command, you may end up looping forever which is not the intended behaviour here. I had a good conversation with Michael about the implications of this for reproducibility.
For now, I have started implementing a fork for some of the shell features whilst still trying to maintain the functional core of the implementation.
An OCaml 5.5 compatible Ppxlib
- April 3, 2026
- Patrick Ferris
Nathan and I released an OCaml 5.5 compatible version of ppxlib.
Ppxlib Releases › 0.38.0 [ppxlib-release-0-38-0]
- March 30, 2026
- Patrick Ferris
Nathan and I released ppxlib.0.38.0 last week. Its main feature is full migration support for the upcoming OCaml 5.5 compiler (currently in its alpha3 release). This means supporting the handful of new features landing in OCaml 5.5: modular explicits, external type declarations and arbitrary "local" structure items.
As Nathan and I continue to find a plausible maintenance story for ppxlib, Nathan has opened an issue on the OCaml compiler to discuss the idea of adding additional extension points to the language.
This comes from the desire to be able to store encoded versions of new OCaml features inside older abstract syntax trees.
There are also some nice bug fixes in there too:
A potential OOM loop has now been removed.
Browser support for ocaml-proj [ocaml-proj-virt]
- April 3, 2026
- Patrick Ferris
A while ago I built some "modern" bindings to PROJ4 in OCaml. After reading Jon Ludlam's weeknotes (and speaking with him and Anil, I thought it might be nice to add a Javascript backend to those bindings). This was relatively straight-forward using Dune's virtual libraries and is available on Github.
With virtual libraries, your own data analysis could (if you wished) depend solely on the proj library and later choose to either link it with proj.c or proj.js depending on where the analysis is being deployed.
I briefly looked at WASM support, but quickly realised there was not much appetite for it and trying to compile around the C FFI was going to be hard.
Hilite updates
- April 3, 2026
- Patrick Ferris
Since I helped relaunch the ocaml.org website a few years ago, I have maintained hilite, a tool for doing build-time syntax highligting.
It is being used on the ocaml.org website, in yocaml_markdown and also in Michael's webplats (when it works...).
And it was Michael who led me to finally fixing and adding syntax highlighting support for Python and Go. Once I was on this roll, I finally took a look at fixing the long-standing bug of trying to highlight ocaml-mdx code, like the following:
# 50.123;;
# 1 "file.ml";;
In fact, this code now highlights fine, but was the source of the bug. The syntax highlighting grammer confuses the ocaml-mdx # as a toplevel directive and trouble ensues.
OCaml Roundup: February 2026 [ocaml-roundup-february-2026]
- March 10, 2026
- Patrick Ferris
Much like last month, this month has been busy with lots of work on ocaml-tiff thanks to Tambe Salome and ppxlib.
Outreachy
- March 10, 2026
- Patrick Ferris
Tambe Salome, at the time of writing, has completed her internship! We will be hosting the biannual Demo Day celebration for this round's interns, so please do come along.
Since the last update Tambe Salome and I have been slowly making progress on making the write-functionality more feature-complete. As I eluded last month, TIFF files are hard to write. Their internal structure is all over the place: directories, immediate and non-immediate values, 32-bit or 64-bit, little or big endian etc. We're tackling this bit by bit, evolving the library to be able to support writing to files. In the early days, when we only read TIFF files there was no need to store information that we could readily pull from the file itself (via something like pread(2)). Now, we need to be able to hold those same values in memory before writing them to the file, so we will need some kind of API change internally to support this.
This month, I also bumped up against well-meaning contributions to ocaml-tiff that made use of AI. This left me with some thoughts that I am adding below.
Vibecoding Etiquette [vibecoding-etiquette]
- March 9, 2026
- Patrick Ferris
I am yet to jump head-first into using LLM-based tools like Claude Code or even ChatGPT to help with my programming in any serious way. After using some "free"-tier tools to try to better understand some tricky eBPF problems and to make sense of the semantics of POSIX shells, I was left unimpressed and ultimately felt my time was wasted.
I feel unwilling to send my money to the corporations behind these tools. This is for a variety of reasons including the deeply worrying relationship with the US Department of War (I struggle to find the meaningful difference between "opertational planning" vs. "operational decision-making" given the leaders of the US DoW), environmental concerns, exploitation of human labour and a fast-and-loose approach to copyright laws. All of which leaves the entire industry very unattractive to me.
Everybody can draw their line where they want, and I am, in good faith, trying to find where mine should be.
Unfortunately, my own decision to not use these tools is not completely in my control. What do I do about pull requests to open-source libraries I maintain that include agentic code? I am, after all, participating in the idea of open-source and inclusive collaboration. Agentic code also comes in many flavours, from blatant LLM-generated pull requests to heavily edited, human-in-the-loop contributions.
An immediate first step for me is to develop some policy for contributions to projects I maintain regarding code where LLMs have had a hand. This can help set expectations for contributors. Eio's "AI-generated Code" subsection is succinct and prohibits contributions that solely use AI.
It obfuscates how you think. Purely AI-generated code tells us little about how you think and the problems you might be having. This makes it harder to provide good feedback on PRs and issues.
It is often more work to review. Particularly for the OCaml ecosystem and libraries like Eio, it seems that these tools are not very good and generate a lot of believable code that is in actual fact completely wrong. PR comments and the code submitted with them can say completely different things.
It is a grey area for licensing. Models like ChatGPT have been trained on lots of code with different licenses and has been known to simply copy code as an answer to a prompt. We would like to avoid this headache as best we can.
Additionally, I plead to other developers to own their use of these tools. Please, make Claude a co-author of the commits where Claude has generated any code at the very least. This is the bare minimum. I have strong feelings about the etiquette of sending AI summarised information or LLM-generated code to other people, but before any of that, the decent thing is to remove any uncertainty in the receiving party's mind of how the information they are receiving came to be. In this way, I appreciate the OCaml compiler's AI notice which includes:
If a significant portion of your code, PR description, review comments or messages has been AI-generated, this must be disclosed, stating which tool was used and for what. Reviewing AI-produced code can require a different approach from human-written code. You should have an acknowledgement anyway even if another human contributor did some of the work.
Ppxlib
- March 10, 2026
- Patrick Ferris
We are still in the throes of supporting OCaml 5.5 in ppxlib. Some of the features have proved more complicated to encode into migrations that "roundtrip". Roundtripping, in the context of ppxlib, is when a modern feature of OCaml must be preserved in older abstract syntax trees which may have no specific node to encode them.
Bugs in Ptyp_open
- March 10, 2026
- Patrick Ferris
Unfortunately, Jon Sterling was bitten by this recently. The feature in question was locally opening modules in types (added in OCaml 5.2). For example:
module M = struct
type t = int
end
type t = M.(t list)
Here, the M.(t list) is an example of a new AST node called Ptyp_open. I had hastily not migrated Ptyp_open to older compilers. So what happened? Jon had used this new feature in his project with a 5.3 compiler with ppxlib 0.35. This is before our internal bump to the 5.2 AST so the code migrated all the way down to OCaml 4.14! Whilst passing from 5.2 to 5.1 we raised an error saying:
Error: migration error: module open in types is not supported before OCaml 5.02
The error is confusing (least of all because there is a typo on the OCaml version number). Since then, we have patched this issue and have planned to release a patched 0.35 in the not too distant future.
If you can bump to ppxlib>=0.36 then you will not face this issue.
Modular Explicits
- March 10, 2026
- Patrick Ferris
We ran into a fairly interesting corner of the OCaml language whilst trying to migrate modular explicits in ppxlib. As a recap, in OCaml 5.5 you can now right function types that depend on modules. For example:
module type Add = sig
type t
val add : t -> t -> t
end
let add : (module A : Add) -> A.t -> A.t -> A.t =
fun (module A : Add) a b -> A.add a b
We have to tell the compiler the module type of A by adding : Add. However, there is another very similar syntax for these kinds of constraints, (module A : module Add). And in fact, the former syntax was syntactic sugar for the latter. In OCaml 5.5, these two were distinguished from one another and (module A : Add) is the required syntax for modular explicits. As you might imagine, this is a bit of a headache in terms of ppxlib migrations. In the end, we try to preserve the original intent of the author where possible, and you can read more about it on the PR for distinguishing the two.
Six Month Retrospective
- March 10, 2026
- Patrick Ferris
This month marks the end of six months of work with Tarides. I wrote a small retrospective and plan for my next six months below.
Fellowship Roundup [fellowship-roundup]
- February 9, 2026
- Patrick Ferris
Overview
- February 9, 2026
- Patrick Ferris
February is the final month of my current six-month fellowship work with Tarides. A lot of the work can be summarised by reading the roundups (see October, November, December and January). I have been writing throughout the fellowship. However, they do not quite capture all the work I have been doing.
Below, I pick individual projects and expand on them more holistically rather than pointing at individual PRs or issues.
Ppxlib
- February 9, 2026
- Patrick Ferris
Most of my time over the past six months has been devoted to ppxlib maintenance. A large proportion of this time has been solo development work. Ppxlib is a cornerstone library of the OCaml ecosystem (whether people like it or not).
$ opam list --depends-on=ppxlib --recursive | wc -l 2030
Moreover, it is completely invaluable to Jane Street too. Like other AST-based tools (e.g. ocamlformat, merlin), ppxlib must follow a regular release schedule to support newer compilers. During the years of multicore OCaml development, ppxlib maintenance was a little easier as the Parsetree rarely changed. However, since then, the same cannot be said. Since OCaml 5.2, here are just some of the Parsetree changes:
Functions are represented according to their arity.
Local module opens on types.
Effect syntax.
Modular explicits.
External types.
Locations for all parts of long identifiers.
Labeled tuples.
In a perfect world, each of these require a codec for serialising the feature into ASTs that do not support the feature, plenty of tests and new Ast_builder/Ast_pattern functions for using the feature. Nathan and I have been managing pretty well I would say, though we are not getting any technical debt work done.
Outreachy
- February 9, 2026
- Patrick Ferris
As the OCaml coordinator for Outreachy I have been running the latest December 2025 round. We are lucky to have four projects on the go!
Thibaut Mattio is mentoring two projects: an ML dashboard for Raven and an OxCaml backend for Raven.
Eio
- February 9, 2026
- Patrick Ferris
OxCaml
- February 9, 2026
- Patrick Ferris
I have enjoyed my work on OxCaml went it has happend. I think a few tools have been useful including the try-oxcaml work. David and I also had fun at ICFP discussing some quick experiments related to io_uring and OxCaml.
One road-blocker here is the comparative amount of time spent trying to keep the OxCaml ecosystem working. Given my limited time working on fellowship projects, the rate of change of OxCaml (including the opam ecosystem) meant most of the time was spent making it just work, not exploring or experimenting with the features themselves. I think this has got better in recent months and perhaps jumping back in I would be surprised at the progress that has been made there.
Forester
- February 9, 2026
- Patrick Ferris
Papers
- February 9, 2026
- Patrick Ferris
I had the great fortune of attending ICFP where I presented two talks and was co-author on a few others too.
Reference. Functional Networking for Millions of Docker Desktops (Experience Report) [madhavapeddy2025docker]
- 2025
- Anil Madhavapeddy, David J. Scott, Patrick Ferris, Ryan T. Gibb, Thomas Gazagnaire
- 10.1145/3747525
- https://dl.acm.org/doi/10.1145/3747525
Abstract
- 2025
- Anil Madhavapeddy, David J. Scott, Patrick Ferris, Ryan T. Gibb, Thomas Gazagnaire
Docker is a developer tool used by millions of developers to build, share and run software stacks. The Docker Desktop clients for Mac and Windows have long used a novel combination of virtualisation and OCaml unikernels to seamlessly run Linux containers on these non-Linux hosts. We reflect on a decade of shipping this functional OCaml code into production across hundreds of millions of developer desktops, and discuss the lessons learnt from our experiences in integrating OCaml deeply into the container architecture that now drives much of the global cloud. We conclude by observing just how good a fit for systems programming that the unikernel approach has been, particularly when combined with the OCaml module and type system.
Reference. What we talk about when we talk about scientific programming [ferris2025scientific_programming]
- 2025
- Patrick Ferris
- https://watch.eeg.cl.cam.ac.uk/w/aYXqXLtgQawYMjVXjSQtjx
Abstract
- 2025
- Patrick Ferris
Programming for the planet undoubtedly involves programming scientifically, but what kind of programming are we talking about and what makes it scientific? In what ways does it differ from other forms of programming, if at all? Is scientific programming, data science or machine learning fundamentally different to constructing a compiler or building a high-throughput web server? By considering how the scientific method (with its falsifiable hypotheses and repeatable and reproducible experiments) relates to scientific programming, I hope to explore how computer science and traditional programming techniques are coming up short in meeting the requirements of scientific programmers.
Reference. Generating a corpus of Hazel programs from ill-typed OCaml programs [ferris2025hazel_of_ocaml]
- 2025
- Patrick Ferris, Anil Madhavapeddy
- https://patrick.sirref.org/var/tyde2025.pdf
Abstract
- 2025
- Patrick Ferris, Anil Madhavapeddy
When developing a new programming language, having a large corpus of both correct and incorrect programs allows language designers to test and explore the capabilities of their new language. However, bootstrapping such a corpus of incorrect programs is time-consuming and arduous. We therefore explore how to reuse code from more mature languages to generate a corpus of ill-typed code for newer ones. We have developed a compiler to Hazel, an emerging language with typed holes, from the more mature OCaml ecosystem. We find it practical to generate a comprehensive corpus of ill-typed programs for Hazel development, and discuss future larger scale efforts towards bridging ecosystems.
See also the online hazel of ocaml compiler
Reference. Decomposable Type Highlighting for Bidirectional Type and Cast Systems [carroll2025decomposable_type_highlighting]
- 2025
- Max Carroll, Anil Madhavapeddy, Patrick Ferris
- https://maxcarroll0.github.io/papers/workshops/HATRA-decomposable-type-highlighting/
Abstract
- 2025
- Max Carroll, Anil Madhavapeddy, Patrick Ferris
We explore how to provide programmers with an interactive interface for explaining the process by which static types and dynamic casts are derived, with the goal of improving the debugging of static and dynamic type errors. To this end, we define mathematical foundations for a decomposable highlighting system within a bidirectional system, and show how these can be propagated through dynamic types in a cast system. Our prototype implementation in the gradually typed Hazel language includes a web-based user interface, through which we highlight the importance of type level debugging.
Reference. Yirgacheffe: A Declarative Approach to Geospatial Data [dales2025yirgacheffe]
- 2025
- Michael Winston Dales, Alison Eyres, Patrick Ferris, Francesca A. Ridley, Simon Tarr, Anil Madhavapeddy
- 10.1145/3759536.3763806
- https://dl.acm.org/doi/10.1145/3759536.3763806
Abstract
- 2025
- Michael Winston Dales, Alison Eyres, Patrick Ferris, Francesca A. Ridley, Simon Tarr, Anil Madhavapeddy
We present Yirgacheffe, a declarative geospatial library that allows spatial algorithms to be implemented concisely, supports parallel execution, and avoids common errors by automatically handling data (large geospatial rasters) and resources (cores, memory, GPUs). Our primary user domain comprises ecologists, where a typical problem involves cleaning messy occurrence data, overlaying it over tiled rasters, combining layers, and deriving actionable insights from the results. We describe the successes of this approach towards driving key pipelines related to global biodiversity and describe the capability gaps that remain, hoping to motivate more research into geospatial domain-specific languages.
I had some great conversations with KC too with respect to my current research.
Future Work
- February 9, 2026
- Patrick Ferris
As I enter my final year of the PhD, my goal would be to try and align more of my fellowship work with my own research wherever it makes sense. This research focuses on the following hypothesis:
Embedding deep provenance tracking, reversible execution and mergeable histories directly into an interactive programming environment (a POSIX-like shell) greatly decreases the gap between exploratory scientific work and reproducible, publishable results; all whilst leaving existing workflows intact and being programming language agnostic.
I want to focus on building these tools using Irmin, Eio, OxCaml etc. There are other projects I wish to continue regardless, like Outreachy, though just as a coordinator (not a mentor).
Overlapping PhD Work
- February 9, 2026
- Patrick Ferris
There are multiple projects that overlap with my work. For example, Irmin, which I wrote a retrospective for. This is at the core of Shelter and suggests an extremely valid use case for a brancheable, mergeable database.
In addition to this, continuing to work on Eio makes sense to me too. Eio currently has no maintainer and no active development, but the issues are piling up. In particular, I am making heavy use of Eio in Merry, a POSIX(ish) shell written in OCaml. Aside from research angles on brancheable and mergeable shells, I am also quite interested in how this might look in terms of OxCaml. I met with Anil and Thomas recently to discuss the future of Eio and there was some agreement that we are all heavy users of it and hope to keep up its maintenance and set of features.
One large piece of work that is sorely needed here is moving Eio to bytes and not bigarray-backed Cstructs. Any libraries using bytesrw (e.g. jsont) incur an extra copy of data into and out of the bytes. Anil has been working on some of the pieces recently to make this better!
Maintaining and Releasing my own libraries
- February 9, 2026
- Patrick Ferris
I have published quite a few OCaml libraries in my time, below is just a few libraries (filtered to not include OCurrent projects).
$ opam list --all --no-switch --columns=name,authors: | grep -E "sirref|Ferris" | cut -d " " -f1 carbon geojson geojsone graft hilite ISO3166 jekyll-format ppx_deriving_ezjsonm ppx_deriving_yaml rtree search topojson topojsone cid multibase multicodec multihash multihash-digestif
Some of these are used in the community including hilite, ppx_deriving_yaml and the multi-codecs. I would like to do some general maintenance of some of these tools and release a few iterations of graft which now makes use of bib.
Ppxlib Maintenance
- February 9, 2026
- Patrick Ferris
By far, maintenance of ppxlib takes up a majority of my time. I think, given the other work I need to focus on, it would be great to try to minimise the amount of time working on ppxlib. In particular, perhaps only maintaining ppxlib as far as OCaml release-readiness is a possibility and important bug fixes (like the OOM bug reported by Jane Street).
Forester, Graft and Writing
- February 9, 2026
- Patrick Ferris
With all of this work, I am eager to communicate what I am up to and my thoughts on open source, OCaml, OxCaml etc. I am glad to be using Forester to do this, particularly as it is written in OCaml (and could make great use of my own work on Eio).
I hope to continue working on Graft and related tools like bib. But I would also like to start writing some long-form content similar to the Irmin retrospective.
OCaml Roundup: January 2026 [ocaml-roundup-january-2026]
- February 5, 2026
- Patrick Ferris
A new year, another roundup in my open-source, OCaml activities. This month has been busy with lots of work on ocaml-tiff thanks to Tambe Salome and ppxlib.
Outreachy
- February 5, 2026
- Patrick Ferris
Tambe Salome has been working to add write support to ocaml-tiff; and we are well on the way to having good support. Writing TIFF files is no easy business. Unlike many formats, TIFF files have an internal metadata-data split, with values sometimes being place nowhere near the metadata describing the values in the file. In practice, it means if you do not wish to read the whole file into memory, then your IO layer must support seeking to file offsets. This means when you come to write the file, you might need to write at different offsets too.
This becomes particularly complicated when you do not know ahead of time how you are going to layout the file (e.g. how many strips will the raw data be separated into). For now, we are doing the sane first step and assuming we are copying a TIFF file we have access to but pushing all the copying via the OCaml values we read from our source TIFF. And Salome has made excellent progress:
$ exiftool test/data/uniform.tiff > input.exif $ dune exec -- example/copy.exe test/data/uniform.tiff example.tiff $ exiftool example.tiff > output.exif $ patdiff input.exif output.exif ------ input.exif ++++++ output.exif @|-1,23 +1,23 ============================================================ |ExifTool Version Number : 13.39 -|File Size : 66 kB +|File Size : 118 bytes |File Permissions : -rw-r--r-- |File Type : TIFF |File Type Extension : tif |MIME Type : image/tiff |Exif Byte Order : Little-endian (Intel, II) |Image Width : 256 |Image Height : 256 |Bits Per Sample : 8 |Compression : Uncompressed |Photometric Interpretation : BlackIsZero |Strip Offsets : 122 |Rows Per Strip : 256 |Strip Byte Counts : 65536 |Planar Configuration : Chunky |Image Size : 256x256 |Megapixels : 0.066
From this slightly edited output, we can see that the OCaml libary is doing a good job at preserving the metadata. The file size discrepancy is because we have not tackled writing the raw data to the file yet! This is next on our TODOs, write data to a file given a strip-offset plan. Once we do that we can then start to think how might we come up with such a plan if we did not have one.
Ppxlib
- February 5, 2026
- Patrick Ferris
The first cut of OCaml 5.5 is not too far away, at which point the Parsetree will be frozen. Unfortunately (for ppxlib maintainers), a handful of new features sneaked into this release including: modular explicits, external type declarations and the previously mentioned local structure items.
All of these features require migrations to support newer compilers. In this migration process, ppxlib lowers modern ASTs to the AST of OCaml 5.2. New AST nodes (or new items of exisiting AST nodes) must be encoded to survive the migration process. We have a few PRs to support 5.5 fully:
Additionally, Nathan has been adding better feature encoding support for the 5.3 and 5.4. Unlike the migration code above, these also include Ast_builder and Ast_pattern functions for building and matching on the new AST nodes. This allows ppx authors to use those nodes in their ppxes.
Finally, we have an important bug fix where long identifiers were given a Location.none. Unfortunately, it is not possible to fully recover a long identifier's location because of the possibility of whitespaces (e.g. Foo (M).t is valid). Read more about that fix here.
OCaml Roundup: December 2025 [ocaml-roundup-december-2025]
- January 11, 2026
- Patrick Ferris
December was busy, both personally and in my OCaml-related work. If you haven't been following along have a read of my October and November roundups.
Outreachy December Round [outreachy-december-round]
- January 11, 2026
- Patrick Ferris
December marks the beginning of a new Outreachy round, and I am very excited to be working with Tambe Salome on improving the ocaml-tiff library.
In particular, we will be adding the ability to write TIFF files from raw data. I imagine an API something like:
val write :
('repr, 'kind) Tiff.Data.t ->
Tiff.File.wo ->
unit
So far Salome has been making excellent progress churning through some issues that are blocking us from starting the main project, including:
As a community, the mentors and mentees also had a community call to introduce ourselves to eachother. I am very excited about the Yocaml project and the two Raven projects.
Ppxlib
- January 11, 2026
- Patrick Ferris
If you recall, I discussed the new representation for local constructs in the AST.
Initial OCaml 5.5 Support [ppxlib-5.5-support]
- December 9, 2025
- Patrick Ferris
We recently merged 5.5 support into our main branch (thanks to Nathan for the review). It cast a light on some new features coming to OCaml including the ability to define any structure locally. Most OCaml programmers will be familiar with things like local opens (e.g. let open M in). This has now been extended to include any structure item (more or less, you cannot nest value bindings).
External types have also landed, bringing with them a new "type kind" in the AST. You can read about them in the manual.
It transpires that since then, changes have landed in the compiler that mean just about any OCaml structure item can now be declared locally. I have documented an issue on ppxlib about the problems this will cause for us:
Currently, we only migrate the previously supported structure items that could appear in a let-binding (
let openetc.). Now, however, the compiler allows anything to appear in a local let-binding except additional let-bindings (let let ...) and includes (let include). Whereas the previous change had a 1:1 mapping from a 5.4 AST node to a 5.5 AST node, now we do not and will need to think of a suitable encoding.
Migration Woes
- January 11, 2026
- Patrick Ferris
We had more migration woes in the form of incorrect (or missing) locations for long identifiers (thanks to gasche for the report). Long identifiers, or Longidents are used in OCaml to identify values like Foo.bar or Map.Make(String).t. In OCaml 5.4, each segment of the identifier was given a precise location. This means that in the migration from 5.3 to 5.4 we have to reconstruct those locations.
However, our code didn't do this, instead it simply defaulted to Location.none causing some imprecise error codes in preprocessed OCaml files. For example:
let () = NonExistingModule.run ()
Has the following error:
File "_none_", line 1: Error: Unbound module NonExistingModule
I have proposed a fix which partially brings back locations during the migration. Part of the problem, I think, is that the exact location of long identifiers containing applications (like Map.Make(String).t) is lost. This is because there could be arbitrary white-space in the original source code (e.g. Map.Make (String).t)
OCaml Roundup: November 2025 [ocaml-roundup-november-2025]
- December 9, 2025
- Patrick Ferris
A roundup of some of my OCaml activity this month!
Ppxlib Updates
- December 9, 2025
- Patrick Ferris
I managed to get a substantial amount of ppxlib work completed in the last month. Some of those bits are described in detail below.
Initial OCaml 5.5 Support [ppxlib-5.5-support]
- December 9, 2025
- Patrick Ferris
We recently merged 5.5 support into our main branch (thanks to Nathan for the review). It cast a light on some new features coming to OCaml including the ability to define any structure locally. Most OCaml programmers will be familiar with things like local opens (e.g. let open M in). This has now been extended to include any structure item (more or less, you cannot nest value bindings).
External types have also landed, bringing with them a new "type kind" in the AST. You can read about them in the manual.
Bug Fixes for Attribute Rewriters
- December 9, 2025
- Patrick Ferris
There was a bug in the error handling for attribute rewriters -- a relatively new feature to have been added to ppxlib.
In some places, ppxlib makes use of a With_error.t monad. Unlike the Result.t monad, With_error.t allows you to collect errors rather than find the first error and thread it through your program. This can make sense if your program can meaningfully do work after encountering an error. Unfortunately, in the logic for replacing attributes, the code could not recover from an error where there were duplicate attributes.
Value binding constraints in ppxlib
- December 9, 2025
- Patrick Ferris
I spent a good few hours understanding why the CI tests in my PR to mirage/repr were still failing. It turns out, the bug, is fairly simple to reproduce. Consider the following OCaml code:
let g : int = 1
We have a let-binding that contains a type constraint. Where, in the abstract syntax tree sense, do we attach the constraint? Since OCaml 5.1, we have quite a few options for how this can be represented.
The first is using the Ppat_constraint AST node which allows you to attach a type constraint to any pattern.
| Ppat_constraint of pattern * core_type
(* (P : T)*)
This tends to be used for things like function arguments (e.g. fun (x : int) -> x + 1). So it doesn't quite capture what we want for this binding constraint.
On older OCaml compilers, let g : int = 1 also includes a Pexp_constraint on the body of the value binding. This makes sense if we consider a more general case of the syntax where we allow functions.
let g x : int = x + 1
In this example, we no longer parse a Ppat_constraint and instead this is treated as syntactic sugar for:
let g x = (x + 1 : int)
In OCaml 5.1 a new field for value bindings was added allowing type constraints to be tracked directly in the bindings themselves.
and value_binding =
{
pvb_pat: pattern;
pvb_expr: expression;
pvb_constraint: poly_constraint option;
pvb_attributes: attributes;
pvb_loc: Location.t;
}(** [let pat : type_constraint = exp]*)
Our type constraint (: int) can be recorded in the pvb_constraint directly. This is a nice change, bringing the concrete syntax of the language closer to the parsetree. For ppxlib, however, it does create a bit of a headache as we now have to encode the different versions of expressing type constraints into the AST of the compiler before 5.1!
So what was the bug? The author's of repr had added some value bindings to circumvent some "unused value warnings" in OCaml. They choose to write these bindings like:
let (_ : int) = 1
Here, I have simplified the types and the body of the binding. The significant thing to notice is the parentheses surrounding the value binding's pattern. This forces the AST representation to be a single Ppat_constraint node regardless of the current compiler version. No Pexp_constraint and no pvb_constraint.
However, using ppxlib with a compiler less than 5.1 meant that this did not roundtrip cleanly. Instead, the value after passing through ppxlib's migrations was:
let _ : int = 1
After bottoming out at the issue, I discovered we already had a test case for this in ppxlib! Whatsomore, ocamlformat.0.20.0 (which repr was still using) actually transforms instances of let x : t = ... into let (x : t) = ...! This limitation does not seem inherent to the parsetree, the printer or the migrations. But I have asked the (very kind and friendly) previous maintainers about these changes.
Outreachy
- December 9, 2025
- Patrick Ferris
December 8th 2025 marks the start of the next round of Outreachy. I have been preparing some issues for geocaml/ocaml-tiff and I am excited to get started with Tambe Salome!
Graft and Bib [graft-and-bib-update]
- December 9, 2025
- Patrick Ferris
I spent some time at the start of the month updating and fixing Graft and Bib.
I added named subtrees to the markdown syntax. This allows users to create subtrees with headings that are also externally linkable.
With some more bug fixing, I hope to release both libraries before the new year!
OCaml Roundup: October 2025 [ocaml-roundup-october-2025]
- November 5, 2025
- Patrick Ferris
Welcome to a monthly roundup of OCaml-related open-source work I have been involved with. If you haven't already, a quick look at my ICFP roundup might be a good preface to what follows.
Outreachy December 2025
- November 5, 2025
- Patrick Ferris
The contribution period for this year's Outreachy round took place for most of the month of October. This year I am excited to be going back to a Geocaml project, working primarily to add writing capabilities to ocaml-tiff.
As per usual, I have been extremely pleased with the level of interest in the various OCaml projects being offered. Whilst we are still deliberating on our choices for interns this year, I won't say much more on the contributions, but if you want to get involved please do reach out! OCaml is a great language for geospatial work, striking a balance between reasonable performance for numerical code and also a rich type system for expressing complicated geospatial data-structures.
Ppxlib and the Future of Compiler Support
- November 5, 2025
- Patrick Ferris
Nathan has put a tremendous amount of effort into laying a roadmap this month for how ppxlib, going forward, will support future compilers. This is in response to the calamity that was bumping the internal AST to 5.2, and whilst I think we are adding a good deal more complexity, it will hopefully keep the ppx universe on an even keel for longer periods of time.
The first substantial PR for this modern world of ppxlib is in review!
Aside from that I also debugged an issue that lead to ppxlib OOM-ing machines... of course, any recursive fold-like loop where the accumulator keeps growing is likely to do that! It was nice to be able to crack out memtrace to be able to hunt it down:
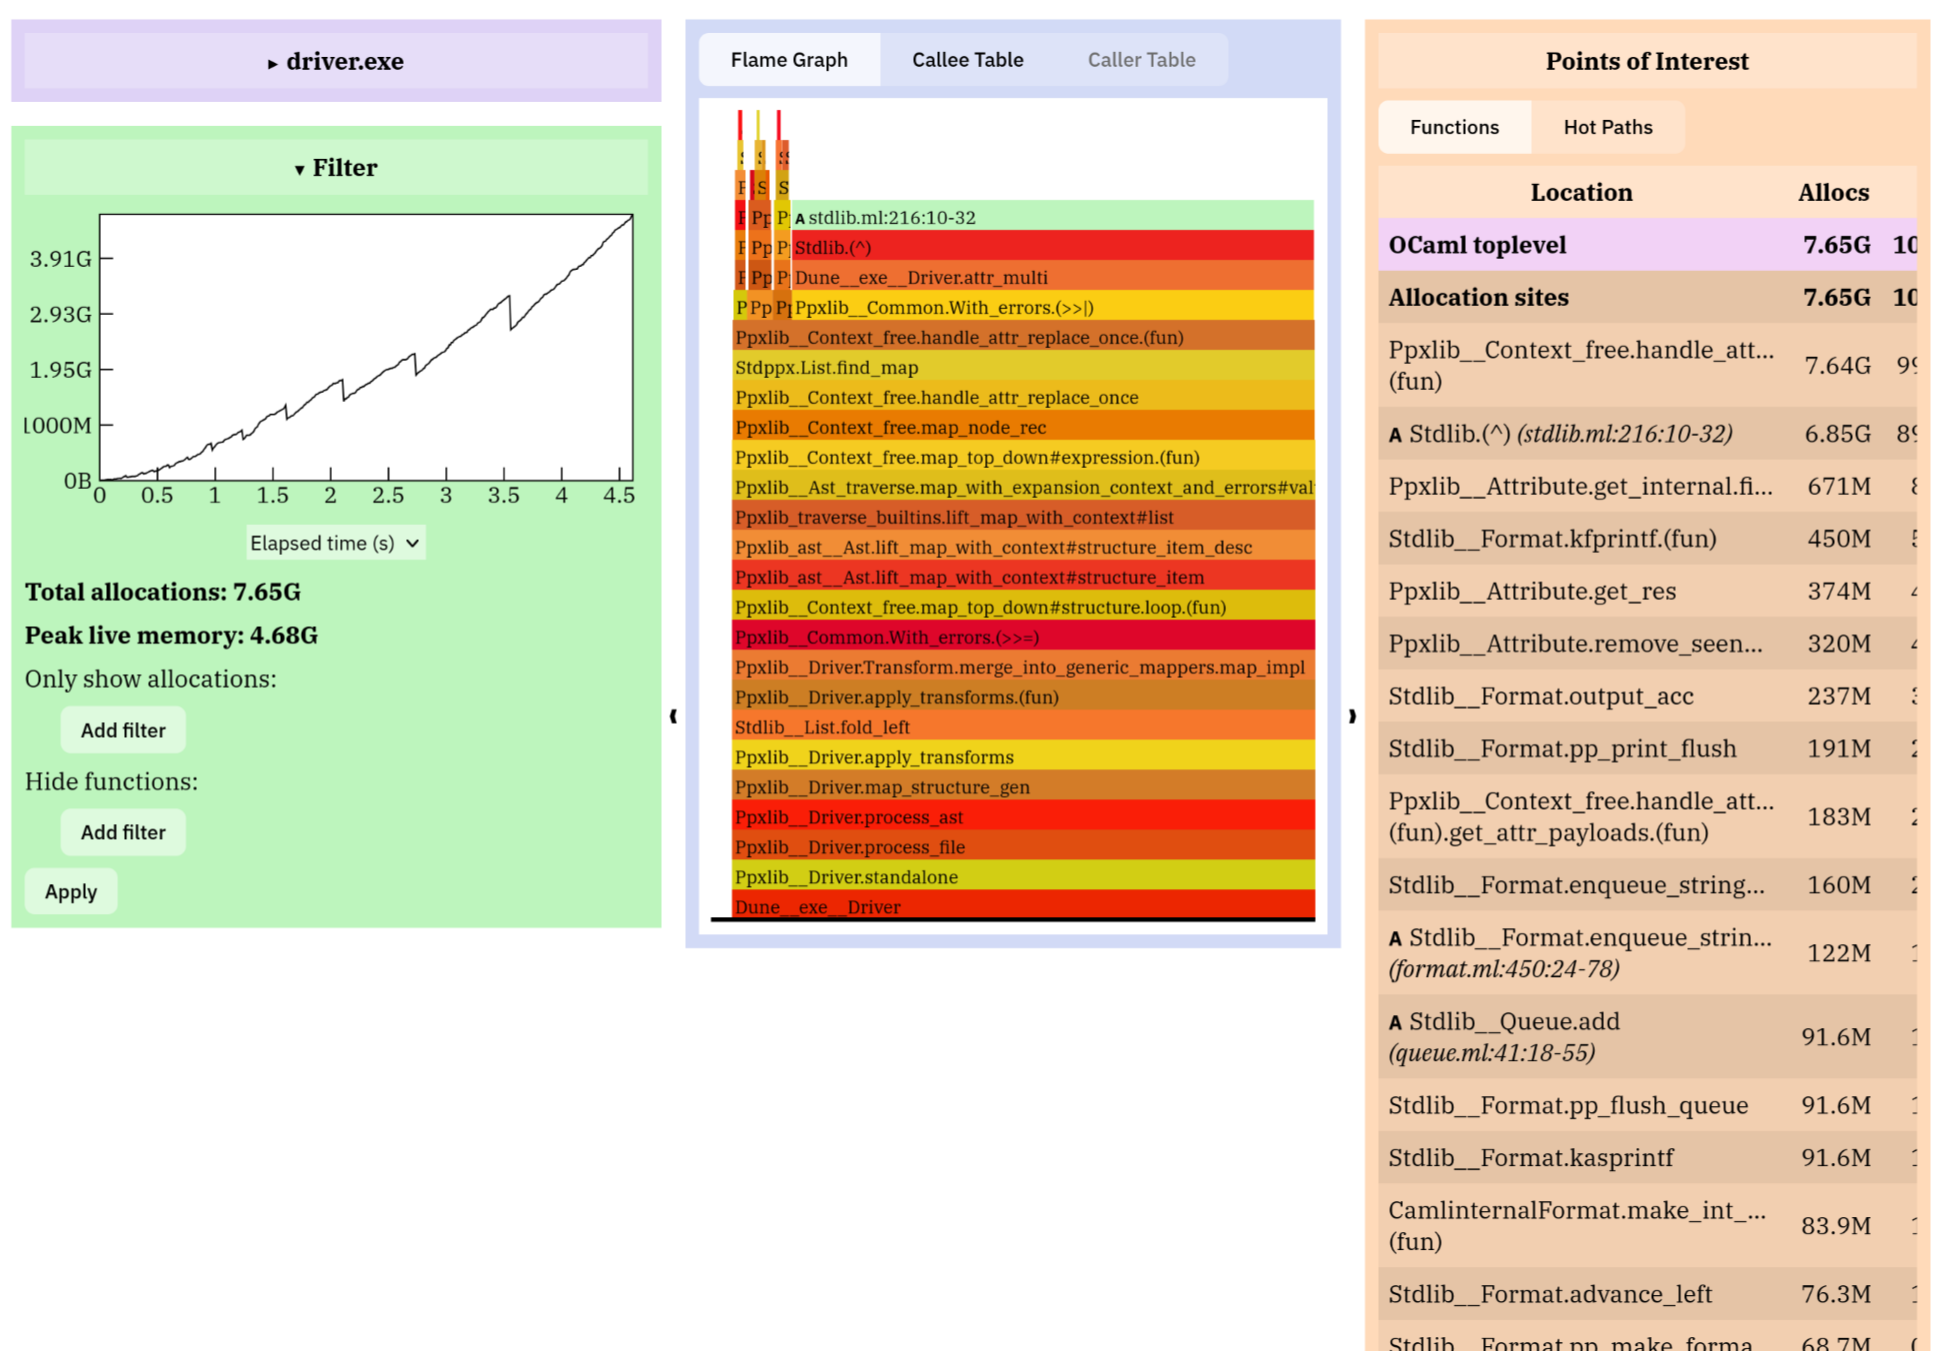
Incremental Directory Reading for Eio
- November 5, 2025
- Patrick Ferris
A common tasks for many a CLI tool is to scan a directory of files, filter out the ones you are looking for and apply some transformation to said files. In fact, that is what Graft and Forester both do! A standard approach to this involves a recursive dance of readdir and stat, the former lists the entries in a directory whilst the latter lets you know what kind of file is at a particular path (e.g. symbolic link, directory etc.). This has a few downsides:
We're making two systems calls (pretty much one of the most expensive things your program can do).
If a directory contains thousands of files, we end up allocating a big list of strings after returning from
readdir.
On Linux, we can get around most of that with getdents64(2) which allows us to incrementally read a directory. Whatsomore, this system call also returns the file type so there's no need to do an extra stat!
I prototyped an implementation of this called Eio.Path.walk which looks like:
val walk : _ t -> ((File.Stat.kind * string) Seq.t -> 'a) -> 'a
(** [walk t] traverses the directory [t] producing a sequence of results.*)
We effectively halve the number of system calls. In a benchmark that traverse deeply-nested directories with plenty of files, a full traversal whent from 1.46s to 110ms. I have since rejigged the implementation to automatically recurse for the user into subdirectories (not that the signature is unchanged) which does make it tricky to control the number of open file descriptors compared to if the user were in control.
OxCaml Experiments [icfp-oxcaml-uring]
- November 5, 2025
- Patrick Ferris
I have included here a transclusion from my ICFP post about an experiment using unboxed 32-bit integers in OCaml's Uring library.
OxCaml and Uring [oxcaml-and-uring]
- Patrick Ferris
Jane Street were a big presence at ICFP 2025, carting along with them a shiny new OCaml compiler: OxCaml. If have been playing around with OxCaml recently but nothing outside toplevels in Javascript. Until now!
After talking to David, I spent some time converting a small corner of the ocaml-uring library to use a part of OxCaml. In particular making the following change:
module Heap = struct
type ptr = int32#
(* ... *)
end
type cqe = {
user_data_id : Heap.ptr;
res : int32#;
}
The idea being that a completion queue entry (a notification that some operation has completed) could be fully represented using 64 bits (two 32-bit, unboxed values). You can see how this impacted the library! I'm not certain about this change (and I'm sure I did it wrong) but it was nice to realise OxCaml gives you this kind of control. However, I am worried about the ergonomics of manipulating values like int32# and the temptation to case it into an int (presumably losing a good portion of the value of having an unboxed value in the first place).
x-ocaml with OxCaml
- November 5, 2025
- Patrick Ferris
I sent a few PRs to the OxCaml repository to get the toplevel working again and lucky the underlying culprit for why patches were disappearing was found. Watch this space for a new toplevel in the browser soon.
Geospatial OCaml
- November 5, 2025
- Patrick Ferris
In addition to the Outreachy work I mentioned above, I also found the time to keep the Geocaml project ticking along. A few projects saw some much-needed love including:
PROJ in OCaml
- November 5, 2025
- Patrick Ferris
A modernisation of the bindings to PROJ. PROJ is probably the most used and tested code for working with geospatial projections. Any time you get a sateillite image or a blob of GeoJSON, the geospatial data will normally have some coordinate reference system (CRS) with it detailing exactly what the numbers that tell you where something is mean. One of the most common being WGS84 (used by GPS and GeoJSON for example). Each CRS has its benefits and drawbacks, and often you will need to convert between them. That is what PROJ does.
WKT in OCaml
- November 5, 2025
- Patrick Ferris
Well-known Text (WKT) is a very simple encoding of geospatial objects and CRSs. For example, a polygon might look like:
Polygon ((10 10, 10 20, 20 20, 20 15, 10 10))
I used bytesrw to build a simple codec for the WKT format. It is probably about time to write the basic geospatial object library too, something similar to Rust's geo library.
Geotessera
- November 5, 2025
- Patrick Ferris
A lot of people in my group are excited about Tessera. They have made it easy to used the Tessera embeddings via a python library called geotessera. In true OCaml-at-heart spirit, I tried my hand at porting this library. I had a good deal of success, converting the data into Nx array, extracting the CRS and transform out of the GeoTIFF landmasks using ocaml-tiff, reading datasets using ocaml-geojson etc. This made me excited but also keen to improve the APIs of most of these libraries too.
I feel geocaml is at a critical mass where we can start to have this useful feedback loop for the libraries because there is enough functionality to actually use them!
OCaml Weekly 2025 w32 to w35 [ocaml-weekly-2025-w32-w35]
- September 2, 2025
- Patrick Ferris
I have been working on a few different OCaml-related projects over the last few weeks. This is also coinciding with my partner and I moving across the UK, which has made finding time to write weeklies and posts a little tricky. Nevertheless, here are some of the things I have been thinking about and working on!
I managed to publish one signficant post this month: a retrospective on Irmin.
Eio
- September 2, 2025
- Patrick Ferris
Increasingly, I'm feeling the dream of a unified framework for asynchronous IO slipping through the OCaml community's fingers. It is perhaps not such a bad thing, and I think with the right library authoring we can at least get to a place where it isn't so bad, for example providing read functions as opposed to using an opinionated IO library directly.
That being said, I am a very happy user of Eio when those choices do not matter, as is the case in building your own application (e.g. Shelter). To this end, I have spent a good bit of time upstreaming support for various missing pieces in Eio's API including:
Setuid and setgid fork action's for the process API.
Set process group support for job control in the process API.
Responding to
Buf_write.of_flowrequest, and tinkering with the example there. I think this does highlight the awkwardness of making code portable across concurrency mechanisms, particularly with Eio's structured concurrency.I did some investigating into
EINTRbug which seems to be stemming from a known-issue on Uring in that writes are not buffered which usually does not matter except perhaps when there are parallel writes tostdout.Spent some time thinking about the fiber local storage across domains issue, I've passed on some thoughts to folks working on this.
Vpnkit
- September 2, 2025
- Patrick Ferris
You might recall I was interested in using vpnkit. Hannes has done an amazing amount of work (patching and releasing) a series of packages to get this into a place that is much better and could be considered soon for merging. This defunctorisation is actually very useful for the Eio port I wrote a long time ago.
Papers and Talks at ICFP
- September 2, 2025
- Patrick Ferris
Somehow, I have ended up on lots of papers and talks at ICFP and the co-located events in October. The vaguely OCaml-related ones include:
Essentially a Vpnkit Experience Report.
An extended abstract on generating a corpus of ill-typed Hazel programs was accepted into TyDe workshop.
Relatedly, the work that project supported was accepted into HATRA which was the Part II project I supervised: Decomposable Type Highlighting for Bidirectional Type and Cast Systems.
And two PROPL talks!
Outreachy
- September 2, 2025
- Patrick Ferris
We have come to the end of another Outreachy round! I will write more on this soon in its own separate post. But for now I am very grateful to this round's mentors gridbugs and mdales, and also our fantastic interns. If you are interested, please do watch our demo day presentations.
The next round is fast approaching and we still need to work out the logistics. But I had a good conversation with mdales about possible Geocaml projects that I intend to submit!
OCaml Weekly 2025 w30 and w31 [ocaml-weekly-2025-w30-w31]
- July 31, 2025
- Patrick Ferris
A bumper edition today, a fortnightly.
Opam Releases
- July 31, 2025
- Patrick Ferris
I did a little personal spring-cleaning of packages I maintain and pushed a few releases to opam. This included a 0.1.0 release of graft! There is some light documentation online at https://graft.sirref.org.
Elsewhere, Hilite got a 0.5.0 release. This release makes the core syntax highlighting separate from the markdown part of the library. You can now generate pairs of tokens and identifiers to plug into any "OCaml sourcecode to format" tool you might be building (e.g. graft!).
Interactive OCaml Presentations
- July 31, 2025
- Patrick Ferris
I had fun trying to fuse slipshow and x-ocaml!
Slipshow x x-ocaml [slipshow-x-xocaml]
- July 23, 2025
A short, explanatory post about combining two very fun pieces of work in OCaml.
Paul-Elliot has been building Slipshow for some time now where slides are slips and your presentations run vertically. More recently, Arthur has built x-ocaml, a web component library for executable OCaml cells embedded into OCaml.
Using xocmd, a small tool I built for translating markdown codeblocks to x-ocaml components, your Slipshow's can now be executable!
xocmd learn-effects.md | slipshow compile - > learn-effects.html
Take a look at an example! (or the source markdown).
I really like this light-weight approach to building interactive presentations for explaining things in OCaml (e.g. over running a jupyter notebook server).
I tried using x-ocaml with Irmin and something is not quite right with some of the runtime JS code being generated (see the issue in case you can help). This was intended to be used alongside a longer-form retrospective I am writing on my use of Irmin over the years.
Outreachy
- July 31, 2025
- Patrick Ferris
I have been helping Michael's intern whilst he has been away on their project Claudius. It has reminded me, again, how inpenetretable some of OCaml's tooling is. In this case the generation of opam files from dune-project files, and in particular, the required manual steps when you wish to remove a dependency (1. remove it from the dune-project file, 2. run dune build to update the opam file, 3. remove all occurences of the library from dune files across your project).
Ppxlib
- July 31, 2025
- Patrick Ferris
Work on Ppxlib has been fairly varied this past two weeks. I mentioned before about an exiting plan Nathan has planned to help ease the burden on ppxlib maintainers and ppx authors whenever there is an OCaml parsetree bump. That, however, is currently shelved as we are dealing with the fall out of the 5.2 bump. Repr got some fixes pushed to it, but this unconvered more issues.
Misc.
- July 31, 2025
- Patrick Ferris
I spent some time cleaning up container-image, a tool primarily written by Thomas G. to fetch OCI images from repositories. The tidy up went surprisingly well, except for some spurious HTTP errors with AWS. Maybe I'll spend some proper time trying to help the state of HTTP clients in OCaml (of which there are many, but few that work very well out of the box in my experience).
OCaml Weekly 2025 w29 [ocaml-weekly-2025-w29]
- July 15, 2025
- Patrick Ferris
Ppxlib
- July 15, 2025
- Patrick Ferris
I met with Nathan this week to discuss future plans for ppxlib. The current state of affairs is that ppxlib is becoming unmaintainable. This is primarily a knock-on effect from changes being made to OCaml's parsetree (e.g. labelled tuples being added in 5.4). Nathan has a plan that will provide two key properties.
Migrations, which allow old compilers to be used with new ppxlib releases, will be more compatible. For example, we will be able to migrate new features downwards and back up without raising an error.
Ppx authors will be able to use new features in an opt-in workflow, rather than ppxlib bumping the internal AST (like we did in ppxlib.0.36.0). This will reduce the maintenance burden significantly whilst still allowing users to write ppxes for new OCaml features.
I also started looking into some older issues in ppxlib related to performance. This is work-in-progress, but I am trying to improve the performance of some passes done by ppxlib. To better understand what was making ppxlib slow, I wanted to use runtime_events_tools but I was dismayed to see it wanting to install over 100 packages! I opened a PR to reduce the number of packages. I think this kind of work goes a little unrecognised as it is not very glamorous. However, I think it really benefits the OCaml community in the long run.
Outreachy
- July 15, 2025
- Patrick Ferris
In Outreachy news, we had a wonderful mid-internship video call with all the interns and mentors to catch-up on how everyone is getting along. Seeing the progress everyone has made was great! I am very grateful for the work that Michael and Steve have put in so far to make this a very successful Outreachy round for OCaml.
In sadder news, an email was shared with all Outreachy mentors detailing the increasingly critical financial situation the project finds itself in. There are ongoing discussions about how costs can be cut including potentially only running a single round a year.
Graft
- July 15, 2025
- Patrick Ferris
With the release of Forester.5.0, I made a plan to make a release of Graft.0.1. Unfortunately this is blocked by a new release of hilite, a tool I built for doing build-time syntax highlighting for OCaml code. This powers the syntax highlighting on ocaml.org.
Teaching [teaching]
I supervise multiple courses in the Department of Computer Science including:
Foundations of Computer Science [focs]
Foundations of Computer Science is a first-year course taught in the Department of Computer Science. It is currently lectured by Anil Madhavapeddy and taught in OCaml.
Discrete Mathematics [discrete-maths]
Discrete Mathematics is a first-year course taught in the Department of Computer Science. It is currently lectured by Jon Sterling.
In addition to this, I supervise multiple final year (Part II) dissertations.
Part II Projects [part-ii]
Part II is the name for third year students studying Computer Science at Cambridge. Over the course of the year, a student is tasked with building a substantial piece of software culminating in a dissertation-style write up at the end. I did this back in 2020, you can read about that here.
Part II Students 2026 [part-ii-2026]
- September 10, 2024
This year I am excited to be the day to day supervisor for three quite different projects. All implemented in OCaml of course!
An Embedded DSL for Querying OpenStreetMap [part-ii-edsl-osm]
- Matthew Occleshaw
This project, originally conceived by Anil Madhavapeddy, hopes to make it easier to answer questions like "What is the safest route to Pembroke College from Cambridge train station?". Here, "safest", can have lots of meanings: the best lit road, a route with tactile paving or accessible pedestrian signals etc.
In addition to this, we may wish to provide suggestions for how to improve the current folksonomy of information OSM stores.
Ripple: An OCaml Library for Incremental Computation [part-ii-incr]
- Boris Hall
Following the work of Adaptive Functional Programming and Implicit self-adjusting computation, this project will build an incremental computation engine in OCaml alongside an expressive combinator library for build such computations. As an extension, a small DSL will be built that makes use of the engine to build an implicitly incremental programming language.
The core of this project is to implement an eDSL and a runtime in OCaml for self-adjusting computation. I also propose a new TDT which allows for generic monoidal folds over modifiable sequences: the library will include a native foldMap primitive that allows performant reduction over a modifiable sequence of modifiable values for any general monoid, giving logarithmic updates with a small trace. I will then compare foldMap to the generic fold implemented in plain SAC.
-- From Boris' Proposal
From OCaml to Graphics Shader Languages [part-ii-shaders]
- Rohan Wadhawan
This project wants to reuse OCaml's typechecker to provide a safe way to create graphics shaders. As an extension, a ppx rewriter will provide a translation layer from OCaml to the embedded DSL making it possible to write shaders in a subset of the OCaml language.
When interacting with the GPU for graphics programming, parts of the rendering pipeline are written as standalone shader programs. The standard method of using these is to store the shader source code as a string, which is then compiled at runtime by the GPU driver. This is not a performance issue, as shader programs are usually small enough that compilation time is negligible. However, it does mean simple syntax errors or incorrect types, which would normally be caught at compilation, won’t manifest until the entire program is run.
I propose a new library, Shaders_of_ocaml, allowing for shader programs to be written inline as native OCaml, which is then compiled to shader code strings to be passed to the existing graphics libraries. This would allow the OCaml compiler to provide type checking for every shader written.
-- From Rohan's Proposal
Part II Students 2024 [part-ii-2024]
- September 10, 2024
In the final year of the Cambridge undergraduate degree in computer science, students undertake a coding project with an accompanying dissertation.
Type Error Debugging in Hazel [part-ii-hazel]
This project will add some features to the Hazel language. Hazel is a functional research language that makes use of gradual types to support unusual features such as: holes (code place-holders) to give type meaning to incomplete programs. Importantly for this project, all Hazel programs, even ill-typed or incomplete programs, are evaluable. This allows dynamic reasoning about ill-typed programs via evaluation traces with the potential to improve the user’s understanding of why ill-typed programs go wrong.
This project aims to exploit further this potential by providing some extra features to both: aid with finding values/inputs that demonstrate why type-errors were found (type-error witnesses) and linking the evaluation traces back to source code.
A Universal Data Access DSL [part-ii-udsl]
The design and implementation of a jq-like EDSL allowing programmers to abstract away the format in which data is stored (YAML, EXIF metadata etc.) and the file system being used – e.g.
open("a/b/[c,d]")could mean "fields c, d in YAML file b of ZIP file a", or it could mean "fields b.c, b.d in JSON file a". My project would statically examine the filesystem to decide which case we're in, giving data scientists an easy way to declare the shape of the data they depend on. Success criteria include projection (correctly reading the data based on the file type), subtyping (e.g. JSON-LD is a child of JSON) and perhaps some compiler optimisations related to parsing (e.g. only loading a JSON library if the file is actually JSON).
Implementing Parallel Algebraic Effect Handlers in OCaml [part-ii-paraeff]
Algebraic effects are becoming increasingly common, but it can be difficult to use them in parallel computations. Xie et al. (2024) present a new structure for effect handlers which allows parallel subcomputations to perform effects independently without synchronisation. I plan to implement the traverse handler in OCaml 5 and evaluate its performance against equivalent programs which do not use effects using a variety of benchmark programs. As extensions, I will devise similar handlers for other types of parallelism, possibly including a more general form which works for many types simultaneously, and investigate how to improve its real-world performance.
Effective Geospatial Code in OCaml [part-ii-geocaml]
This project is co-supervised with Michael Dales.
Geospatial processing is critical in environmental science and is used in a range of environmental scenarios, both in areas of carbon accounting like digital Monitoring, Reporting and Verification in Reforestation Carbon Removal, and also biodiversity analysis like calculating worldwide extinction rates.
However there are problems with the current state of affairs, Python is one of the most popular data science libraries, and when doing geospatial data science with Python you use the GDAL geospatial data library. This workflow is not ideal [2]. For environmental scientists, interacting with the geospatial data in the imperative way that Python requires can be very difficult, and it is also not designed for the scale of computation needed for large geospatial projects. Furthermore, Python’s dynamic type system means that tricky type errors due to heterogeneity of data points can go unchecked. GDAL also only allows synchronous IO for loading GeoTIFF files, which can hurt performance.
I will write a non-blocking library for reading GeoTIFF files in OCaml (built on top of the WIP OCaml-TIFF library1 written by one of my supervisors, Patrick Ferris). I will then use OCaml to write an embedded Domain Specific Language (eDSL) which will be used to interact with geospatial data in a declarative way.
Part II Students 2023 [part-ii-2023]
- September 10, 2023
In the final year of the Cambridge undergraduate degree in computer science, students undertake a coding project with an accompanying dissertation.
A DSL for Decentralised Identity in OCaml [part-ii-dslid]
This project was completed by Michał Mgeładze-Arciuch and supervised by Anil Madhavapeddy and Patrick Ferris.
Publications [publications]
Various talks, papers and preprints.
Published
Conference Papers
Reference. Package Managers à la Carte [pkg-calc2026gibb]
- 2026
- Ryan T. Gibb, Patrick Ferris, David Allsopp, Thomas Gazagnaire, Anil Madhavapeddy
- 10.1145/3828699
- https://doi.org/10.1145/3828699
Abstract
- 2026
- Ryan T. Gibb, Patrick Ferris, David Allsopp, Thomas Gazagnaire, Anil Madhavapeddy
Package managers are legion. Every programming language and operating system has its own solution, each with subtly different semantics for dependency resolution. This fragmentation prevents multilingual projects from expressing precise dependencies across language ecosystems; it leaves external system dependencies implicit and unversioned; and it obscures the full dependency graph that supply-chain analysis depends on. We present the Package Calculus, a formalism for dependency resolution that unifies the core semantics of package managers. Through a series of formal reductions, we show how this core is expressive enough to model the diversity of real-world dependency expression languages. The calculus provides the theoretical foundation for future cross-ecosystem tooling, as a lingua franca of dependency expression.
Reference. Functional Networking for Millions of Docker Desktops (Experience Report) [madhavapeddy2025docker]
- 2025
- Anil Madhavapeddy, David J. Scott, Patrick Ferris, Ryan T. Gibb, Thomas Gazagnaire
- 10.1145/3747525
- https://dl.acm.org/doi/10.1145/3747525
Abstract
- 2025
- Anil Madhavapeddy, David J. Scott, Patrick Ferris, Ryan T. Gibb, Thomas Gazagnaire
Docker is a developer tool used by millions of developers to build, share and run software stacks. The Docker Desktop clients for Mac and Windows have long used a novel combination of virtualisation and OCaml unikernels to seamlessly run Linux containers on these non-Linux hosts. We reflect on a decade of shipping this functional OCaml code into production across hundreds of millions of developer desktops, and discuss the lessons learnt from our experiences in integrating OCaml deeply into the container architecture that now drives much of the global cloud. We conclude by observing just how good a fit for systems programming that the unikernel approach has been, particularly when combined with the OCaml module and type system.
Workshop Papers
Reference. Generating a corpus of Hazel programs from ill-typed OCaml programs [ferris2025hazel_of_ocaml]
- 2025
- Patrick Ferris, Anil Madhavapeddy
- https://patrick.sirref.org/var/tyde2025.pdf
Abstract
- 2025
- Patrick Ferris, Anil Madhavapeddy
When developing a new programming language, having a large corpus of both correct and incorrect programs allows language designers to test and explore the capabilities of their new language. However, bootstrapping such a corpus of incorrect programs is time-consuming and arduous. We therefore explore how to reuse code from more mature languages to generate a corpus of ill-typed code for newer ones. We have developed a compiler to Hazel, an emerging language with typed holes, from the more mature OCaml ecosystem. We find it practical to generate a comprehensive corpus of ill-typed programs for Hazel development, and discuss future larger scale efforts towards bridging ecosystems.
Reference. Decomposable Type Highlighting for Bidirectional Type and Cast Systems [carroll2025decomposable_type_highlighting]
- 2025
- Max Carroll, Anil Madhavapeddy, Patrick Ferris
- https://maxcarroll0.github.io/papers/workshops/HATRA-decomposable-type-highlighting/
Abstract
- 2025
- Max Carroll, Anil Madhavapeddy, Patrick Ferris
We explore how to provide programmers with an interactive interface for explaining the process by which static types and dynamic casts are derived, with the goal of improving the debugging of static and dynamic type errors. To this end, we define mathematical foundations for a decomposable highlighting system within a bidirectional system, and show how these can be propagated through dynamic types in a cast system. Our prototype implementation in the gradually typed Hazel language includes a web-based user interface, through which we highlight the importance of type level debugging.
Reference. Yirgacheffe: A Declarative Approach to Geospatial Data [dales2025yirgacheffe]
- 2025
- Michael Winston Dales, Alison Eyres, Patrick Ferris, Francesca A. Ridley, Simon Tarr, Anil Madhavapeddy
- 10.1145/3759536.3763806
- https://dl.acm.org/doi/10.1145/3759536.3763806
Abstract
- 2025
- Michael Winston Dales, Alison Eyres, Patrick Ferris, Francesca A. Ridley, Simon Tarr, Anil Madhavapeddy
We present Yirgacheffe, a declarative geospatial library that allows spatial algorithms to be implemented concisely, supports parallel execution, and avoids common errors by automatically handling data (large geospatial rasters) and resources (cores, memory, GPUs). Our primary user domain comprises ecologists, where a typical problem involves cleaning messy occurrence data, overlaying it over tiled rasters, combining layers, and deriving actionable insights from the results. We describe the successes of this approach towards driving key pipelines related to global biodiversity and describe the capability gaps that remain, hoping to motivate more research into geospatial domain-specific languages.
Reference. Modularizing Reasoning about AI Capabilities via Abstract Dijkstra Monads [omar2024bastion]
- 2024
- Cyrus Omar, Patrick Ferris, Anil Madhavapeddy
- https://icfp24.sigplan.org/home/hope-2024
Abstract
- 2024
- Cyrus Omar, Patrick Ferris, Anil Madhavapeddy
The proposed talk will outline the vision for a recently originated research project aiming to build a formally verified prototype of a foundational "operating system" for safeguarded AI, called Bastion, that grounds these activities within programming language theory, namely by combining dependent type theory (as a practical general-purpose theory of computational structures and proofs), Dijkstra monads (as a flexible formalism for reasoning about an AI agent's computational effects), and abstract types (for modularizing reasoningto individual components that can be separately developed by various stakeholders, including AI safety researchers, formal methods experts, organizations of various scales, and governments seeking to develop actionable, specific policy).
Reference. Carbon-Aware Name Resolution [gibb2024carbonaware]
- 2024
- Ryan Gibb, Patrick Ferris, Anil Madhavapeddy
- https://www.sicsa.ac.uk/wp-content/uploads/2024/11/LOCO2024_paper_28.pdf
Abstract
- 2024
- Ryan Gibb, Patrick Ferris, Anil Madhavapeddy
The current Internet architecture fails to treat the carbon emissions associated with networked services as a first-class metric. We propose extending the DNS with load balancing techniques to consider the carbon cost of scheduling decisions, and further to actively wake machines running networked services as a side effect of name resolution. By extending the DNS, we maintain compatibility with existing Internet infrastructure, unlocking the ability for existing applications to be carbon-aware.
Reference. Lineage first computing: towards a frugal userspace for Linux [dales2024frugallinux]
- 2024
- Michael Dales, Patrick Ferris, Anil Madhavapeddy
- https://www.sicsa.ac.uk/wp-content/uploads/2024/11/LOCO2024_paper_30.pdf
Abstract
- 2024
- Michael Dales, Patrick Ferris, Anil Madhavapeddy
Data-science is a vital tool in tackling the ongoing climate crisis, but it is one that has a significant cost to it also, in terms of energy used during execution and in terms of significant hardware investment required to run it. These are then amplified considerably in the exploratory nature of scientific research.We argue this is because the affordances of the operating system, particularly filesystems, make little effort to support reuse of computed artifacts directly or promote reuse through trusted lineage data. However, it turns out that many of the userspace interfaces exposed by the Linux kernel entirely support a radically more efficient -- a more frugal -- model of computation than is currently the default. In this talk, we explore a new OS architecture which defaults to deterministic, reusable computation with the careful recording of side effects. This in turn allows the OS to guide complex computations towards previously acquired intermediate results, but still allowing for recomputation when required. We use these interfaces to build a new Linux userspace where we put the workflow graph-containing relationships between tools, provenance and labelling-as the core of a system that drives how processes, data, and users interact. Our prototype shell, dubbed Shark, is a data-science first operating environment that is designed to both ensure efficient use of computation and storage resources, and to make it easy for non-experts to create pipeline descriptions from end results post-hoc. It does this by making the lineage graph of a data-pipeline the key concept that ties everything else together: by tracking how the data-pipeline evolves from experimental practice, and tracking what data has already been built and what hasn't we can prevent re-execution both at development and after publication.
Reference. Emission Impossible: privacy-preserving carbon emissions claims [man2024emissionimpossible]
- 2024
- Jessica Man, Sadiq Jaffer, Patrick Ferris, Martin Kleppmann, Anil Madhavapeddy
- https://www.sicsa.ac.uk/wp-content/uploads/2024/11/LOCO2024_paper_35.pdf
Abstract
- 2024
- Jessica Man, Sadiq Jaffer, Patrick Ferris, Martin Kleppmann, Anil Madhavapeddy
In this talk we will explore: (i) how the conflicting incentives around carbon emissions reporting make existing systems unlikely to succeed; and (ii) how we could use ZKPs to allow for the accurate reporting of carbon claims without compromising on individual privacy and competitiveness requirements.
Reference. Eio 1.0-effects-based IO for OCaml 5 [leonard2023eio]
Abstract
- 2023
- Thomas Leonard, Patrick Ferris, Christiano Haesbaert, Lucas Pluvinage, Vesa Karvonen, Sudha Parimala, K Sivaramakrishnan, Vincent Balat, Anil Madhavapeddy
Eio provides an effects-based direct-style IO stack for OCaml 5. This talk introduces Eio's main features, such as use of effects, multicore support and lock-free data-structures, support for modular programming, interoperability with other concurrency libraries such as Lwt, Async and Domainslib, and interactive monitoring support enabled by the custom runtime events in OCaml 5.1. We will report on our experiences porting existing applications to Eio.
Reference. Continuous Monitoring of OCaml Applications using Runtime Events [jaffer2022runtimeevents]
- 2022
- Sadiq Jaffer, Patrick Ferris
- https://icfp22.sigplan.org/details/ocaml-2022-papers/7/Continuous-Monitoring-of-OCaml-Applications-using-Runtime-Events
Abstract
- 2022
- Sadiq Jaffer, Patrick Ferris
The upcoming 5.0 release of OCaml includes a new runtime tracing system designed for continuous monitoring of OCaml applications called Runtime Events. It enables very low overhead, programmatic access to performance data emitted by the OCaml runtime and garbage collector. This talk focuses on the implementation of Runtime Events and the user experience of writing applications exploiting this new feature.
Misc.
Reference. What we talk about when we talk about scientific programming [ferris2025scientific_programming]
- 2025
- Patrick Ferris
- https://watch.eeg.cl.cam.ac.uk/w/aYXqXLtgQawYMjVXjSQtjx
Abstract
- 2025
- Patrick Ferris
Programming for the planet undoubtedly involves programming scientifically, but what kind of programming are we talking about and what makes it scientific? In what ways does it differ from other forms of programming, if at all? Is scientific programming, data science or machine learning fundamentally different to constructing a compiler or building a high-throughput web server? By considering how the scientific method (with its falsifiable hypotheses and repeatable and reproducible experiments) relates to scientific programming, I hope to explore how computer science and traditional programming techniques are coming up short in meeting the requirements of scientific programmers.
Reference. Global, robust and comparable digital carbon assets [jaffer2024global]
- 2024
- Sadiq Jaffer, Michael Dales, Patrick Ferris, Derek Sorensen, Thomas Swinfield, Robin Message, Srinivasan Keshav, Anil Madhavapeddy
- 10.1109/ICBC59979.2024.10634343
Abstract
- 2024
- Sadiq Jaffer, Michael Dales, Patrick Ferris, Derek Sorensen, Thomas Swinfield, Robin Message, Srinivasan Keshav, Anil Madhavapeddy
Carbon credits purchased in the voluntary carbon market allow unavoidable emissions, such as international flights for essential travel, to be offset by an equivalent climate benefit, such as avoiding emissions from tropical deforestation. However, many concerns regarding the credibility of these offsetting claims have been raised. Moreover, the credit market is manual, therefore inefficient and unscalable, and non-fungible, therefore illiquid. To address these issues, we propose an efficient digital methodology that combines remote sensing data, modern econometric techniques, and on-chain certification and trading to create a new digital carbon asset (the PACT stablecoin) against which carbon offsetting claims can be transparently verified. PACT stablecoins are produced as outputs from a reproducible computational pipeline for estimating the climate benefits of carbon offset projects that not only quantifies the CO2 emissions involved, but also allows for similar credits to be pooled based on their co-benefits such as biodiversity and jurisdictional attributes, increasing liquidity through fungibility within pools. We implement and evaluate the PACT carbon stablecoin on the Tezos blockchain, which is designed to facilitate low-cost transactions while minimizing environmental impact. Our implementation includes a contract for a registry for tracking issuance, ownership, and retirement of credits, and a custodian contract to bridge on-chain and off-chain transactions. Our work brings scale and trust to the voluntary carbon market by providing a transparent, scalable, and efficient framework for high-integrity carbon credit transactions.
Preprints
Reference. Planetary computing for data-driven environmental policy-making [ferris2023planetary]
- 2023
- Patrick Ferris, Michael Dales, Sadiq Jaffer, Amelia Holcomb, Eleanor Scott, Thomas Swinfield, Alison Eyres, Andrew Balmford, David Coomes, Srinivasan Keshav, Anil Madhavapeddy
- 10.48550/arXiv.2303.04501
Abstract
- 2023
- Patrick Ferris, Michael Dales, Sadiq Jaffer, Amelia Holcomb, Eleanor Scott, Thomas Swinfield, Alison Eyres, Andrew Balmford, David Coomes, Srinivasan Keshav, Anil Madhavapeddy
We make a case for planetary computing -- infrastructure to handle the ingestion, transformation, analysis and publication of global data products for furthering environmental science and enabling better informed policy-making. We draw on our experiences as a team of computer scientists working with environmental scientists on forest carbon and biodiversity preservation, and classify existing solutions by their flexibility in scalably processing geospatial data, and also how well they support building trust in the results via traceability and reproducibility. We identify research gaps in the intersection of computing and environmental science around how to handle continuously changing datasets that are often collected across decades and require careful access control rather than being fully open access.
Reference. PACT Tropical Moist Forest Accreditation Methodology v2.0 [balmford2023pact]
- 2023
- Andrew Balmford, David Coomes, Michael Dales, Patrick Ferris, James Hartup, Sadiq Jaffer, Srinivasan Keshav, Miranda Lam, Anil Madhavapeddy, Robin Message
- 10.33774/coe-2023-g584d-v5
Abstract
- 2023
- Andrew Balmford, David Coomes, Michael Dales, Patrick Ferris, James Hartup, Sadiq Jaffer, Srinivasan Keshav, Miranda Lam, Anil Madhavapeddy, Robin Message
This draft document describes the methodology developed by the Cambridge Center for Carbon Credits (4C) for estimating the number of credits to be issued to a project in the tropical moist forest (TMF) biome. It expands on the methodology outlined in (Swinfield and Balmford, 2023). We welcome comments and suggestions in the associated online document at https://tinyurl.com/cowgreport.